mirror of
https://github.com/GoogleCloudPlatform/vertex-ai-samples.git
synced 2026-09-26 14:42:04 +00:00
Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 Vertex MG TeamandCopybara-Service |
85c649dd26 | ||
|
Vertex MG TeamandCopybara-Service
|
b7135ae1f0 | ||
|
Vertex MG TeamandCopybara-Service
|
2f5119a266 | ||
|
Vertex MG TeamandCopybara-Service
|
23e64ca76f | ||
|
gurusai-voletiandGitHub
|
0ba5a62cc9 | ||
|
Damodar PanigrahiandGitHub
|
0be2c6fd0c | ||
|
Vertex MG TeamandCopybara-Service
|
cef4928c49 | ||
|
Vertex MG TeamandCopybara-Service
|
9bb8107110 | ||
|
Vertex MG TeamandCopybara-Service
|
b075990d88 | ||
|
Ravi DalalGitHubgemini-code-assist[bot] <176961590+gemini-code-assist[bot]@users.noreply.github.com>gemini-code-assist[bot] <176961590+gemini-code-assist[bot]@users.noreply.github.com> |
6a83c4c695 | ||
|
Damodar PanigrahiGitHubgemini-code-assist[bot] <176961590+gemini-code-assist[bot]@users.noreply.github.com>gemini-code-assist[bot] <176961590+gemini-code-assist[bot]@users.noreply.github.com>gemini-code-assist[bot] <176961590+gemini-code-assist[bot]@users.noreply.github.com> |
820c0f8db4 | ||
|
Damodar PanigrahiGitHubgemini-code-assist[bot] <176961590+gemini-code-assist[bot]@users.noreply.github.com>gemini-code-assist[bot] <176961590+gemini-code-assist[bot]@users.noreply.github.com>gemini-code-assist[bot] <176961590+gemini-code-assist[bot]@users.noreply.github.com>gemini-code-assist[bot] <176961590+gemini-code-assist[bot]@users.noreply.github.com>gemini-code-assist[bot] <176961590+gemini-code-assist[bot]@users.noreply.github.com>gemini-code-assist[bot] <176961590+gemini-code-assist[bot]@users.noreply.github.com>gemini-code-assist[bot] <176961590+gemini-code-assist[bot]@users.noreply.github.com> |
4ab197a4ba | ||
|
Damodar PanigrahiandGitHub
|
2a5877fbd1 | ||
|
Vertex MG TeamandCopybara-Service
|
090e1d9fee | ||
|
Eric DongandGitHub
|
2e049d4830 | ||
|
Vertex MG TeamandCopybara-Service
|
e3320d2126 | ||
|
Vertex MG TeamandCopybara-Service
|
5fc0e03ca3 | ||
|
Vertex MG TeamandCopybara-Service
|
ff2a16237d | ||
|
Vertex MG TeamandCopybara-Service
|
d26f081642 | ||
|
Vertex MG TeamandCopybara-Service
|
8a0a39176c | ||
|
Vertex MG TeamandCopybara-Service
|
646532ea69 | ||
|
Vertex MG TeamandCopybara-Service
|
9e96a3da67 | ||
|
Vertex MG TeamandCopybara-Service
|
db34e1fbd5 | ||
|
Sam-DecigaandGitHub
|
82308acbac | ||
|
Vertex MG TeamandCopybara-Service
|
ee0ba75d1e | ||
|
Vertex MG TeamandCopybara-Service
|
d61aedc721 | ||
|
Vertex MG TeamandCopybara-Service
|
19f7f94af5 | ||
|
Vertex MG TeamandCopybara-Service
|
4e5ce9b226 | ||
|
Vertex MG TeamandCopybara-Service
|
99938244f4 | ||
|
Vertex MG TeamandCopybara-Service
|
0cc7be4a6a | ||
|
Vertex MG TeamandCopybara-Service
|
b6bde41850 | ||
|
Vertex MG TeamandCopybara-Service
|
52444a0933 | ||
|
Vertex MG TeamandCopybara-Service
|
bab9c398fd | ||
|
Vertex MG TeamandCopybara-Service
|
447affcc93 | ||
|
Bhaskar GoyalandGitHub
|
6132c37be0 | ||
|
Vertex MG TeamandCopybara-Service
|
8d7f59aeec | ||
|
Vertex MG TeamandCopybara-Service
|
bd327ad424 | ||
|
Vertex MG TeamandCopybara-Service
|
3b1fbdb382 | ||
|
Vertex MG TeamandCopybara-Service
|
954043a729 | ||
|
Vertex MG TeamandCopybara-Service
|
16ef9ee80e | ||
|
Bhaskar GoyalandGitHub
|
79301b4a4d | ||
|
Vertex MG TeamandCopybara-Service
|
0b38d02e6f | ||
|
kthytangandGitHub
|
c52ff25ba4 | ||
|
Vertex MG TeamandCopybara-Service
|
424400bace | ||
|
Mend RenovateandGitHub
|
b1dfac2043 | ||
|
Mend RenovateandGitHub
|
b81ffcddab | ||
|
Mend RenovateandGitHub
|
21d8f144aa | ||
|
Vertex MG TeamandCopybara-Service
|
065a674305 | ||
|
haomengchaoandGitHub
|
571d498d08 | ||
|
Bhaskar GoyalandGitHub
|
e936882123 | ||
|
Vertex MG TeamandCopybara-Service
|
f754f99052 | ||
|
Vertex MG TeamandCopybara-Service
|
aa5523a5e9 | ||
|
Vertex MG TeamandCopybara-Service
|
81393ede1a | ||
|
Vertex MG TeamandCopybara-Service
|
5a1c0222da | ||
|
Vertex MG TeamandCopybara-Service
|
1f9326bd56 | ||
|
Vertex MG TeamandCopybara-Service
|
a94cae2e79 | ||
|
kthytangandGitHub
|
cb861713c8 | ||
|
|
3a55087789 | ||
|
Vertex MG TeamandCopybara-Service
|
d359b21f3e | ||
|
Vertex MG TeamandCopybara-Service
|
c7d4123b25 | ||
|
Vertex MG TeamandCopybara-Service
|
07a8bb2d0c | ||
|
Vertex MG TeamandCopybara-Service
|
f6b6f365b6 | ||
|
Vertex MG TeamandCopybara-Service
|
fec825f9e5 | ||
|
Vertex MG TeamandCopybara-Service
|
1e9bf72097 | ||
|
Vertex MG TeamandCopybara-Service
|
3fa1cf99ec | ||
|
Vertex MG TeamandCopybara-Service
|
2bcaf8abde | ||
|
Vertex MG TeamandCopybara-Service
|
759495a1f8 | ||
|
Vertex MG TeamandCopybara-Service
|
9925e62c4b | ||
|
Vertex MG TeamandCopybara-Service
|
40ade71b35 | ||
|
Vertex MG TeamandCopybara-Service
|
65173071a5 | ||
|
Vertex MG TeamandCopybara-Service
|
a514bb51c2 | ||
|
Rayan DasoriyaandCopybara-Service
|
a6dc1b0f6d | ||
|
|
75236998c7 | ||
|
MarkandGitHub
|
9c8a7808bf | ||
|
Holt SkinnerandGitHub
|
86ce1576d2 | ||
|
Holt Skinner
|
c2b743bfeb | ||
|
Vertex MG TeamandCopybara-Service
|
b04575d746 | ||
|
Vertex MG TeamandCopybara-Service
|
b90d16885e | ||
|
Holt SkinnerandGitHub
|
828f1a26fa | ||
|
Holt SkinnerandGitHub
|
915e5edf0a |
@@ -7,9 +7,9 @@ jobs:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@v5
|
||||
uses: actions/setup-python@v6
|
||||
with:
|
||||
python-version: '3.x'
|
||||
python-version: '3.13'
|
||||
- name: Fetch pull request branch
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
|
||||
@@ -4,7 +4,7 @@
|
||||
# 2. To lint specific notebooks:
|
||||
# docker run -v ${PWD}:/setup/app gcr.io/python-docs-samples-tests/notebook_linter:latest notebooks/1.ipynb notebooks/2.ipynb
|
||||
|
||||
FROM python:3.13
|
||||
FROM python:3.14
|
||||
|
||||
WORKDIR setup
|
||||
|
||||
|
||||
@@ -3,7 +3,7 @@ ipython
|
||||
jupyter
|
||||
nbconvert
|
||||
black==25.1.0
|
||||
pyupgrade==3.20.0
|
||||
pyupgrade==3.21.0
|
||||
isort==6.0.1
|
||||
flake8==7.3.0
|
||||
nbqa==1.9.1
|
||||
|
||||
+1
-1
@@ -1,3 +1,3 @@
|
||||
torch==2.2.0
|
||||
torch==2.8.0
|
||||
torchvision==0.9.1
|
||||
tensorboard==2.5.0
|
||||
+1
-1
@@ -45,5 +45,5 @@ six==1.17.0
|
||||
sniffio==1.3.1
|
||||
typing-inspection==0.4.0
|
||||
typing_extensions==4.13.2
|
||||
urllib3==2.4.0
|
||||
urllib3==2.5.0
|
||||
websockets==15.0.1
|
||||
@@ -26,6 +26,7 @@
|
||||
/vertex_endpoints/find_ideal_machine_type/find_ideal_machine_type/find_ideal_machine_type.ipynb @entrpn
|
||||
/vertex_endpoints/nvidia-triton/nvidia-triton-custom-container-prediction.ipynb @RajeshThallam
|
||||
/vertex_endpoints/optimized_tensorflow_runtime @vlasenkoalexey
|
||||
/notebooks/community/alphagenome/cloudai_alphagenome_vai_quickstart.ipynb @dpanigra
|
||||
/notebooks/community/ml_ops/stage2/get_started_with_visionapi_and_automl.ipynb @mansari
|
||||
/notebooks/community/neo4j/graph_paysim.ipynb @benofben @laeg
|
||||
/notebooks/community/ml_ops/stage1/get_started_with_visionapi_and_vertex_datasets.ipynb @mansari
|
||||
|
||||
@@ -0,0 +1,93 @@
|
||||
|
||||
|
||||
# AlphaGenome
|
||||
[**Overview**](#overview) | [**Use Cases**](#use-cases) | [**Documentation**](#documentation) | [**Pricing**](#pricing) | [**Quick start**](#quick-start)
|
||||
|
||||
## Overview
|
||||
**Disclaimer:** *Experimental*.
|
||||
|
||||
*The AlphaGenome Private Preview is a "Pre-GA Offering" subject to the "Pre-GA
|
||||
Offerings Terms" in the General Service Terms section of the Google Cloud
|
||||
[Service Specific Terms](https://cloud.google.com/terms/service-terms). It is
|
||||
also a “Generative AI Preview Product” as defined in and subject to the
|
||||
[Additional Terms for Generative AI Preview Products](https://cloud.google.com/trustedtester/aitos?e=48754805&hl=en).
|
||||
Pre-GA products are available "as is" and might have limited support. For more
|
||||
information, see the [launch stage](https://cloud.google.com/products?e=48754805#product-launch-stages)
|
||||
descriptions.*
|
||||
|
||||
Access to the AlphaGenome model capabilities requires application and approval.
|
||||
Users must be added to an allowlist to use the service.
|
||||
If you are interested in applying to the program, **Request Access** above.
|
||||
|
||||
|
||||
|
||||
AlphaGenome is Google DeepMind’s unifying model for deciphering the regulatory
|
||||
code within DNA sequences.
|
||||
|
||||
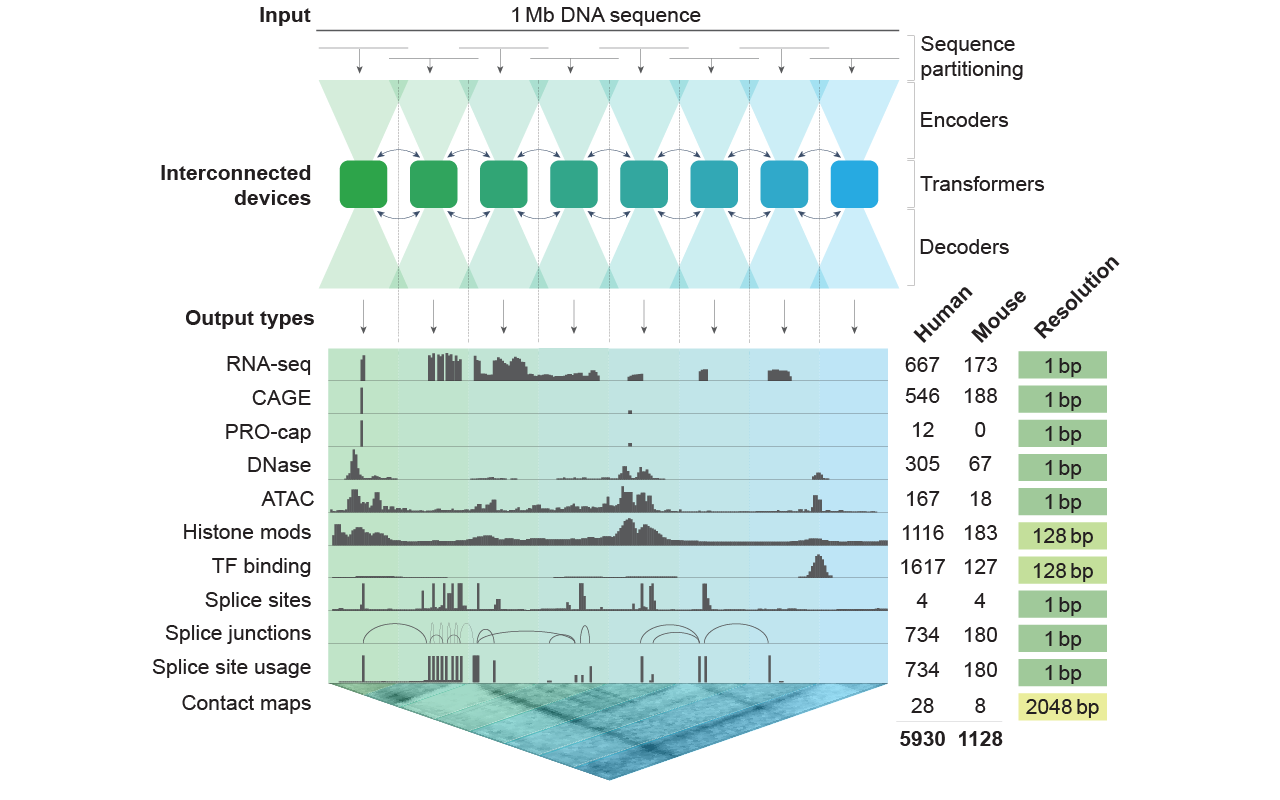
AlphaGenome offers multimodal predictions, encompassing diverse functional
|
||||
outputs such as gene expression, splicing patterns, chromatin features, and
|
||||
contact maps (see diagram below). The model analyzes DNA sequences of up to 1
|
||||
million base pairs in length and can deliver predictions at single base-pair
|
||||
resolution for most outputs.
|
||||
|
||||
Training data was sourced from large public consortia including
|
||||
[ENCODE](http://encodeproject.org/), [GTEx](https://www.gtexportal.org/),
|
||||
[4D Nucleome](https://4dnucleome.org/) and
|
||||
[FANTOM5](https://fantom.gsc.riken.jp/5/), which experimentally measured these
|
||||
properties covering important modalities of gene regulation across hundreds of
|
||||
human and mouse cell types and tissues.
|
||||
|
||||
|
||||
|
||||
## Use Cases
|
||||
* **Sequence-to-function predictions:** Predict multiple functional tracks (such as gene expression, splicing) from DNA sequences across a wide variety of tissues and cell types.
|
||||
|
||||
* **Variant effect scoring:** Assess the impact of genetic variants by comparing predictions for the reference and alternative alleles and summarising the differences between them.
|
||||
|
||||
* **Identify functional regions:** Use in silico mutagenesis (ISM) to identify functionally important regions in the DNA sequence.
|
||||
|
||||
* **Human and mouse capability:** Generate predictions for both human and mouse genomes.
|
||||
|
||||
## Documentation
|
||||
This API provides access to AlphaGenome, Google DeepMind's unifying model for
|
||||
deciphering the regulatory code within DNA sequences. AlphaGenome offers
|
||||
multimodal predictions, encompassing diverse functional outputs including gene
|
||||
expression, splicing patterns, chromatin features, and contact maps (see diagram
|
||||
below). The model analyzes up to 1 million base pairs of DNA sequence and can
|
||||
deliver predictions at single base-pair resolution for most modalities.
|
||||
AlphaGenome achieves state-of-the-art performance across a range of genomic
|
||||
prediction benchmarks, including diverse variant effect prediction tasks.
|
||||
|
||||
The Google Cloud API for AlphaGenome provides a way for Google Cloud customers
|
||||
to explore the AlphaGenome API for commercial use cases. This API is in private
|
||||
preview (Request Access above). Once allowlisted, customers can access the API
|
||||
directly or use the [colab](cloudai_alphagenome_vai_quickstart.ipynb).
|
||||
|
||||
### Acknowledgements
|
||||
|
||||
*Avsec, Ž., Latysheva, N., Cheng, J., Novati, G., Taylor, K. R., Ward, T., ... Kohli, P. (2025). AlphaGenome: advancing regulatory variant effect prediction with a unified DNA sequence model. bioRxiv.* [https://doi.org/10.1101/2025.06.25.661532](https://doi.org/10.1101/2025.06.25.661532)
|
||||
|
||||
### Contact
|
||||
If you have any questions on using these models on Google Cloud please contact:
|
||||
[alphagenome-cloud-external@google.com](mailto:alphagenome-cloud-external@google.com) or join the community [Discourse](https://www.alphagenomecommunity.com/) for more generic questions on AlphaGenome.
|
||||
|
||||
### Links
|
||||
|
||||
* Read our [paper](https://doi.org/10.1101/2025.06.25.661532)
|
||||
* Read our [blog post](https://deepmind.google/discover/blog/alphagenome-ai-for-better-understanding-the-genome)
|
||||
* Join the [community](https://www.alphagenomecommunity.com/)
|
||||
* Check out the [AlphaGenome 101 Video](https://youtu.be/Xbvloe13nak)
|
||||
|
||||
## Pricing
|
||||
Access to AlphaGenome on Vertex AI is currently restricted.
|
||||
To utilize these models via this service:
|
||||
|
||||
* You must **Request Access** using your Google contact.
|
||||
* Your application will be reviewed, and if approved, you will be **added to
|
||||
an allowlist**.
|
||||
* Only allowlisted users can access the API
|
||||
* **Pricing information** will be shared directly with users upon approval
|
||||
and placement on the allowlist.
|
||||
|
||||
## Quick start
|
||||
The quickest way to get started with the AlphaGenome in Google Cloud Platform is to run [our example notebook](cloudai_alphagenome_vai_quickstart.ipynb) in [Google Colab](https://colab.research.google.com/).
|
||||
File diff suppressed because one or more lines are too long
+2
@@ -545,6 +545,8 @@ def get_quota_id(
|
||||
"NVIDIA_H200_141GB": "H200GPUs",
|
||||
"NVIDIA_GB200": "B200GPUs",
|
||||
"NVIDIA_TESLA_T4": "T4GPUs",
|
||||
"NVIDIA_RTX_PRO_6000": "RTXPRO6000GPUs",
|
||||
"TPU_7x": "7XTPU",
|
||||
"TPU_V6e": "V6ETPU",
|
||||
"TPU_V5e": "V5ETPU",
|
||||
"TPU_V3": "V3TPUs",
|
||||
|
||||
@@ -545,6 +545,8 @@ def get_quota_id(
|
||||
"NVIDIA_H200_141GB": "H200GPUs",
|
||||
"NVIDIA_GB200": "B200GPUs",
|
||||
"NVIDIA_TESLA_T4": "T4GPUs",
|
||||
"NVIDIA_RTX_PRO_6000": "RTXPRO6000GPUs",
|
||||
"TPU_7x": "7XTPU",
|
||||
"TPU_V6e": "V6ETPU",
|
||||
"TPU_V5e": "V5ETPU",
|
||||
"TPU_V3": "V3TPUs",
|
||||
|
||||
@@ -120,7 +120,7 @@
|
||||
"id": "L3dqbxovo5t6",
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "440a9e07b0b3"
|
||||
"id": "50047cc80bb9"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
@@ -138,7 +138,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -868,7 +868,7 @@
|
||||
"per_node_accelerator_count = 8\n",
|
||||
"boot_disk_size_gb = 500\n",
|
||||
"dws_kwargs = {\n",
|
||||
" \"max_wait_duration\": 1800, # 30 minutes\n",
|
||||
" \"max_wait_duration\": 5400, # 90 minutes\n",
|
||||
" \"scheduling_strategy\": gca_custom_job_compat.Scheduling.Strategy.FLEX_START,\n",
|
||||
"}\n",
|
||||
"is_dynamic_workload_scheduler = True\n",
|
||||
@@ -990,7 +990,7 @@
|
||||
"# @markdown 4. Once the command runs (You may have to click `Authorize` if prompted), click the link starting with `http://localhost`.\n",
|
||||
"\n",
|
||||
"# @markdown Note: You may need to wait around 10 minutes after the job starts in order for the TensorBoard logs to be written to the GCS bucket.\n",
|
||||
"print(f\"Command to copy: tensorboard --logdir {AXOLOTL_OUTPUT_GCS_URI}\")"
|
||||
"print(f\"Command to copy: tensorboard --logdir {AXOLOTL_OUTPUT_GCS_URI}/node-0/runs/\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -1105,6 +1105,7 @@
|
||||
" max_num_seqs: int = 256,\n",
|
||||
" model_type: str = None,\n",
|
||||
" enable_llama_tool_parser: bool = False,\n",
|
||||
" is_spot: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys trained models with vLLM into Vertex AI.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
@@ -1199,6 +1200,7 @@
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" service_account=service_account,\n",
|
||||
" spot=is_spot,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_axolotl_finetuning.ipynb\",\n",
|
||||
" \"NOTEBOOK_ENVIRONMENT\": get_deploy_source(),\n",
|
||||
|
||||
@@ -826,7 +826,7 @@
|
||||
"per_node_accelerator_count = 8\n",
|
||||
"boot_disk_size_gb = 500\n",
|
||||
"dws_kwargs = {\n",
|
||||
" \"max_wait_duration\": 1800, # 30 minutes\n",
|
||||
" \"max_wait_duration\": 5400, # 90 minutes\n",
|
||||
" \"scheduling_strategy\": gca_custom_job_compat.Scheduling.Strategy.FLEX_START,\n",
|
||||
"}\n",
|
||||
"is_dynamic_workload_scheduler = True\n",
|
||||
@@ -948,7 +948,7 @@
|
||||
"# @markdown 4. Once the command runs (You may have to click `Authorize` if prompted), click the link starting with `http://localhost`.\n",
|
||||
"\n",
|
||||
"# @markdown Note: You may need to wait around 10 minutes after the job starts in order for the TensorBoard logs to be written to the GCS bucket.\n",
|
||||
"print(f\"Command to copy: tensorboard --logdir {AXOLOTL_OUTPUT_GCS_URI}\")"
|
||||
"print(f\"Command to copy: tensorboard --logdir {AXOLOTL_OUTPUT_GCS_URI}/node-0/runs/\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -983,7 +983,7 @@
|
||||
"if \"adapter\" in axolotl_config and (\n",
|
||||
" axolotl_config[\"adapter\"] == \"lora\" or axolotl_config[\"adapter\"] == \"qlora\"\n",
|
||||
"):\n",
|
||||
" VLLM_MODEL_GCS_URI = f\"{AXOLOTL_OUTPUT_GCS_URI}/merged\""
|
||||
" VLLM_MODEL_GCS_URI = f\"{AXOLOTL_OUTPUT_GCS_URI}/node-0/merged\""
|
||||
]
|
||||
},
|
||||
{
|
||||
|
||||
@@ -521,7 +521,7 @@
|
||||
"per_node_accelerator_count = 8\n",
|
||||
"boot_disk_size_gb = 500\n",
|
||||
"dws_kwargs = {\n",
|
||||
" \"max_wait_duration\": 1800, # 30 minutes\n",
|
||||
" \"max_wait_duration\": 5400, # 90 minutes\n",
|
||||
" \"scheduling_strategy\": gca_custom_job_compat.Scheduling.Strategy.FLEX_START,\n",
|
||||
"}\n",
|
||||
"is_dynamic_workload_scheduler = True\n",
|
||||
@@ -643,7 +643,7 @@
|
||||
"# @markdown 4. Once the command runs (You may have to click `Authorize` if prompted), click the link starting with `http://localhost`.\n",
|
||||
"\n",
|
||||
"# @markdown Note: You may need to wait around 10 minutes after the job starts in order for the TensorBoard logs to be written to the GCS bucket.\n",
|
||||
"print(f\"Command to copy: tensorboard --logdir {AXOLOTL_OUTPUT_GCS_URI}\")"
|
||||
"print(f\"Command to copy: tensorboard --logdir {AXOLOTL_OUTPUT_GCS_URI}/node-0/runs/\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
|
||||
@@ -823,7 +823,7 @@
|
||||
"per_node_accelerator_count = 8\n",
|
||||
"boot_disk_size_gb = 500\n",
|
||||
"dws_kwargs = {\n",
|
||||
" \"max_wait_duration\": 1800, # 30 minutes\n",
|
||||
" \"max_wait_duration\": 5400, # 90 minutes\n",
|
||||
" \"scheduling_strategy\": gca_custom_job_compat.Scheduling.Strategy.FLEX_START,\n",
|
||||
"}\n",
|
||||
"is_dynamic_workload_scheduler = True\n",
|
||||
@@ -945,7 +945,7 @@
|
||||
"# @markdown 4. Once the command runs (You may have to click `Authorize` if prompted), click the link starting with `http://localhost`.\n",
|
||||
"\n",
|
||||
"# @markdown Note: You may need to wait around 10 minutes after the job starts in order for the TensorBoard logs to be written to the GCS bucket.\n",
|
||||
"print(f\"Command to copy: tensorboard --logdir {AXOLOTL_OUTPUT_GCS_URI}\")"
|
||||
"print(f\"Command to copy: tensorboard --logdir {AXOLOTL_OUTPUT_GCS_URI}/node-0/runs/\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -979,12 +979,12 @@
|
||||
" print(\"The training job has finished.\")\n",
|
||||
"\n",
|
||||
"# @markdown 2. Set up SGLang docker URI and model gcs uri.\n",
|
||||
"SGLANG_MODEL_GCS_URI = AXOLOTL_OUTPUT_GCS_URI\n",
|
||||
"SGLANG_MODEL_GCS_URI = f\"{AXOLOTL_OUTPUT_GCS_URI}/node-0/\"\n",
|
||||
"\n",
|
||||
"if \"adapter\" in axolotl_config and (\n",
|
||||
" axolotl_config[\"adapter\"] == \"lora\" or axolotl_config[\"adapter\"] == \"qlora\"\n",
|
||||
"):\n",
|
||||
" SGLANG_MODEL_GCS_URI = f\"{AXOLOTL_OUTPUT_GCS_URI}/merged\"\n",
|
||||
" SGLANG_MODEL_GCS_URI = f\"{AXOLOTL_OUTPUT_GCS_URI}/node-0/merged\"\n",
|
||||
"\n",
|
||||
"# The pre-built serving docker images.\n",
|
||||
"SGLANG_DOCKER_URI = \"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/sglang-serve.cu124.0-4.ubuntu2204.py310:20250428-1803-rc0\"\n",
|
||||
|
||||
@@ -99,7 +99,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -165,14 +165,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -329,6 +334,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -338,7 +355,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -362,7 +379,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/deeplearning-platform-release/gcr.io/huggingface-text-embeddings-inference-cu122.1-2.ubuntu2204\",\n",
|
||||
@@ -372,6 +389,25 @@
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -565,7 +601,7 @@
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
@@ -130,7 +130,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -109,7 +109,8 @@
|
||||
"! pip install --upgrade --quiet gcsfs==2024.3.1\n",
|
||||
"! pip install --upgrade --quiet accelerate==0.34.2\n",
|
||||
"! pip install --upgrade --quiet transformers==4.47.1\n",
|
||||
"! pip install --upgrade --quiet datasets==2.20.0"
|
||||
"! pip install --upgrade --quiet datasets==2.20.0\n",
|
||||
"! pip install --upgrade --quiet google-cloud-aiplatform==1.130.0"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -839,6 +840,7 @@
|
||||
" max_num_seqs: int = 256,\n",
|
||||
" model_type: str = None,\n",
|
||||
" enable_llama_tool_parser: bool = False,\n",
|
||||
" is_spot: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys trained models with vLLM into Vertex AI.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
@@ -933,6 +935,7 @@
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" service_account=service_account,\n",
|
||||
" spot=is_spot,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_gemma2_finetuning_on_vertex.ipynb\",\n",
|
||||
" \"NOTEBOOK_ENVIRONMENT\": get_deploy_source(),\n",
|
||||
|
||||
@@ -165,14 +165,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -232,7 +237,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model_version = \"gemma-3-1b-it\" # @param [\"gemma-3-12b-it\", \"gemma-3-12b-pt\", \"gemma-3-1b-it\", \"gemma-3-1b-pt\", \"gemma-3-270m\", \"gemma-3-270m-it\", \"gemma-3-27b-it\", \"gemma-3-27b-pt\", \"gemma-3-4b-it\", \"gemma-3-4b-pt\"] {isTemplate:true}\n",
|
||||
"model_version = \"gemma-3-4b-it\" # @param [\"gemma-3-12b-it\", \"gemma-3-12b-pt\", \"gemma-3-1b-it\", \"gemma-3-1b-pt\", \"gemma-3-270m\", \"gemma-3-270m-it\", \"gemma-3-27b-it\", \"gemma-3-27b-pt\", \"gemma-3-4b-it\", \"gemma-3-4b-pt\"] {isTemplate:true}\n",
|
||||
"MODEL_NAME = f\"google/gemma3@{model_version}\""
|
||||
]
|
||||
},
|
||||
@@ -329,6 +334,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -338,7 +355,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -362,16 +379,35 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20250430_0916_RC00_maas\",\n",
|
||||
" machine_type=\"a3-highgpu-1g\",\n",
|
||||
" accelerator_type=\"NVIDIA_H100_80GB\",\n",
|
||||
" machine_type=\"a2-ultragpu-1g\",\n",
|
||||
" accelerator_type=\"NVIDIA_A100_80GB\",\n",
|
||||
" accelerator_count=1,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -472,6 +508,7 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Chat completion with multimodal requests\n",
|
||||
"# @markdown Note `1b` models don't support multimodal requests.\n",
|
||||
"\n",
|
||||
"if use_dedicated_endpoint:\n",
|
||||
" DEDICATED_ENDPOINT_DNS = endpoint.gca_resource.dedicated_endpoint_dns\n",
|
||||
@@ -487,7 +524,7 @@
|
||||
"\n",
|
||||
"# @markdown Next fill out some request parameters:\n",
|
||||
"\n",
|
||||
"user_image = \"https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg\"\n",
|
||||
"user_image = \"https://images.google.com/images/branding/googlelogo/2x/googlelogo_color_272x92dp.png\"\n",
|
||||
"user_message = \"What is in the image?\" # @param {type: \"string\"}\n",
|
||||
"# @markdown If you encounter the issue like `ServiceUnavailable: 503 Took too long to respond when processing`, you can reduce the maximum number of output tokens, such as set `max_tokens` as 20.\n",
|
||||
"max_tokens = 50 # @param {type: \"integer\"}\n",
|
||||
@@ -554,7 +591,7 @@
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
File diff suppressed because it is too large
Load Diff
@@ -165,14 +165,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -329,6 +334,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -338,7 +355,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -362,16 +379,35 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/sglang-serve.cu124.0-4.ubuntu2204.py310:model-garden.sglang-0-4-release_20250817.00_p0\",\n",
|
||||
" machine_type=\"a3-highgpu-1g\",\n",
|
||||
" accelerator_type=\"NVIDIA_H100_80GB\",\n",
|
||||
" machine_type=\"a2-ultragpu-1g\",\n",
|
||||
" accelerator_type=\"NVIDIA_A100_80GB\",\n",
|
||||
" accelerator_count=1,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -551,7 +587,7 @@
|
||||
"\n",
|
||||
"# @markdown Next fill out some request parameters:\n",
|
||||
"\n",
|
||||
"user_image = \"https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg\"\n",
|
||||
"user_image = \"https://images.google.com/images/branding/googlelogo/2x/googlelogo_color_272x92dp.png\"\n",
|
||||
"user_message = \"What is in the image?\" # @param {type: \"string\"}\n",
|
||||
"# @markdown If you encounter the issue like `ServiceUnavailable: 503 Took too long to respond when processing`, you can reduce the maximum number of output tokens, such as set `max_tokens` as 20.\n",
|
||||
"max_tokens = 50 # @param {type: \"integer\"}\n",
|
||||
@@ -688,7 +724,7 @@
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
@@ -97,7 +97,7 @@
|
||||
"# @title Install Python Packages for Finetuning\n",
|
||||
"\n",
|
||||
"# @markdown 1. Install google-cloud-aiplatform package and restart the session if instructed.\n",
|
||||
"! pip install --upgrade --quiet 'google-cloud-aiplatform>=1.66.0'\n",
|
||||
"! pip install --upgrade --quiet google-cloud-aiplatform==1.130.0\n",
|
||||
"\n",
|
||||
"# @markdown 2. Install packages to validate dataset with template.\n",
|
||||
"! pip install --upgrade --quiet accelerate==0.31.0\n",
|
||||
@@ -700,6 +700,7 @@
|
||||
" max_num_seqs: int = 256,\n",
|
||||
" model_type: str = None,\n",
|
||||
" enable_llama_tool_parser: bool = False,\n",
|
||||
" is_spot: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys trained models with vLLM into Vertex AI.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
@@ -794,6 +795,7 @@
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" service_account=service_account,\n",
|
||||
" spot=is_spot,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_gemma_finetuning_on_vertex.ipynb\",\n",
|
||||
" \"NOTEBOOK_ENVIRONMENT\": get_deploy_source(),\n",
|
||||
|
||||
+429
-439
@@ -58,8 +58,17 @@
|
||||
"\n",
|
||||
"### Objective\n",
|
||||
"\n",
|
||||
"- Chat with instruction-tuned text generation models deployed on the [Vertex Online Prediction](https://cloud.google.com/vertex-ai/docs/predictions/get-online-predictions) endpoints.\n",
|
||||
"- (Optional) One-click deploy demo models to [Vertex Online Prediction](https://cloud.google.com/vertex-ai/docs/predictions/get-online-predictions) endpoints.\n",
|
||||
"This notebook shows how to build a streaming chat UI using [Gradio](https://www.gradio.app/) and models from **Vertex AI Model Garden**.\n",
|
||||
"\n",
|
||||
"We cover two options:\n",
|
||||
"\n",
|
||||
"1. Public Playground Endpoints — quick demos, no deployment needed. \n",
|
||||
"2. Self-Deployed Endpoints (via Model Garden SDK) — production-ready, full control over resources, scaling, and networking using [Vertex Online Prediction](https://cloud.google.com/vertex-ai/docs/predictions/get-online-predictions).\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"### File a Bug\n",
|
||||
"\n",
|
||||
"If you encounter issues with this notebook, report them on [GitHub](https://github.com/GoogleCloudPlatform/vertex-ai-samples/issues/new).\n",
|
||||
"\n",
|
||||
"### Costs\n",
|
||||
"\n",
|
||||
@@ -74,10 +83,19 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "B4ppASahFB9b"
|
||||
"id": "TW7zfjJ9ijdv"
|
||||
},
|
||||
"source": [
|
||||
"## Run the notebook"
|
||||
"## Get Started"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "t2ZbddqwirAQ"
|
||||
},
|
||||
"source": [
|
||||
"### Install Vertex AI SDK and other required packages"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -85,27 +103,261 @@
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "62VgpTrAGx9JQPwjG5RYFCJT"
|
||||
"id": "jUZxkzWgisjM"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Setup Google Cloud project and install dependencies\n",
|
||||
"# Upgrade Vertex AI SDK.\n",
|
||||
"! pip3 install --upgrade --quiet 'google-cloud-aiplatform>=1.64.0'\n",
|
||||
"! pip3 install --upgrade gradio~=4.40.0\n",
|
||||
"%pip install --upgrade --force-reinstall --quiet 'google-cloud-aiplatform>=1.106.0' 'gradio~=4.40.0' 'openai' 'google-auth==2.27.0' 'requests==2.32.3'"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "5kqUh4mLi3ve"
|
||||
},
|
||||
"source": [
|
||||
"### Authenticate the Notebook Environment (Colab only)\n",
|
||||
"\n",
|
||||
"If you're running this notebook in Google Colab, run the following cell to authenticate."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "LCCyyaMCi5WA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import sys\n",
|
||||
"\n",
|
||||
"if \"google.colab\" in sys.modules:\n",
|
||||
" from google.colab import auth\n",
|
||||
"\n",
|
||||
" auth.authenticate_user()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "C4OKFznli8wZ"
|
||||
},
|
||||
"source": [
|
||||
"### Set Google Cloud Project Information\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"To get started with Vertex AI, ensure you have an existing Google Cloud project and that the [Vertex AI API is enabled](https://console.cloud.google.com/flows/enableapi?apiid=aiplatform.googleapis.com).\n",
|
||||
"\n",
|
||||
"See the guide on [setting up your project and development environment](https://cloud.google.com/vertex-ai/docs/start/cloud-environment). Also confirm that [billing is enabled](https://cloud.google.com/billing/docs/how-to/modify-project)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "rvg9VdvLjDlU"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Use the environment variable if the user doesn't provide Project ID.\n",
|
||||
"import os\n",
|
||||
"\n",
|
||||
"from google.cloud import aiplatform\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"# Get the default cloud project id.\n",
|
||||
"PROJECT_ID = os.environ[\"GOOGLE_CLOUD_PROJECT\"]\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"# Get the default region for endpoints.\n",
|
||||
"REGION = os.environ[\"GOOGLE_CLOUD_REGION\"]\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"\n",
|
||||
"aiplatform.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"# Dedicated endpoint not supported yet\n",
|
||||
"REGION = \"us-west1\" # @param {type: \"string\", placeholder: \"us-west1\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-west1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "UJTVLP9KjGcA"
|
||||
},
|
||||
"source": [
|
||||
"### Import libraries"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "JVyH9233jAfs"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import json\n",
|
||||
"from typing import Any, Dict, List, Optional, Tuple\n",
|
||||
"\n",
|
||||
"import google.auth\n",
|
||||
"import google.auth.transport.requests\n",
|
||||
"import gradio as gr\n",
|
||||
"import requests\n",
|
||||
"from vertexai import model_garden"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "32d-COi4Xuxf"
|
||||
},
|
||||
"source": [
|
||||
"## Choose an Endpoint"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "9l5U7zzWjQN4"
|
||||
},
|
||||
"source": [
|
||||
"### [Option 1] Public Playground Endpoint\n",
|
||||
"\n",
|
||||
"Google provides some shared endpoints for quick testing. These are **multi-tenant** and intended for experimentation, not production. Use this option if you just want to test the chat UI quickly.\n",
|
||||
"\n",
|
||||
"This example is using Gemma-2-2b-it (Public playground)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "k1Vg7ZtRjXJV"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"use_public_endpoint = True\n",
|
||||
"MODEL = \"google/796\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-7NrNHYumaMT"
|
||||
},
|
||||
"source": [
|
||||
"### [Option 2] Self-Deployed Endpoint\n",
|
||||
"Deploy a model from Model Garden with your own settings. You control machine type, scaling, etc."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "PngCre5noddO"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"use_public_endpoint = False"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "nYZ9ej_1p--4"
|
||||
},
|
||||
"source": [
|
||||
"#### Choose model variant\n",
|
||||
"\n",
|
||||
"You can proceed with the default model variant or select a different one.\n",
|
||||
"\n",
|
||||
"To see all deployable model variants available in Model Garden, use:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "EAgXX3-lnFyY"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"all_deployable_models = model_garden.list_deployable_models()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "z6J_UhJOnPVT"
|
||||
},
|
||||
"source": [
|
||||
"Once you've selected a model variant, initialize it:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "miOkAxBenRig"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model = model_garden.OpenModel(\"openai/gpt-oss@gpt-oss-20b\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "8ZSQ6jUrn33o"
|
||||
},
|
||||
"source": [
|
||||
"#### Check the Deployment Configuration\n",
|
||||
"\n",
|
||||
"Use the `list_deploy_options()` method to view the verified deployment configurations for your selected model. This helps ensure you have sufficient resources (e.g., GPU quota) available to deploy it.\n",
|
||||
"\n",
|
||||
"> **Note**: Only endpoints with **TGI**, **vLLM**, and **HexLLM** serving container image deployed after August 20, 2024 with a new container image support chat completions and streaming features. If you are not sure, you can deploy a demo endpoint directly from below."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "vL7Qf_H8n5gc"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"deploy_options = model.list_deploy_options(concise=True)\n",
|
||||
"print(deploy_options)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "AqLAKRhWn9JY"
|
||||
},
|
||||
"source": [
|
||||
"#### Deploy the Model\n",
|
||||
"\n",
|
||||
"Now that you’ve reviewed the deployment options, use the `deploy()` method to serve the selected open model to a Vertex AI endpoint. Deployment time may vary depending on the model size and infrastructure requirements.\n",
|
||||
"\n",
|
||||
"> **Note**: If the model requires accepting a license agreement (EULA), set the `accept_eula=True` flag in the deploy call. Set `use_dedicated_endpoint` to False if you don't want to use [dedicated endpoint](https://cloud.google.com/vertex-ai/docs/general/deployment#create-dedicated-endpoint)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "CFUxKaCiogKF"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"use_dedicated_endpoint = False"
|
||||
]
|
||||
},
|
||||
@@ -114,471 +366,209 @@
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "-zFBGiLWUVNd"
|
||||
"id": "BrloHZgXm-z1"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Start the playground\n",
|
||||
"endpoint = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20250807_0916_RC01_maas\",\n",
|
||||
" machine_type=\"a3-highgpu-1g\",\n",
|
||||
" accelerator_type=\"NVIDIA_H100_80GB\",\n",
|
||||
" accelerator_count=1,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "etu4WvXqH7Pf"
|
||||
},
|
||||
"source": [
|
||||
"## Streaming Chat Function\n",
|
||||
"\n",
|
||||
"# @markdown This is a chatbot playground for instruction-tuned text generation models.\n",
|
||||
"# @markdown After the cell runs, this playground is available in a separate browser tab if you click the public URL,\n",
|
||||
"# @markdown i.e. [\"https://####.gradio.live\"](#) in the output of the cell.\n",
|
||||
"\n",
|
||||
"# @markdown **How to use:**\n",
|
||||
"# @markdown 1. **Important**: Notebook cell reruns create new public URLs. Previous URLs will stop working.\n",
|
||||
"# @markdown 1. Before you start, you need to select a Vertex prediction endpoint with a matching model\n",
|
||||
"# @markdown from the endpoint dropdown list in the same project and region where you run this notebook.\n",
|
||||
"# @markdown 1. This playground only supports new deployments with\n",
|
||||
"# @markdown text-generation-inference (`us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-hf-tgi-serve`),\n",
|
||||
"# @markdown vLLM (`us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve`),\n",
|
||||
"# @markdown or HexLLM (`us-docker.pkg.dev/vertex-ai-restricted/vertex-vision-model-garden-dockers/hex-llm-serve`).\n",
|
||||
"# @markdown\n",
|
||||
"# @markdown **Endpoints deployed with older serving containers or before August 20, 2024 might not work**. We recommend deploying a new endpoint from the listed demo models inside the Gradio app.\n",
|
||||
"# @markdown 1. After experiments, do not forget to undeploy the models from [Vertex Online Prediction](https://console.cloud.google.com/vertex-ai/online-prediction/endpoints) to avoid continuous charges to the project.\n",
|
||||
"\n",
|
||||
"import dataclasses\n",
|
||||
"import json\n",
|
||||
"from typing import Callable, Tuple\n",
|
||||
"\n",
|
||||
"import gradio as gr\n",
|
||||
"import requests\n",
|
||||
"\n",
|
||||
"MAX_TOKENS = 512\n",
|
||||
"HF_TOKEN = \"\"\n",
|
||||
"\n",
|
||||
"VLLM_DOCKER_URI = \"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20240819_0916_RC00\"\n",
|
||||
"TGI_DOCKER_URI = \"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-hf-tgi-serve:20240820_0936_RC01\"\n",
|
||||
"\n",
|
||||
"SERVER_TYPE_VLLM = \"vllm\"\n",
|
||||
"SERVER_TYPE_HEXLLM = \"hex-llm\"\n",
|
||||
"SERVER_TYPE_TGI = \"tgi\"\n",
|
||||
"SERVER_TYPES = [\n",
|
||||
" SERVER_TYPE_VLLM,\n",
|
||||
" SERVER_TYPE_HEXLLM,\n",
|
||||
" SERVER_TYPE_TGI,\n",
|
||||
"]\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"@dataclasses.dataclass\n",
|
||||
"class Endpoint:\n",
|
||||
" display_name: str\n",
|
||||
" location: str\n",
|
||||
" resource_name: str\n",
|
||||
" server_type: str\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"PUBLIC_PLAYGROUND_ENDPOINTS = [\n",
|
||||
" Endpoint(\n",
|
||||
" display_name=\"Gemma-2-2b-it (Public playground)\",\n",
|
||||
" location=\"us-west1\",\n",
|
||||
" resource_name=\"playground:google/796\",\n",
|
||||
" server_type=SERVER_TYPE_HEXLLM,\n",
|
||||
" ),\n",
|
||||
"]\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"@dataclasses.dataclass\n",
|
||||
"class DeployConfig:\n",
|
||||
" display_name: str\n",
|
||||
" model_name: str\n",
|
||||
" func: Callable[[str], tuple[aiplatform.Model, aiplatform.Endpoint]]\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def deploy_model_vllm(\n",
|
||||
" model_name: str,\n",
|
||||
" model_id: str,\n",
|
||||
" publisher: str,\n",
|
||||
" publisher_model_id: str,\n",
|
||||
" service_account: str,\n",
|
||||
" base_model_id: str = None,\n",
|
||||
" machine_type: str = \"g2-standard-8\",\n",
|
||||
" accelerator_type: str = \"NVIDIA_L4\",\n",
|
||||
" accelerator_count: int = 1,\n",
|
||||
" gpu_memory_utilization: float = 0.9,\n",
|
||||
" max_model_len: int = 4096,\n",
|
||||
" dtype: str = \"auto\",\n",
|
||||
" enable_trust_remote_code: bool = False,\n",
|
||||
" enforce_eager: bool = False,\n",
|
||||
" enable_lora: bool = False,\n",
|
||||
" enable_chunked_prefill: bool = False,\n",
|
||||
" enable_prefix_cache: bool = False,\n",
|
||||
" host_prefix_kv_cache_utilization_target: float = 0.0,\n",
|
||||
" max_loras: int = 1,\n",
|
||||
" max_cpu_loras: int = 8,\n",
|
||||
" use_dedicated_endpoint: bool = False,\n",
|
||||
" max_num_seqs: int = 256,\n",
|
||||
" model_type: str = None,\n",
|
||||
" enable_llama_tool_parser: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys trained models with vLLM into Vertex AI.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
" display_name=f\"{model_name}-endpoint\",\n",
|
||||
" dedicated_endpoint_enabled=use_dedicated_endpoint,\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" if not base_model_id:\n",
|
||||
" base_model_id = model_id\n",
|
||||
"\n",
|
||||
" # See https://docs.vllm.ai/en/latest/models/engine_args.html for a list of possible arguments with descriptions.\n",
|
||||
" vllm_args = [\n",
|
||||
" \"python\",\n",
|
||||
" \"-m\",\n",
|
||||
" \"vllm.entrypoints.api_server\",\n",
|
||||
" \"--host=0.0.0.0\",\n",
|
||||
" \"--port=8080\",\n",
|
||||
" f\"--model={model_id}\",\n",
|
||||
" f\"--tensor-parallel-size={accelerator_count}\",\n",
|
||||
" \"--swap-space=16\",\n",
|
||||
" f\"--max-model-len={max_model_len}\",\n",
|
||||
" f\"--dtype={dtype}\",\n",
|
||||
" f\"--max-loras={max_loras}\",\n",
|
||||
" f\"--max-cpu-loras={max_cpu_loras}\",\n",
|
||||
" f\"--max-num-seqs={max_num_seqs}\",\n",
|
||||
" \"--disable-log-stats\",\n",
|
||||
" ]\n",
|
||||
"\n",
|
||||
" if gpu_memory_utilization:\n",
|
||||
" vllm_args.append(f\"--gpu-memory-utilization={gpu_memory_utilization}\")\n",
|
||||
"\n",
|
||||
" if enable_trust_remote_code:\n",
|
||||
" vllm_args.append(\"--trust-remote-code\")\n",
|
||||
"\n",
|
||||
" if enforce_eager:\n",
|
||||
" vllm_args.append(\"--enforce-eager\")\n",
|
||||
"\n",
|
||||
" if enable_lora:\n",
|
||||
" vllm_args.append(\"--enable-lora\")\n",
|
||||
"\n",
|
||||
" if enable_chunked_prefill:\n",
|
||||
" vllm_args.append(\"--enable-chunked-prefill\")\n",
|
||||
"\n",
|
||||
" if enable_prefix_cache:\n",
|
||||
" vllm_args.append(\"--enable-prefix-caching\")\n",
|
||||
"\n",
|
||||
" if 0 < host_prefix_kv_cache_utilization_target < 1:\n",
|
||||
" vllm_args.append(\n",
|
||||
" f\"--host-prefix-kv-cache-utilization-target={host_prefix_kv_cache_utilization_target}\"\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" if model_type:\n",
|
||||
" vllm_args.append(f\"--model-type={model_type}\")\n",
|
||||
"\n",
|
||||
" if enable_llama_tool_parser:\n",
|
||||
" vllm_args.append(\"--enable-auto-tool-choice\")\n",
|
||||
" vllm_args.append(\"--tool-call-parser=vertex-llama-3\")\n",
|
||||
"\n",
|
||||
" env_vars = {\n",
|
||||
" \"MODEL_ID\": base_model_id,\n",
|
||||
" \"DEPLOY_SOURCE\": \"notebook\",\n",
|
||||
" }\n",
|
||||
"\n",
|
||||
" # HF_TOKEN is not a compulsory field and may not be defined.\n",
|
||||
" try:\n",
|
||||
" if HF_TOKEN:\n",
|
||||
" env_vars[\"HF_TOKEN\"] = HF_TOKEN\n",
|
||||
" except NameError:\n",
|
||||
" pass\n",
|
||||
"\n",
|
||||
" model = aiplatform.Model.upload(\n",
|
||||
" display_name=model_name,\n",
|
||||
" serving_container_image_uri=VLLM_DOCKER_URI,\n",
|
||||
" serving_container_args=vllm_args,\n",
|
||||
" serving_container_ports=[8080],\n",
|
||||
" serving_container_predict_route=\"/generate\",\n",
|
||||
" serving_container_health_route=\"/ping\",\n",
|
||||
" serving_container_environment_variables=env_vars,\n",
|
||||
" serving_container_shared_memory_size_mb=(16 * 1024), # 16 GB\n",
|
||||
" serving_container_deployment_timeout=7200,\n",
|
||||
" model_garden_source_model_name=(\n",
|
||||
" f\"publishers/{publisher}/models/{publisher_model_id}\"\n",
|
||||
" ),\n",
|
||||
" )\n",
|
||||
" print(\n",
|
||||
" f\"Deploying {model_name} on {machine_type} with {accelerator_count} {accelerator_type} GPU(s).\"\n",
|
||||
" )\n",
|
||||
" model.deploy(\n",
|
||||
" endpoint=endpoint,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" service_account=service_account,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_gradio_streaming_chat_completions.ipynb\",\n",
|
||||
" \"NOTEBOOK_ENVIRONMENT\": common_util.get_deploy_source(),\n",
|
||||
" },\n",
|
||||
" )\n",
|
||||
" print(\"endpoint_name:\", endpoint.name)\n",
|
||||
"\n",
|
||||
" return model, endpoint\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def deploy_model_tgi(\n",
|
||||
" model_name: str,\n",
|
||||
" model_id: str,\n",
|
||||
" publisher: str,\n",
|
||||
" publisher_model_id: str,\n",
|
||||
" service_account: str = None,\n",
|
||||
" machine_type: str = \"g2-standard-8\",\n",
|
||||
" accelerator_type: str = \"NVIDIA_L4\",\n",
|
||||
" accelerator_count: int = 1,\n",
|
||||
" max_input_length: int = 2047,\n",
|
||||
" max_total_tokens: int = 2048,\n",
|
||||
" max_batch_prefill_tokens: int = 2048,\n",
|
||||
" use_dedicated_endpoint: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys models with TGI on GPU in Vertex AI.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
" display_name=f\"{model_name}-endpoint\",\n",
|
||||
" dedicated_endpoint_enabled=use_dedicated_endpoint,\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" env_vars = {\n",
|
||||
" \"MODEL_ID\": model_id,\n",
|
||||
" \"NUM_SHARD\": f\"{accelerator_count}\",\n",
|
||||
" \"MAX_INPUT_LENGTH\": f\"{max_input_length}\",\n",
|
||||
" \"MAX_TOTAL_TOKENS\": f\"{max_total_tokens}\",\n",
|
||||
" \"MAX_BATCH_PREFILL_TOKENS\": f\"{max_batch_prefill_tokens}\",\n",
|
||||
" \"DEPLOY_SOURCE\": \"notebook\",\n",
|
||||
" }\n",
|
||||
"\n",
|
||||
" # HF_TOKEN is not a compulsory field and may not be defined.\n",
|
||||
" try:\n",
|
||||
" if HF_TOKEN:\n",
|
||||
" env_vars[\"HF_TOKEN\"] = HF_TOKEN\n",
|
||||
" except NameError:\n",
|
||||
" pass\n",
|
||||
"\n",
|
||||
" if service_account:\n",
|
||||
" env_vars[\"SERVICE_ACCOUNT\"] = service_account\n",
|
||||
"\n",
|
||||
" model = aiplatform.Model.upload(\n",
|
||||
" display_name=model_name,\n",
|
||||
" serving_container_image_uri=TGI_DOCKER_URI,\n",
|
||||
" serving_container_ports=[8080],\n",
|
||||
" serving_container_environment_variables=env_vars,\n",
|
||||
" serving_container_shared_memory_size_mb=(16 * 1024), # 16 GB\n",
|
||||
" model_garden_source_model_name=(\n",
|
||||
" f\"publishers/{publisher}/models/{publisher_model_id}\"\n",
|
||||
" ),\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" model.deploy(\n",
|
||||
" endpoint=endpoint,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" service_account=service_account,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_gradio_streaming_chat_completions.ipynb\",\n",
|
||||
" \"NOTEBOOK_ENVIRONMENT\": common_util.get_deploy_source(),\n",
|
||||
" },\n",
|
||||
" )\n",
|
||||
" return model, endpoint\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"DEPLOY_CONFIGS = [\n",
|
||||
" DeployConfig(\n",
|
||||
" display_name=\"microsoft/Phi-3-mini-4k-instruct (vLLM)\",\n",
|
||||
" model_name=\"vllm-Phi-3-mini-4k-instruct\",\n",
|
||||
" func=lambda x: deploy_model_vllm(\n",
|
||||
" x, \"microsoft/Phi-3-mini-4k-instruct\", \"microsoft\", \"phi3\", None\n",
|
||||
" ),\n",
|
||||
" ),\n",
|
||||
" DeployConfig(\n",
|
||||
" display_name=\"Qwen/Qwen2-7B-Instruct (TGI)\",\n",
|
||||
" model_name=\"tgi-Qwen2-7B-Instruct\",\n",
|
||||
" func=lambda x: deploy_model_tgi(\n",
|
||||
" x, \"Qwen/Qwen2-7B-Instruct\", \"qwen\", \"qwen2\", None\n",
|
||||
" ),\n",
|
||||
" ),\n",
|
||||
"]\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def get_server_type(endpoint: aiplatform.Endpoint) -> str | None:\n",
|
||||
" \"\"\"Returns the model server type or None if not recognizable.\"\"\"\n",
|
||||
" models = endpoint.list_models()\n",
|
||||
" models: list[aiplatform.Model] = [aiplatform.Model(m.model) for m in models]\n",
|
||||
" for server_type in SERVER_TYPES:\n",
|
||||
" if any(server_type in model.container_spec.image_uri for model in models):\n",
|
||||
" return server_type\n",
|
||||
" return None\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def format_payload(messages: list[dict[str, str]]) -> dict[str, str]:\n",
|
||||
" return {\n",
|
||||
"This function will:\n",
|
||||
"- Take user input + history\n",
|
||||
"- Call the model (streaming)\n",
|
||||
"- Yield partial outputs so the UI updates in real time"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "e5sKDoepYDcp"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"def format_payload(\n",
|
||||
" messages: List[Dict[str, str]], max_tokens: int, model: str = None\n",
|
||||
") -> Dict[str, Any]:\n",
|
||||
" \"\"\"Formats the request payload for the chat completion API.\"\"\"\n",
|
||||
" payload = {\n",
|
||||
" \"messages\": messages,\n",
|
||||
" \"max_tokens\": MAX_TOKENS,\n",
|
||||
" \"max_tokens\": max_tokens,\n",
|
||||
" \"stream\": True,\n",
|
||||
" }\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def list_endpoints() -> list[tuple[str, str]]:\n",
|
||||
" \"\"\"Returns all valid prediction endpoints for in the project and region.\"\"\"\n",
|
||||
" endpoints = [\n",
|
||||
" endpoint\n",
|
||||
" for endpoint in aiplatform.Endpoint.list(order_by=\"create_time desc\")\n",
|
||||
" if endpoint.traffic_split and get_server_type(endpoint)\n",
|
||||
" ]\n",
|
||||
" endpoints = [(e.display_name, e.resource_name) for e in endpoints]\n",
|
||||
" endpoints.extend(\n",
|
||||
" (e.display_name, e.resource_name) for e in PUBLIC_PLAYGROUND_ENDPOINTS\n",
|
||||
" )\n",
|
||||
" return endpoints\n",
|
||||
" # Conditionally add the model for public endpoints\n",
|
||||
" if model:\n",
|
||||
" payload[\"model\"] = model\n",
|
||||
" return payload\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"class StreamingClient:\n",
|
||||
" \"\"\"A wrapper for a streaming client.\"\"\"\n",
|
||||
" \"\"\"A wrapper for a streaming client, initialized with either a model (public) or an endpoint (custom).\"\"\"\n",
|
||||
"\n",
|
||||
" endpoint: Endpoint | None = None\n",
|
||||
" def __init__(\n",
|
||||
" self,\n",
|
||||
" model: Optional[str] = None,\n",
|
||||
" endpoint: Optional[Any] = None,\n",
|
||||
" max_tokens: int = 512,\n",
|
||||
" use_dedicated_endpoint: bool = False,\n",
|
||||
" ):\n",
|
||||
" \"\"\"\n",
|
||||
" Initializes the client with API configuration.\n",
|
||||
"\n",
|
||||
" def set_endpoint(self, endpoint: str):\n",
|
||||
" \"\"\"Sets the prediction endpoint.\"\"\"\n",
|
||||
" playground_endpoint = [\n",
|
||||
" e for e in PUBLIC_PLAYGROUND_ENDPOINTS if e.resource_name == endpoint\n",
|
||||
" ]\n",
|
||||
" if playground_endpoint:\n",
|
||||
" self.endpoint = playground_endpoint[0]\n",
|
||||
" else:\n",
|
||||
" vertex_endpoint = aiplatform.Endpoint(endpoint)\n",
|
||||
" server_type = get_server_type(vertex_endpoint)\n",
|
||||
" self.endpoint = Endpoint(\n",
|
||||
" display_name=vertex_endpoint.display_name,\n",
|
||||
" location=vertex_endpoint.location,\n",
|
||||
" resource_name=endpoint,\n",
|
||||
" server_type=server_type,\n",
|
||||
" :param model: The model ID (e.g., \"gemini-2.5-flash\") for the public endpoint.\n",
|
||||
" :param endpoint: An object representing a custom deployed endpoint (must have a resource_name).\n",
|
||||
" :param max_tokens: The maximum number of tokens to generate.\n",
|
||||
" :param use_dedicated_endpoint: Flag to use a GCA-dedicated endpoint URL pattern.\n",
|
||||
" \"\"\"\n",
|
||||
" self.max_tokens = max_tokens\n",
|
||||
"\n",
|
||||
" if model is not None and endpoint is not None:\n",
|
||||
" raise ValueError(\n",
|
||||
" \"Must provide either a 'model' (for public API) OR an 'endpoint' (for custom deployment), not both.\"\n",
|
||||
" )\n",
|
||||
" print(\n",
|
||||
" \"Selected endpoint:\",\n",
|
||||
" self.endpoint.resource_name,\n",
|
||||
" \"Server:\",\n",
|
||||
" self.endpoint.server_type,\n",
|
||||
" if model is None and endpoint is None:\n",
|
||||
" raise ValueError(\n",
|
||||
" \"Must provide a 'model' (for public API) or an 'endpoint' (for custom deployment).\"\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" self.model = model\n",
|
||||
" self.use_public_endpoint = model is not None\n",
|
||||
"\n",
|
||||
" if self.use_public_endpoint:\n",
|
||||
" self.url = f\"https://{REGION}-aiplatform.googleapis.com/v1beta1/projects/{PROJECT_ID}/locations/{REGION}/endpoints/openapi/chat/completions\"\n",
|
||||
"\n",
|
||||
" elif use_dedicated_endpoint:\n",
|
||||
" self.url = f\"https://{endpoint.dedicated_endpoint_dns}/v1beta1/{endpoint.resource_name}/chat/completions\"\n",
|
||||
"\n",
|
||||
" else:\n",
|
||||
" self.url = f\"https://{REGION}-aiplatform.googleapis.com/v1beta1/{endpoint.resource_name}/chat/completions\"\n",
|
||||
"\n",
|
||||
" def _get_access_token(self) -> str:\n",
|
||||
" \"\"\"Programmatically obtains the access token using google.auth.\"\"\"\n",
|
||||
" credentials, _ = google.auth.default(\n",
|
||||
" scopes=[\"https://www.googleapis.com/auth/cloud-platform\"]\n",
|
||||
" )\n",
|
||||
" auth_request = google.auth.transport.requests.Request()\n",
|
||||
" credentials.refresh(auth_request)\n",
|
||||
" return credentials.token\n",
|
||||
"\n",
|
||||
" def predict(self, message: str, chat_history: list[tuple[str, str]]):\n",
|
||||
" if not self.endpoint:\n",
|
||||
" raise gr.Error(\"Select an endpoint first.\")\n",
|
||||
"\n",
|
||||
" def predict(self, message: str, chat_history: List[Tuple[str, str]]):\n",
|
||||
" \"\"\"\n",
|
||||
" Sends a request to the chat API and streams the response.\n",
|
||||
" :yields: Chunks of the streamed prediction text.\n",
|
||||
" \"\"\"\n",
|
||||
" messages = []\n",
|
||||
" for u, a in chat_history:\n",
|
||||
" messages.append({\"role\": \"user\", \"content\": u})\n",
|
||||
" messages.append({\"role\": \"assistant\", \"content\": a})\n",
|
||||
" messages.append({\"role\": \"user\", \"content\": message})\n",
|
||||
" payload = format_payload(messages)\n",
|
||||
"\n",
|
||||
" is_playground_endpoint = self.endpoint.resource_name.startswith(\"playground:\")\n",
|
||||
" if is_playground_endpoint:\n",
|
||||
" url = f\"https://{self.endpoint.location}-aiplatform.googleapis.com/v1beta1/projects/{PROJECT_ID}/locations/{self.endpoint.location}/endpoints/openapi/chat/completions\"\n",
|
||||
" payload[\"model\"] = self.endpoint.resource_name.removeprefix(\"playground:\")\n",
|
||||
" else:\n",
|
||||
" url = f\"https://{self.endpoint.location}-aiplatform.googleapis.com/v1beta1/{self.endpoint.resource_name}/chat/completions\"\n",
|
||||
" model_to_use = self.model if self.use_public_endpoint else None\n",
|
||||
" payload = format_payload(messages, self.max_tokens, model=model_to_use)\n",
|
||||
"\n",
|
||||
" access_token = self._get_access_token()\n",
|
||||
"\n",
|
||||
" access_token = ! gcloud auth print-access-token\n",
|
||||
" access_token = access_token[0]\n",
|
||||
" response = requests.post(\n",
|
||||
" url,\n",
|
||||
" self.url,\n",
|
||||
" headers={\"Authorization\": f\"Bearer {access_token}\"},\n",
|
||||
" json=payload,\n",
|
||||
" stream=True,\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" if not response.ok:\n",
|
||||
" raise gr.Error(response)\n",
|
||||
" raise gr.Error(\n",
|
||||
" f\"API Request Failed: {response.status_code} - {response.text}\"\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" prediction = \"\"\n",
|
||||
" for chunk in response.iter_lines(chunk_size=8192, decode_unicode=False):\n",
|
||||
" if chunk:\n",
|
||||
" chunk = chunk.decode(\"utf-8\").removeprefix(\"data:\").strip()\n",
|
||||
" if chunk == \"[DONE]\":\n",
|
||||
" break\n",
|
||||
" data = json.loads(chunk)\n",
|
||||
" if type(data) is not dict or \"error\" in data:\n",
|
||||
" try:\n",
|
||||
" data = json.loads(chunk)\n",
|
||||
" except json.JSONDecodeError:\n",
|
||||
" continue\n",
|
||||
"\n",
|
||||
" if not isinstance(data, dict) or \"error\" in data:\n",
|
||||
" raise gr.Error(data)\n",
|
||||
"\n",
|
||||
" delta = data[\"choices\"][0][\"delta\"].get(\"content\")\n",
|
||||
" if delta:\n",
|
||||
" prediction += delta\n",
|
||||
" yield prediction\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"streaming_client = StreamingClient()\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def create_endpoint_selector():\n",
|
||||
" \"\"\"Creates a dropdown list of prediction endpoints.\"\"\"\n",
|
||||
"\n",
|
||||
" with gr.Row():\n",
|
||||
" endpoints_dropdown = gr.Dropdown(\n",
|
||||
" list_endpoints(),\n",
|
||||
" label=\"Endpoint\",\n",
|
||||
" scale=1,\n",
|
||||
" info=\"Only TGI, vLLM, and HexLLM endpoints deployed after August 20, 2024 with a new container image support chat completions and streaming features. \"\n",
|
||||
" + \"If you are not sure, you can deploy a demo endpoint directly from below. \",\n",
|
||||
" )\n",
|
||||
" endpoints_dropdown.input(\n",
|
||||
" streaming_client.set_endpoint, inputs=[endpoints_dropdown], outputs=[]\n",
|
||||
" )\n",
|
||||
" refresh_btn = gr.Button(\"Refresh\", scale=0)\n",
|
||||
" refresh_btn.click(\n",
|
||||
" lambda: gr.Dropdown(choices=list_endpoints()),\n",
|
||||
" inputs=[],\n",
|
||||
" outputs=[endpoints_dropdown],\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def create_deploy_selector():\n",
|
||||
" \"\"\"Creates a dropdown list of model deploy configs.\"\"\"\n",
|
||||
"\n",
|
||||
" def find_deploy_config(display_name: str) -> DeployConfig:\n",
|
||||
" \"\"\"Finds the deploy config from display name.\"\"\"\n",
|
||||
" matches = [c for c in DEPLOY_CONFIGS if c.display_name == display_name]\n",
|
||||
" if not matches:\n",
|
||||
" raise gr.Error(\"Select a model to deploy first.\")\n",
|
||||
" return matches[0]\n",
|
||||
"\n",
|
||||
" def deploy(endpoint_name: str, display_name: str):\n",
|
||||
" \"\"\"Deploys the model.\"\"\"\n",
|
||||
" config = find_deploy_config(display_name)\n",
|
||||
" gr.Info(f\"Deploying to {endpoint_name}...\")\n",
|
||||
" config.func(endpoint_name)\n",
|
||||
" gr.Info(f\"Deployed to {endpoint_name}. Refresh the endpoints to see it.\")\n",
|
||||
"\n",
|
||||
" with gr.Row():\n",
|
||||
" deploy_dropdown = gr.Dropdown(\n",
|
||||
" [x.display_name for x in DEPLOY_CONFIGS],\n",
|
||||
" label=\"Deploy Model\",\n",
|
||||
" scale=1,\n",
|
||||
" info=\"Model deployment will take ~20 minutes. After you finish your experiments, \"\n",
|
||||
" + \"undeploy the endpoint from Vertex Online Prediction to avoid continuous charges to the project.\",\n",
|
||||
" )\n",
|
||||
" model_name = gr.Textbox(\n",
|
||||
" label=\"Model Name\",\n",
|
||||
" placeholder=\"Enter a custom model name for endpoint creation\",\n",
|
||||
" interactive=True,\n",
|
||||
" )\n",
|
||||
" deploy_dropdown.change(\n",
|
||||
" lambda x: find_deploy_config(x).model_name,\n",
|
||||
" inputs=[deploy_dropdown],\n",
|
||||
" outputs=[model_name],\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" deploy_btn = gr.Button(\"Deploy\", scale=0)\n",
|
||||
" deploy_btn.click(\n",
|
||||
" lambda: gr.Button(\"Deploying...\", interactive=False),\n",
|
||||
" inputs=[],\n",
|
||||
" outputs=[deploy_btn],\n",
|
||||
" ).then(deploy, inputs=[model_name, deploy_dropdown], outputs=[]).then(\n",
|
||||
" lambda: gr.Button(\"Deploy\", interactive=True), [], [deploy_btn]\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" yield prediction"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "w-dAr278H-89"
|
||||
},
|
||||
"source": [
|
||||
"## Build Gradio Interface\n",
|
||||
"Use Gradio to build a chat interface that calls the `stream_chat` generator: the UI shows messages and the streaming response."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "PY6xIJQ8IBKT"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if use_public_endpoint:\n",
|
||||
" client = StreamingClient(model=MODEL)\n",
|
||||
"else:\n",
|
||||
" client = StreamingClient(\n",
|
||||
" endpoint=endpoint, use_dedicated_endpoint=use_dedicated_endpoint\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
"with gr.Blocks(title=\"Vertex Model Garden Chat\", fill_height=True) as demo:\n",
|
||||
" create_endpoint_selector()\n",
|
||||
" create_deploy_selector()\n",
|
||||
" gr.ChatInterface(streaming_client.predict)\n",
|
||||
" gr.ChatInterface(client.predict)\n",
|
||||
"\n",
|
||||
"demo.launch(share=False, debug=True, show_error=True)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "crFYGvxIIG2l"
|
||||
},
|
||||
"source": [
|
||||
"## Cleanup\n",
|
||||
"\n",
|
||||
"show_debug_logs = True # @param {type: \"boolean\"}\n",
|
||||
"demo.queue()\n",
|
||||
"demo.launch(share=True, inline=False, debug=show_debug_logs, show_error=True)"
|
||||
"If you deployed your own endpoint, make sure to delete it to avoid charges:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "GM-Xrc0SIIJF"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# endpoint.delete() # Uncomment when ready"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
||||
@@ -165,14 +165,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -329,6 +334,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -338,7 +355,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -362,7 +379,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-one-serve:20250205_0822_RC00\",\n",
|
||||
@@ -372,6 +389,25 @@
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -513,7 +549,7 @@
|
||||
"source": [
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
+2
-2
@@ -103,7 +103,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
@@ -163,7 +163,7 @@
|
||||
"TASK = \"text-classification\" # @param {type: \"string\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"# The pre-built serving docker images for Hugging Face Pytorch Inference.\n",
|
||||
"SERVE_DOCKER_URI = \"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/hf-inference-toolkit.cu125.0-1.ubuntu2204.py311:model-garden.hf-inference-toolkit-0-1-release_20250828.01_p0\"\n",
|
||||
"SERVE_DOCKER_URI = \"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/hf-inference-toolkit.cu125.0-1.ubuntu2204.py311:model-garden.hf-inference-toolkit-0-1-release_20251206.00_p0\"\n",
|
||||
"\n",
|
||||
"machine_type = \"g2-standard-8\" # @param {type: \"string\", isTemplate: true}\n",
|
||||
"accelerator_type = \"NVIDIA_L4\" # @param [\"NVIDIA_L4\", \"None\"] {isTemplate: true}\n",
|
||||
|
||||
@@ -112,7 +112,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
@@ -214,7 +214,7 @@
|
||||
"HUGGING_FACE_MODEL_ID = \"Qwen/Qwen3-Embedding-8B\" # @param {type: \"string\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"# The pre-built serving docker images for TEI.\n",
|
||||
"TEI_DOCKER_URI = \"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/hf-tei.cu125.0-1.ubuntu2204.py310:model-garden.hf-tei-0-1-release_20250828.01_p0\"\n",
|
||||
"TEI_DOCKER_URI = \"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/hf-tei.cu125.0-1.ubuntu2204.py310:model-garden.hf-tei-0-1-release_20251205.00_p0\"\n",
|
||||
"\n",
|
||||
"machine_type = \"g2-standard-8\" # @param {type: \"string\", isTemplate: true}\n",
|
||||
"accelerator_type = \"NVIDIA_L4\" # @param [\"NVIDIA_L4\", \"None\"] {isTemplate: true}\n",
|
||||
|
||||
@@ -104,7 +104,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -104,7 +104,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
@@ -164,7 +164,7 @@
|
||||
"HF_TOKEN = \"\" # @param {type:\"string\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"# The pre-built vLLM serving docker image.\n",
|
||||
"VLLM_DOCKER_URI = \"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20250905_0916_RC01\"\n",
|
||||
"VLLM_DOCKER_URI = \"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20251205_0916_RC01\"\n",
|
||||
"SERVING_CONTAINER_IMAGE_URI = VLLM_DOCKER_URI\n",
|
||||
"LABEL = \"vllm\"\n",
|
||||
"\n",
|
||||
|
||||
@@ -120,7 +120,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -113,7 +113,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -165,14 +165,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -329,6 +334,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -338,7 +355,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -362,7 +379,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/pytorch-inference.cu125.0-4.ubuntu2204.py310\",\n",
|
||||
@@ -372,6 +389,25 @@
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -461,7 +497,7 @@
|
||||
"source": [
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
@@ -110,7 +110,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
+4
-1
@@ -148,7 +148,8 @@
|
||||
"! pip install --quiet accelerate==0.31.0\n",
|
||||
"! pip install --quiet transformers==4.43.1\n",
|
||||
"! pip install --quiet datasets==2.19.2\n",
|
||||
"! pip install --quiet tensorflow==2.18.0"
|
||||
"! pip install --quiet tensorflow==2.18.0\n",
|
||||
"! pip install --upgrade --quiet google-cloud-aiplatform==1.130.0"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -1366,6 +1367,7 @@
|
||||
" max_num_seqs: int = 256,\n",
|
||||
" model_type: str = None,\n",
|
||||
" enable_llama_tool_parser: bool = False,\n",
|
||||
" is_spot: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys trained models with vLLM into Vertex AI.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
@@ -1460,6 +1462,7 @@
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" service_account=service_account,\n",
|
||||
" spot=is_spot,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_llama3_1_finetuning_with_workbench.ipynb\",\n",
|
||||
" \"NOTEBOOK_ENVIRONMENT\": get_deploy_source(),\n",
|
||||
|
||||
@@ -126,7 +126,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
File diff suppressed because it is too large
Load Diff
@@ -104,7 +104,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -81,7 +81,16 @@
|
||||
"id": "hQJWRopioSKT"
|
||||
},
|
||||
"source": [
|
||||
"## Before you begin"
|
||||
"## Get Started"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "6T2VvUfGuIBR"
|
||||
},
|
||||
"source": [
|
||||
"### Install Vertex AI SDK and other required packages"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -89,57 +98,102 @@
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "J_jmxcIZoSxU"
|
||||
"id": "RP_QxjjOuJEN"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Setup Google Cloud project\n",
|
||||
"%pip install --upgrade --force-reinstall --quiet 'google-cloud-aiplatform>=1.106.0' 'openai' 'google-auth==2.27.0' 'requests==2.32.3'"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "XQX067YQuR52"
|
||||
},
|
||||
"source": [
|
||||
"### Authenticate the Notebook Environment (Colab only)\n",
|
||||
"\n",
|
||||
"# Upgrade Vertex AI SDK.\n",
|
||||
"! git clone https://github.com/GoogleCloudPlatform/vertex-ai-samples.git\n",
|
||||
"If you're running this notebook in Google Colab, run the following cell to authenticate."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "--J8-VF2uSz-"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import sys\n",
|
||||
"\n",
|
||||
"import importlib\n",
|
||||
"if \"google.colab\" in sys.modules:\n",
|
||||
" from google.colab import auth\n",
|
||||
"\n",
|
||||
" auth.authenticate_user()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "aHBFS55quUi-"
|
||||
},
|
||||
"source": [
|
||||
"### Set Google Cloud Project Information\n",
|
||||
"\n",
|
||||
"To get started with Vertex AI, ensure you have an existing Google Cloud project and that the [Vertex AI API is enabled](https://console.cloud.google.com/flows/enableapi?apiid=aiplatform.googleapis.com).\n",
|
||||
"\n",
|
||||
"See the guide on [setting up your project and development environment](https://cloud.google.com/vertex-ai/docs/start/cloud-environment). Also confirm that [billing is enabled](https://cloud.google.com/billing/docs/how-to/modify-project)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "4ybYR342uWjt"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Use the environment variable if the user doesn't provide Project ID.\n",
|
||||
"import os\n",
|
||||
"from typing import Tuple\n",
|
||||
"\n",
|
||||
"from google.cloud import aiplatform\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"# @markdown 1. [Make sure that billing is enabled for your project](https://cloud.google.com/billing/docs/how-to/modify-project).\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"# @markdown 2. **[Optional]** Set region. If not set, the region will be set automatically according to Colab Enterprise environment.\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = \"\" # @param {type:\"string\"}\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
"# @markdown | a3-highgpu-4g | 4 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
"# @markdown | a3-highgpu-8g | 8 NVIDIA_H100_80GB | us-central1, europe-west4, us-west1, asia-southeast1 |\n",
|
||||
"\n",
|
||||
"common_util = importlib.import_module(\n",
|
||||
" \"vertex-ai-samples.notebooks.community.model_garden.docker_source_codes.notebook_util.common_util\"\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"models, endpoints = {}, {}\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"# Get the default cloud project id.\n",
|
||||
"PROJECT_ID = os.environ[\"GOOGLE_CLOUD_PROJECT\"]\n",
|
||||
"\n",
|
||||
"# Get the default region for launching jobs.\n",
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ[\"GOOGLE_CLOUD_REGION\"]\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"# Initialize Vertex AI API.\n",
|
||||
"print(\"Initializing Vertex AI API.\")\n",
|
||||
"aiplatform.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"! gcloud config set project $PROJECT_ID\n",
|
||||
"\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "WBgpWxYLuX-S"
|
||||
},
|
||||
"source": [
|
||||
"### Import libraries"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "GEUuDXUouY7R"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from vertexai import model_garden"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -166,6 +220,16 @@
|
||||
"# @markdown It takes ~20 minutes to complete the deployment.\n",
|
||||
"\n",
|
||||
"MODEL_ID = \"deepseek-r1:1.5b\" # @param [\"deepseek-r1:1.5b\", \"deepseek-r1:671b\"]\n",
|
||||
"if MODEL_ID == \"deepseek-r1:1.5b\":\n",
|
||||
" model = model_garden.OpenModel(\n",
|
||||
" \"deepseek-ai/deepseek-r1@deepseek-r1-distill-qwen-1.5b\"\n",
|
||||
" )\n",
|
||||
"elif MODEL_ID == \"deepseek-r1:671b\":\n",
|
||||
" model = model_garden.OpenModel(\"deepseek-ai/deepseek-r1@deepseek-r1\")\n",
|
||||
"else:\n",
|
||||
" raise ValueError(f\"Unsupported model id: {MODEL_ID}\")\n",
|
||||
"\n",
|
||||
"endpoints = {}\n",
|
||||
"\n",
|
||||
"# The pre-built serving docker image for Ollama.\n",
|
||||
"OLLAMA_DOCKER_URI = \"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/ollama-serve.cu125.0-5.ubuntu2204.py310\"\n",
|
||||
@@ -188,71 +252,17 @@
|
||||
"\n",
|
||||
"context_length = 131072 if \"1.5b\" in MODEL_ID else 16384\n",
|
||||
"\n",
|
||||
"common_util.check_quota(\n",
|
||||
" project_id=PROJECT_ID,\n",
|
||||
" region=REGION,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" is_for_training=False,\n",
|
||||
")\n",
|
||||
"env_vars = {\n",
|
||||
" \"MODEL_ID\": MODEL_ID,\n",
|
||||
" \"CONTEXT_LENGTH\": context_length,\n",
|
||||
"}\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def deploy_model_ollama(\n",
|
||||
" model_name: str,\n",
|
||||
" model_id: str,\n",
|
||||
" publisher: str,\n",
|
||||
" publisher_model_id: str,\n",
|
||||
" context_length: int,\n",
|
||||
" machine_type: str = \"g2-standard-8\",\n",
|
||||
" accelerator_type: str = \"NVIDIA_L4\",\n",
|
||||
" accelerator_count: int = 1,\n",
|
||||
" use_dedicated_endpoint: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys models with Ollama on GPU in Vertex AI.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
" display_name=f\"{model_name}-endpoint\",\n",
|
||||
" dedicated_endpoint_enabled=use_dedicated_endpoint,\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" env_vars = {\n",
|
||||
" \"MODEL_ID\": model_id,\n",
|
||||
" \"CONTEXT_LENGTH\": context_length,\n",
|
||||
" }\n",
|
||||
"\n",
|
||||
" model = aiplatform.Model.upload(\n",
|
||||
" display_name=model_name,\n",
|
||||
" serving_container_image_uri=OLLAMA_DOCKER_URI,\n",
|
||||
" serving_container_ports=[8080],\n",
|
||||
" serving_container_predict_route=\"/generate\",\n",
|
||||
" serving_container_health_route=\"/ping\",\n",
|
||||
" serving_container_environment_variables=env_vars,\n",
|
||||
" model_garden_source_model_name=(\n",
|
||||
" f\"publishers/{publisher}/models/{publisher_model_id}\"\n",
|
||||
" ),\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" model.deploy(\n",
|
||||
" endpoint=endpoint,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=3600,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_ollama_deployment.ipynb\",\n",
|
||||
" \"DEPLOY_SOURCE\": \"notebook\",\n",
|
||||
" },\n",
|
||||
" )\n",
|
||||
" print(\"endpoint_name:\", endpoint.name)\n",
|
||||
"\n",
|
||||
" return model, endpoint\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"models[\"ollama\"], endpoints[\"ollama\"] = deploy_model_ollama(\n",
|
||||
" model_name=common_util.get_job_name_with_datetime(prefix=MODEL_ID),\n",
|
||||
" model_id=MODEL_ID,\n",
|
||||
" publisher=\"deepseek-ai\",\n",
|
||||
" publisher_model_id=\"deepseek-r1\",\n",
|
||||
" context_length=context_length,\n",
|
||||
"endpoints[\"ollama\"] = model.deploy(\n",
|
||||
" serving_container_image_uri=OLLAMA_DOCKER_URI,\n",
|
||||
" serving_container_ports=[8080],\n",
|
||||
" serving_container_predict_route=\"/generate\",\n",
|
||||
" serving_container_health_route=\"/ping\",\n",
|
||||
" serving_container_environment_variables=env_vars,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
@@ -421,16 +431,10 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Delete the models and endpoints\n",
|
||||
"# @markdown Delete the experiment models and endpoints to recycle the resources\n",
|
||||
"# @markdown and avoid unnecessary continuous charges that may incur.\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"# Undeploy model and delete endpoint.\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)\n",
|
||||
"\n",
|
||||
"# Delete models.\n",
|
||||
"for model in models.values():\n",
|
||||
" model.delete()"
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
||||
@@ -0,0 +1,822 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "ur8xi4C7S06n"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Copyright 2025 Google LLC\n",
|
||||
"#\n",
|
||||
"# Licensed under the Apache License, Version 2.0 (the \"License\");\n",
|
||||
"# you may not use this file except in compliance with the License.\n",
|
||||
"# You may obtain a copy of the License at\n",
|
||||
"#\n",
|
||||
"# https://www.apache.org/licenses/LICENSE-2.0\n",
|
||||
"#\n",
|
||||
"# Unless required by applicable law or agreed to in writing, software\n",
|
||||
"# distributed under the License is distributed on an \"AS IS\" BASIS,\n",
|
||||
"# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.\n",
|
||||
"# See the License for the specific language governing permissions and\n",
|
||||
"# limitations under the License."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "JAPoU8Sm5E6e"
|
||||
},
|
||||
"source": [
|
||||
"# Vertex AI Model Garden - Get started with DeepSeek-V3.2 models\n",
|
||||
"\n",
|
||||
"<table align=\"left\">\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://colab.research.google.com/github/GoogleCloudPlatform/vertex-ai-samples/blob/main/notebooks/community/model_garden/model_garden_openai_api_deepseek3_2.ipynb\">\n",
|
||||
" <img src=\"https://cloud.google.com/ml-engine/images/colab-logo-32px.png\" alt=\"Google Colaboratory logo\"><br> Open in Colab\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/colab/import/https:%2F%2Fraw.githubusercontent.com%2FGoogleCloudPlatform%2Fvertex-ai-samples%2Fmain%2Fnotebooks%2Fcommunity%2Fmodel_garden%2Fmodel_garden_openai_api_deepseek3_2.ipynb\"\">\n",
|
||||
" <img width=\"32px\" src=\"https://cloud.google.com/ml-engine/images/colab-enterprise-logo-32px.png\" alt=\"Google Cloud Colab Enterprise logo\"><br> Open in Colab Enterprise\n",
|
||||
" </a>\n",
|
||||
" </td> \n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/workbench/deploy-notebook?download_url=https://raw.githubusercontent.com/GoogleCloudPlatform/vertex-ai-samples/blob/main/notebooks/community/model_garden/model_garden_openai_api_deepseek3_2.ipynb\">\n",
|
||||
" <img src=\"https://lh3.googleusercontent.com/UiNooY4LUgW_oTvpsNhPpQzsstV5W8F7rYgxgGBD85cWJoLmrOzhVs_ksK_vgx40SHs7jCqkTkCk=e14-rj-sc0xffffff-h130-w32\" alt=\"Vertex AI logo\"><br> Open in Workbench\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://github.com/GoogleCloudPlatform/vertex-ai-samples/blob/main/notebooks/community/model_garden/model_garden_openai_api_deepseek3_2.ipynb\">\n",
|
||||
" <img src=\"https://cloud.google.com/ml-engine/images/github-logo-32px.png\" alt=\"GitHub logo\"><br> View on GitHub\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
"</table>"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "tvgnzT1CKxrO"
|
||||
},
|
||||
"source": [
|
||||
"## Overview\n",
|
||||
"\n",
|
||||
"This notebook demonstrates how to get started with using the OpenAI library and demonstrates how to use DeepSeek-V3.2 models as Model-as-service (MaaS) for building translation chain and document question-answer.\n",
|
||||
"\n",
|
||||
"### Objective\n",
|
||||
"\n",
|
||||
"- Configure OpenAI SDK for the DeepSeek-V3.2 Completions API\n",
|
||||
"- Chat with DeepSeek-V3.2 models with different prompts and model parameters, and apply Llama Guard for safeguarding\n",
|
||||
"- Build with DeepSeek-V3.2 models\n",
|
||||
" - Translation Chain.\n",
|
||||
"\n",
|
||||
"### Costs\n",
|
||||
"\n",
|
||||
"This tutorial uses billable components of Google Cloud:\n",
|
||||
"\n",
|
||||
"* Vertex AI\n",
|
||||
"* Cloud Storage\n",
|
||||
"\n",
|
||||
"Learn about [Vertex AI pricing](https://cloud.google.com/vertex-ai/pricing), [Cloud Storage pricing](https://cloud.google.com/storage/pricing), and use the [Pricing Calculator](https://cloud.google.com/products/calculator/) to generate a cost estimate based on your projected usage."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "61RBz8LLbxCR"
|
||||
},
|
||||
"source": [
|
||||
"## Get started"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "No17Cw5hgx12"
|
||||
},
|
||||
"source": [
|
||||
"### Install Vertex AI SDK for Python and other required packages\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "tFy3H3aPgx12"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"! pip3 install --upgrade --quiet google-cloud-aiplatform[langchain] openai\n",
|
||||
"! pip3 install --upgrade --quiet langchain-openai"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "R5Xep4W9lq-Z"
|
||||
},
|
||||
"source": [
|
||||
"### Restart runtime (Colab only)\n",
|
||||
"\n",
|
||||
"To use the newly installed packages, you must restart the runtime on Google Colab."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "XRvKdaPDTznN"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import sys\n",
|
||||
"\n",
|
||||
"if \"google.colab\" in sys.modules:\n",
|
||||
"\n",
|
||||
" import IPython\n",
|
||||
"\n",
|
||||
" app = IPython.Application.instance()\n",
|
||||
" app.kernel.do_shutdown(True)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "SbmM4z7FOBpM"
|
||||
},
|
||||
"source": [
|
||||
"<div class=\"alert alert-block alert-warning\">\n",
|
||||
"<b>⚠️ The kernel is going to restart. Wait until it's finished before continuing to the next step. ⚠️</b>\n",
|
||||
"</div>\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "dmWOrTJ3gx13"
|
||||
},
|
||||
"source": [
|
||||
"### Authenticate your notebook environment (Colab only)\n",
|
||||
"\n",
|
||||
"Authenticate your environment on Google Colab.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "NyKGtVQjgx13"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import sys\n",
|
||||
"\n",
|
||||
"if \"google.colab\" in sys.modules:\n",
|
||||
"\n",
|
||||
" from google.colab import auth\n",
|
||||
"\n",
|
||||
" auth.authenticate_user()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "DF4l8DTdWgPY"
|
||||
},
|
||||
"source": [
|
||||
"### Set Google Cloud project information\n",
|
||||
"\n",
|
||||
"To get started using Vertex AI, you must have an existing Google Cloud project and [enable the Vertex AI API](https://console.cloud.google.com/flows/enableapi?apiid=aiplatform.googleapis.com). Learn more about [setting up a project and a development environment](https://cloud.google.com/vertex-ai/docs/start/cloud-environment)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "Nqwi-5ufWp_B"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"PROJECT_ID = \"<YOUR PROJECT ID>\" # @param {type:\"string\"}\n",
|
||||
"\n",
|
||||
"LOCATION = \"global\" # @param {type:\"string\"}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "jVYoyDl165EE"
|
||||
},
|
||||
"source": [
|
||||
"### Import libraries\n",
|
||||
"\n",
|
||||
"Import libraries to use in this tutorial."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "c1tEW-U968h8"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Chat completions API\n",
|
||||
"import openai\n",
|
||||
"from google.auth import default, transport\n",
|
||||
"from langchain import PromptTemplate\n",
|
||||
"# Build\n",
|
||||
"from langchain_openai import ChatOpenAI"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "uqYCG2Fw7D3L"
|
||||
},
|
||||
"source": [
|
||||
"### Configure OpenAI SDK for the DeepSeek-V3.2 Chat Completions API\n",
|
||||
"\n",
|
||||
"To configure the OpenAI SDK for the DeepSeek-V3.2 Chat Completions API, you need to request the access token and initialize the client pointing to the DeepSeek-V3.2 endpoint.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "W0K6VSJRHhH2"
|
||||
},
|
||||
"source": [
|
||||
"#### Authentication\n",
|
||||
"\n",
|
||||
"You can request an access token from the default credentials for the current environment. Note that the access token lives for [1 hour by default](https://cloud.google.com/docs/authentication/token-types#at-lifetime); after expiration, it must be refreshed.\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "i0qceuiQEPHv"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"credentials, _ = default()\n",
|
||||
"auth_request = transport.requests.Request()\n",
|
||||
"credentials.refresh(auth_request)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Q04wJmA0HT6X"
|
||||
},
|
||||
"source": [
|
||||
"Then configure the OpenAI SDK to point to the DeepSeek-V3.2 Chat Completions API endpoint.\n",
|
||||
"\n",
|
||||
"Notice, only `global` is supported region for DeepSeek-V3.2 models using Model-as-a-Service (MaaS)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "c-MRhsnlj6iw"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"MODEL_LOCATION = \"global\"\n",
|
||||
"\n",
|
||||
"client = openai.OpenAI(\n",
|
||||
" base_url=f\"https://aiplatform.googleapis.com/v1/projects/{PROJECT_ID}/locations/{MODEL_LOCATION}/endpoints/openapi/chat/completions?\",\n",
|
||||
" api_key=credentials.token,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "UGokrtdiIHrX"
|
||||
},
|
||||
"source": [
|
||||
"#### DeepSeek-V3.2 Model\n",
|
||||
"\n",
|
||||
"This tutorial uses DeepSeek-V3.2 using Model-as-a-Service (MaaS). Using Model-as-a-Service (MaaS), you can access DeepSeek-V3.2 model in just a few clicks without any setup or infrastructure hassles. Model-as-a-Service (MaaS) integrates [Llama Guard](https://huggingface.co/meta-llama/Llama-Guard-3-8B) as a safety filter. It is switched on by default and can be switched off. Llama Guard enables us to safeguard model inputs and outputs. If a response is filtered, it will be populated with a `finish_reason` field (with value `content_filtered`) and a `refusal` field (stating the filtering reason)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "r7OhyH46H2H5"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"MODEL_ID = \"deepseek-ai/deepseek-v3.2-maas\" # @param {type:\"string\"} [\"deepseek-ai/deepseek-v3.2-maas\"]"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "1xD62NTpqHXd"
|
||||
},
|
||||
"source": [
|
||||
"### Chat with DeepSeek-V3.2\n",
|
||||
"\n",
|
||||
"Use the Chat Completions API to send a request to the DeepSeek-V3.2model."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "tkyp9kZSuJGx"
|
||||
},
|
||||
"source": [
|
||||
"#### Hello, DeepSeek-V3.2!"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "CKVOZ1HEqRbY"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"apply_llama_guard = True # @param {type:\"boolean\"}\n",
|
||||
"\n",
|
||||
"response = client.chat.completions.create(\n",
|
||||
" model=MODEL_ID,\n",
|
||||
" messages=[{\"role\": \"user\", \"content\": \"Hello, Deepseek!\"}],\n",
|
||||
" extra_body={\n",
|
||||
" \"extra_body\": {\n",
|
||||
" \"google\": {\n",
|
||||
" \"model_safety_settings\": {\n",
|
||||
" \"enabled\": apply_llama_guard,\n",
|
||||
" \"llama_guard_settings\": {},\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
" },\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "LxpdxYCxH51u"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"print(response.choices[0].message.content)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "B1rKbHUQt605"
|
||||
},
|
||||
"source": [
|
||||
"#### Ask DeepSeek-V3.2 using different model configuration\n",
|
||||
"\n",
|
||||
"Use the following parameters to generate different answers:\n",
|
||||
"\n",
|
||||
"* `temperature` to control the randomness of the response\n",
|
||||
"* `max_tokens` to limit the response length\n",
|
||||
"* `top_p` to control the quality of the response\n",
|
||||
"* `stream` to stream the response back or not\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "owv-5Sz5rIEU"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"temperature = 1.0 # @param {type:\"number\"}\n",
|
||||
"max_tokens = 256 # @param {type:\"integer\"}\n",
|
||||
"top_p = 1.0 # @param {type:\"number\"}\n",
|
||||
"stream = True # @param {type:\"boolean\"}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "a-qBuhcK-G1V"
|
||||
},
|
||||
"source": [
|
||||
"Get the answer."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "O1YU8bSivH0B"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"apply_llama_guard = True # @param {type:\"boolean\"}\n",
|
||||
"\n",
|
||||
"response = client.chat.completions.create(\n",
|
||||
" model=MODEL_ID,\n",
|
||||
" messages=[\n",
|
||||
" {\"role\": \"user\", \"content\": \"What is Vertex AI?\"},\n",
|
||||
" {\"role\": \"assistant\", \"content\": \"Sure, Vertex AI is:\"},\n",
|
||||
" ],\n",
|
||||
" temperature=temperature,\n",
|
||||
" max_tokens=max_tokens,\n",
|
||||
" top_p=top_p,\n",
|
||||
" stream=stream,\n",
|
||||
" extra_body={\n",
|
||||
" \"extra_body\": {\n",
|
||||
" \"google\": {\n",
|
||||
" \"model_safety_settings\": {\n",
|
||||
" \"enabled\": apply_llama_guard,\n",
|
||||
" \"llama_guard_settings\": {},\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
" },\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-o9-gF0U-Kba"
|
||||
},
|
||||
"source": [
|
||||
"Depending if `stream` parameter is enabled or not, you can print the response entirely or chunk by chunk."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "CoDHLGhyyt8d"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if stream:\n",
|
||||
" for chunk in response:\n",
|
||||
" if chunk.choices:\n",
|
||||
" print(chunk.choices[0].delta.content, end=\"\")\n",
|
||||
"else:\n",
|
||||
" print(response.choices[0].message.content)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "BkoaelaKxm1r"
|
||||
},
|
||||
"source": [
|
||||
"#### Use DeepSeek-V3.2 with different tasks\n",
|
||||
"\n",
|
||||
"In this section, you will use DeepSeek-V3.2 to perform different tasks including text generation, text summarization, and code generation.\n",
|
||||
"\n",
|
||||
"For each task, you'll define a different prompt and submit a request to the model as you did before."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-en7AYQDyONt"
|
||||
},
|
||||
"source": [
|
||||
"##### Text Generation"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "QANInNvizWbi"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"prompt = \"Write a poem about a cat who loves to code\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "2x8ML1Y_yfom"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"apply_llama_guard = True # @param {type:\"boolean\"}\n",
|
||||
"\n",
|
||||
"response = client.chat.completions.create(\n",
|
||||
" model=MODEL_ID,\n",
|
||||
" messages=[\n",
|
||||
" {\"role\": \"user\", \"content\": prompt},\n",
|
||||
" ],\n",
|
||||
" extra_body={\n",
|
||||
" \"extra_body\": {\n",
|
||||
" \"google\": {\n",
|
||||
" \"model_safety_settings\": {\n",
|
||||
" \"enabled\": apply_llama_guard,\n",
|
||||
" \"llama_guard_settings\": {},\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
" },\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "qQ6UUgpHztXZ"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"print(response.choices[0].message.content)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "kBLESIw4zhto"
|
||||
},
|
||||
"source": [
|
||||
"##### Text summarization"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "UrAybklfzhtz"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"article = \"\"\"\n",
|
||||
"Vertex AI: Google's Unified Platform for Machine Learning\n",
|
||||
"\n",
|
||||
"Google Cloud's Vertex AI is a comprehensive platform that simplifies the process of building, deploying, and managing machine learning (ML) models and AI applications. It provides a single environment for all your AI needs, from data preparation to model deployment and monitoring.\n",
|
||||
"\n",
|
||||
"Vertex AI offers a range of features to cater to various user levels, including:\n",
|
||||
"\n",
|
||||
"AutoML: This feature allows you to train models on tabular, image, text, or video data without writing code. It's ideal for users without extensive ML expertise.\n",
|
||||
"Custom Training: For advanced users, Vertex AI provides custom training options, allowing you to use your preferred ML framework and write your own code.\n",
|
||||
"Model Garden: This feature lets you discover, test, and deploy pre-trained models from Vertex AI and open-source sources.\n",
|
||||
"Generative AI: Access Google's powerful large language models (LLMs) to generate text, code, images, and speech, which can be customized and deployed for your applications.\n",
|
||||
"Vertex AI seamlessly integrates with other Google Cloud services like BigQuery for data warehousing, Cloud Storage for data management, and Cloud AI Platform for custom model training. It provides managed infrastructure that can be tailored to your performance and budget needs.\n",
|
||||
"\n",
|
||||
"Whether you're a seasoned data scientist or just starting out with AI, Vertex AI simplifies the entire ML lifecycle and empowers you to build and deploy AI solutions effectively.\n",
|
||||
"\"\"\"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"prompt = (\"Summarize the following article in one sentence: \" + article).replace(\n",
|
||||
" \"\\n\", \"\"\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "VJYIZbGyzhtz"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"apply_llama_guard = True # @param {type:\"boolean\"}\n",
|
||||
"\n",
|
||||
"response = client.chat.completions.create(\n",
|
||||
" model=MODEL_ID,\n",
|
||||
" messages=[\n",
|
||||
" {\"role\": \"user\", \"content\": prompt},\n",
|
||||
" ],\n",
|
||||
" extra_body={\n",
|
||||
" \"extra_body\": {\n",
|
||||
" \"google\": {\n",
|
||||
" \"model_safety_settings\": {\n",
|
||||
" \"enabled\": apply_llama_guard,\n",
|
||||
" \"llama_guard_settings\": {},\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
" },\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "9vfWA2i9zwOZ"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"print(response.choices[0].message.content)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-_mNB0Fezh6G"
|
||||
},
|
||||
"source": [
|
||||
"##### Code generation"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "ltbhrGiwzh6H"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"prompt = \"Write a Python function that takes a list of numbers and returns the average. Include error handling for empty lists.\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "q66yE4Pszh6H"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"apply_llama_guard = True # @param {type:\"boolean\"}\n",
|
||||
"\n",
|
||||
"response = client.chat.completions.create(\n",
|
||||
" model=MODEL_ID,\n",
|
||||
" messages=[\n",
|
||||
" {\"role\": \"user\", \"content\": prompt},\n",
|
||||
" ],\n",
|
||||
" extra_body={\n",
|
||||
" \"extra_body\": {\n",
|
||||
" \"google\": {\n",
|
||||
" \"model_safety_settings\": {\n",
|
||||
" \"enabled\": apply_llama_guard,\n",
|
||||
" \"llama_guard_settings\": {},\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
" }\n",
|
||||
" },\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "mcAf5tXrtPIu"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"print(response.choices[0].message.content)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "gnrXpv5Y3yFK"
|
||||
},
|
||||
"source": [
|
||||
"### Build with DeepSeek-V3.2\n",
|
||||
"\n",
|
||||
"In this section, you use DeepSeek-V3.2 to build a translation simple applications.\n",
|
||||
"\n",
|
||||
"**Translation Chain** to translate text across multiple languages using DeepSeek-V3.2 and LangChain Expression Language (LCEL).\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "IowGcZq95HqZ"
|
||||
},
|
||||
"source": [
|
||||
"#### Translation chain\n",
|
||||
"\n",
|
||||
"In this scenario, you use LangChain Expression Language (LCEL) to build a simple chain which translates some `text_to_translate` to the specified `target_language`."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "yLAwaYPzFqDQ"
|
||||
},
|
||||
"source": [
|
||||
"##### Initialize the chat interface and the translation prompt template using LangChain"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "CE2KxIrG5xKC"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"llm = ChatOpenAI(\n",
|
||||
" model=MODEL_ID,\n",
|
||||
" base_url=f\"https://aiplatform.googleapis.com/v1/projects/{PROJECT_ID}/locations/{MODEL_LOCATION}/endpoints/openapi/chat/completions?\",\n",
|
||||
" api_key=credentials.token,\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"template = \"\"\"Translate the following {text} to {target_language}:\"\"\"\n",
|
||||
"\n",
|
||||
"prompt = PromptTemplate(input_variables=[\"text\", \"target_language\"], template=template)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "odTLqzLiF8h_"
|
||||
},
|
||||
"source": [
|
||||
"##### Initialize the chain"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "74Mywe4W9MmE"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"chain = prompt | llm"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "QE3sizbzGFER"
|
||||
},
|
||||
"source": [
|
||||
"##### Translate a text"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "SRJ-xuSI9ZQl"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"text_to_translate = \"Hello Deepseek!\" # @param {type:\"string\"}\n",
|
||||
"target_language = \"Italian\" # @param {type:\"string\"}\n",
|
||||
"\n",
|
||||
"response = chain.invoke({\"text\": text_to_translate, \"target_language\": target_language})"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "yYzc1kCjEHGP"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"print(response.content)"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "model_garden_openai_api_deepseek3_2.ipynb",
|
||||
"toc_visible": true
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
@@ -104,7 +104,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -49,37 +49,48 @@
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "iJs8Mk6Vd3gb"
|
||||
"id": "3de7470326a2"
|
||||
},
|
||||
"source": [
|
||||
"## Overview\n",
|
||||
"\n",
|
||||
"This notebook demonstrates deploying prebuilt [Phi-4 models](https://huggingface.co/collections/microsoft/phi-4-677e9380e514feb5577a40e4) with [vLLM](https://github.com/vllm-project/vllm) and [HexLLM](https://cloud.google.com/vertex-ai/generative-ai/docs/open-models/use-hex-llm?hl=en) to improve serving throughput.\n",
|
||||
"This notebook demonstrates how to deploy a **Phi-4** open model on Google Cloud Vertex AI.\n",
|
||||
"\n",
|
||||
"### Objectives\n",
|
||||
"\n",
|
||||
"### Objective\n",
|
||||
"- Deploy Phi-4 using containerized backends like [vLLM](https://github.com/vllm-project/vllm) on GPU.\n",
|
||||
"- Use the deployed model to serve chat completion requests for both text and multimodal inputs.\n",
|
||||
"\n",
|
||||
"- Download and deploy prebuilt Phi-4 models\n",
|
||||
"- Deploy Phi-4 with [vLLM](https://github.com/vllm-project/vllm) to improve serving throughput\n",
|
||||
"- Deploy Phi-4 with [HexLLM](https://cloud.google.com/vertex-ai/generative-ai/docs/open-models/use-hex-llm?hl=en)\n",
|
||||
"### File a Bug\n",
|
||||
"\n",
|
||||
"If you encounter issues with this notebook, report them on [GitHub](https://github.com/GoogleCloudPlatform/vertex-ai-samples/issues/new).\n",
|
||||
"\n",
|
||||
"### Costs\n",
|
||||
"\n",
|
||||
"This tutorial uses billable components of Google Cloud:\n",
|
||||
"\n",
|
||||
"* Vertex AI\n",
|
||||
"* Cloud Storage\n",
|
||||
"- Vertex AI\n",
|
||||
"- Cloud Storage\n",
|
||||
"\n",
|
||||
"Learn about [Vertex AI pricing](https://cloud.google.com/vertex-ai/pricing), [Cloud Storage pricing](https://cloud.google.com/storage/pricing), and use the [Pricing Calculator](https://cloud.google.com/products/calculator/) to generate a cost estimate based on your projected usage."
|
||||
"Refer to the [Vertex AI pricing](https://cloud.google.com/vertex-ai/pricing) and [Cloud Storage pricing](https://cloud.google.com/storage/pricing) pages for more information. Use the [Pricing Calculator](https://cloud.google.com/products/calculator/) to estimate your projected costs."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Cj84x0OUd3gb"
|
||||
"id": "jeYw-Czg-DFy"
|
||||
},
|
||||
"source": [
|
||||
"## Before you begin"
|
||||
"## Get Started"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "KgyhGvEzBDkj"
|
||||
},
|
||||
"source": [
|
||||
"### Install Vertex AI SDK and other required packages"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -87,116 +98,90 @@
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "0QATZfrLd3gb"
|
||||
"id": "iCacdLqG-IsH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Setup Google Cloud project\n",
|
||||
"%pip install --upgrade --force-reinstall --quiet 'google-cloud-aiplatform>=1.106.0' 'openai' 'google-auth==2.27.0' 'requests==2.32.3'"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "HUKCrpBy-3yf"
|
||||
},
|
||||
"source": [
|
||||
"### Authenticate the Notebook Environment (Colab only)\n",
|
||||
"\n",
|
||||
"# @markdown 1. [Make sure that billing is enabled for your project](https://cloud.google.com/billing/docs/how-to/modify-project).\n",
|
||||
"If you're running this notebook in Google Colab, run the following cell to authenticate."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "JXwCT1kn-3Gu"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import sys\n",
|
||||
"\n",
|
||||
"# @markdown 2. **[Optional]** [Create a Cloud Storage bucket](https://cloud.google.com/storage/docs/creating-buckets) for storing experiment outputs. Set the BUCKET_URI for the experiment environment. The specified Cloud Storage bucket (`BUCKET_URI`) should be located in the same region as where the notebook was launched. Note that a multi-region bucket (eg. \"us\") is not considered a match for a single region covered by the multi-region range (eg. \"us-central1\"). If not set, a unique GCS bucket will be created instead.\n",
|
||||
"if \"google.colab\" in sys.modules:\n",
|
||||
" from google.colab import auth\n",
|
||||
"\n",
|
||||
"BUCKET_URI = \"gs://\" # @param {type:\"string\"}\n",
|
||||
" auth.authenticate_user()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "AcW2nwB8-7yC"
|
||||
},
|
||||
"source": [
|
||||
"### Set Google Cloud Project Information\n",
|
||||
"\n",
|
||||
"# @markdown 3. **[Optional]** Set region. If not set, the region will be set automatically according to Colab Enterprise environment.\n",
|
||||
"To get started with Vertex AI, ensure you have an existing Google Cloud project and that the [Vertex AI API is enabled](https://console.cloud.google.com/flows/enableapi?apiid=aiplatform.googleapis.com).\n",
|
||||
"\n",
|
||||
"REGION = \"\" # @param {type:\"string\"}\n",
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
"# @markdown | a3-highgpu-4g | 4 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
"# @markdown | a3-highgpu-8g | 8 NVIDIA_H100_80GB | us-central1, europe-west4, us-west1, asia-southeast1 |\n",
|
||||
"\n",
|
||||
"# Import the necessary packages\n",
|
||||
"import datetime\n",
|
||||
"import importlib\n",
|
||||
"See the guide on [setting up your project and development environment](https://cloud.google.com/vertex-ai/docs/start/cloud-environment). Also confirm that [billing is enabled](https://cloud.google.com/billing/docs/how-to/modify-project).\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "eIVLp0oE--k-"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Use the environment variable if the user doesn't provide Project ID.\n",
|
||||
"import os\n",
|
||||
"import uuid\n",
|
||||
"from typing import Tuple\n",
|
||||
"\n",
|
||||
"from google.cloud import aiplatform\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"! git clone https://github.com/GoogleCloudPlatform/vertex-ai-samples.git\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"models, endpoints = {}, {}\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"common_util = importlib.import_module(\n",
|
||||
" \"vertex-ai-samples.notebooks.community.model_garden.docker_source_codes.notebook_util.common_util\"\n",
|
||||
")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"# Get the default cloud project id.\n",
|
||||
"PROJECT_ID = os.environ[\"GOOGLE_CLOUD_PROJECT\"]\n",
|
||||
"\n",
|
||||
"# Get the default region for launching jobs.\n",
|
||||
"if not REGION:\n",
|
||||
" if not os.environ.get(\"GOOGLE_CLOUD_REGION\"):\n",
|
||||
" raise ValueError(\n",
|
||||
" \"REGION must be set. See\"\n",
|
||||
" \" https://cloud.google.com/vertex-ai/docs/general/locations for\"\n",
|
||||
" \" available cloud locations.\"\n",
|
||||
" )\n",
|
||||
" REGION = os.environ[\"GOOGLE_CLOUD_REGION\"]\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"# Enable the Vertex AI API and Compute Engine API, if not already.\n",
|
||||
"print(\"Enabling Vertex AI API and Compute Engine API.\")\n",
|
||||
"! gcloud services enable aiplatform.googleapis.com compute.googleapis.com\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"# Cloud Storage bucket for storing the experiment artifacts.\n",
|
||||
"# A unique GCS bucket will be created for the purpose of this notebook. If you\n",
|
||||
"# prefer using your own GCS bucket, change the value yourself below.\n",
|
||||
"now = datetime.datetime.now().strftime(\"%Y%m%d%H%M%S\")\n",
|
||||
"BUCKET_NAME = \"/\".join(BUCKET_URI.split(\"/\")[:3])\n",
|
||||
"\n",
|
||||
"if BUCKET_URI is None or BUCKET_URI.strip() == \"\" or BUCKET_URI == \"gs://\":\n",
|
||||
" BUCKET_URI = f\"gs://{PROJECT_ID}-tmp-{now}-{str(uuid.uuid4())[:4]}\"\n",
|
||||
" BUCKET_NAME = \"/\".join(BUCKET_URI.split(\"/\")[:3])\n",
|
||||
" ! gsutil mb -l {REGION} {BUCKET_URI}\n",
|
||||
"else:\n",
|
||||
" assert BUCKET_URI.startswith(\"gs://\"), \"BUCKET_URI must start with `gs://`.\"\n",
|
||||
" shell_output = ! gsutil ls -Lb {BUCKET_NAME} | grep \"Location constraint:\" | sed \"s/Location constraint://\"\n",
|
||||
" bucket_region = shell_output[0].strip().lower()\n",
|
||||
" if bucket_region != REGION:\n",
|
||||
" raise ValueError(\n",
|
||||
" \"Bucket region %s is different from notebook region %s\"\n",
|
||||
" % (bucket_region, REGION)\n",
|
||||
" )\n",
|
||||
"print(f\"Using this GCS Bucket: {BUCKET_URI}\")\n",
|
||||
"\n",
|
||||
"STAGING_BUCKET = os.path.join(BUCKET_URI, \"temporal\")\n",
|
||||
"MODEL_BUCKET = os.path.join(BUCKET_URI, \"phi4\")\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"# Initialize Vertex AI API.\n",
|
||||
"print(\"Initializing Vertex AI API.\")\n",
|
||||
"aiplatform.init(project=PROJECT_ID, location=REGION, staging_bucket=STAGING_BUCKET)\n",
|
||||
"\n",
|
||||
"# Gets the default SERVICE_ACCOUNT.\n",
|
||||
"shell_output = ! gcloud projects describe $PROJECT_ID\n",
|
||||
"project_number = shell_output[-1].split(\":\")[1].strip().replace(\"'\", \"\")\n",
|
||||
"SERVICE_ACCOUNT = f\"{project_number}-compute@developer.gserviceaccount.com\"\n",
|
||||
"print(\"Using this default Service Account:\", SERVICE_ACCOUNT)\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"# Provision permissions to the SERVICE_ACCOUNT with the GCS bucket\n",
|
||||
"! gsutil iam ch serviceAccount:{SERVICE_ACCOUNT}:roles/storage.admin $BUCKET_NAME\n",
|
||||
"\n",
|
||||
"! gcloud config set project $PROJECT_ID\n",
|
||||
"! gcloud projects add-iam-policy-binding --no-user-output-enabled {PROJECT_ID} --member=serviceAccount:{SERVICE_ACCOUNT} --role=\"roles/storage.admin\"\n",
|
||||
"! gcloud projects add-iam-policy-binding --no-user-output-enabled {PROJECT_ID} --member=serviceAccount:{SERVICE_ACCOUNT} --role=\"roles/aiplatform.user\""
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "czbg_Jfed3gb"
|
||||
"id": "Q0CXrvcZH_aw"
|
||||
},
|
||||
"source": [
|
||||
"## Deploy prebuilt Phi-4 models with vLLM"
|
||||
"### Import libraries"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -204,230 +189,233 @@
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "I-xYEPgVd3gb"
|
||||
"id": "3G2UXB82ICs6"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Deploy\n",
|
||||
"from vertexai import model_garden"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "upYRiGtP_-iN"
|
||||
},
|
||||
"source": [
|
||||
"## Deploy model"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "H2WC_0hXDVXc"
|
||||
},
|
||||
"source": [
|
||||
"### Choose model variant"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "u41zbNa2EoFq"
|
||||
},
|
||||
"source": [
|
||||
"You can proceed with the default model variant or select a different one."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "-fgC4NLSDkF7"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model_version = \"phi-4\" # @param [\"phi-4\", \"phi-4-reasoning\", \"phi-4-reasoning-plus\"] {isTemplate:true}\n",
|
||||
"MODEL_NAME = f\"microsoft/phi4@{model_version}\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "VRnUgU8LF3_i"
|
||||
},
|
||||
"source": [
|
||||
"To see all deployable model variants available in Model Garden, use:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "-QLd-wshF6sB"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"all_model_versions = model_garden.list_deployable_models(\n",
|
||||
" model_filter=\"phi4\", list_hf_models=False\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "N0UeFHa2GO63"
|
||||
},
|
||||
"source": [
|
||||
"Once you've selected a model variant, initialize it:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "GZiV3trBBcA3"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model = model_garden.OpenModel(MODEL_NAME)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-0cL378wFlvf"
|
||||
},
|
||||
"source": [
|
||||
"### Check the Deployment Configuration\n",
|
||||
"\n",
|
||||
"# @markdown This section uploads prebuilt the Phi-4 model to Model Registry and deploys it to a Vertex AI Endpoint.\n",
|
||||
"Use the `list_deploy_options()` method to view the verified deployment configurations for your selected model. This helps ensure you have sufficient resources (e.g., GPU quota) available to deploy it."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "zm73g7vFFm9N"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"deploy_options = model.list_deploy_options(concise=True)\n",
|
||||
"print(deploy_options)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "WjV499VsGwrD"
|
||||
},
|
||||
"source": [
|
||||
"### Deploy the Model\n",
|
||||
"\n",
|
||||
"# @markdown The Phi-4 model may take 15-30 minutes to deploy.\n",
|
||||
"Now that you’ve reviewed the deployment options, use the `deploy()` method to serve the selected open model to a Vertex AI endpoint. Deployment time may vary depending on the model size and infrastructure requirements.\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"# @markdown | Model Version | Default Max Model Length | Available GPU configurations |\n",
|
||||
"# @markdown |----------------------------|------------------|-----------------------------|\n",
|
||||
"# @markdown | Phi-4 | 16384 | 1 NVIDIA_A100 80GB a2-ultragpu-1g, 2 NVIDIA_L4 g2-standard-24 |\n",
|
||||
"# @markdown | Phi-4-reasoning | 32768 | 1 NVIDIA_A100 80GB a2-ultragpu-1g, 1 NVIDIA_H100 80GB a3-highgpu-1g |\n",
|
||||
"# @markdown | Phi-4-reasoning-plus | 32768 | 1 NVIDIA_A100 80GB a2-ultragpu-1g, 1 NVIDIA_H100 80GB a3-highgpu-1g |\n",
|
||||
"\n",
|
||||
"# The pre-built serving docker images.\n",
|
||||
"VLLM_DOCKER_URI = \"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20250417_0916_RC01\"\n",
|
||||
"\n",
|
||||
"MODEL_ID = \"Phi-4\" # @param [\"Phi-4\", \"Phi-4-reasoning\", \"Phi-4-reasoning-plus\"] {isTemplate:true}\n",
|
||||
"model_path_prefix = \"microsoft\"\n",
|
||||
"model_id = os.path.join(model_path_prefix, MODEL_ID)\n",
|
||||
"\n",
|
||||
"accelerator_type = \"NVIDIA_L4\" # @param [\"NVIDIA_L4\", \"NVIDIA_A100_80GB\", \"NVIDIA_H100_80GB\"] {isTemplate: true}\n",
|
||||
"machine_type = None\n",
|
||||
"vllm_dtype = \"bfloat16\"\n",
|
||||
"accelerator_count = None\n",
|
||||
"max_model_len = None\n",
|
||||
"gpu_memory_utilization = None\n",
|
||||
"enable_trust_remote_code = False\n",
|
||||
"\n",
|
||||
"if \"Phi-4-reasoning\" in MODEL_ID:\n",
|
||||
" max_model_len = 32768\n",
|
||||
" if accelerator_type == \"NVIDIA_A100_80GB\":\n",
|
||||
" accelerator_count = 1\n",
|
||||
" machine_type = \"a2-ultragpu-1g\"\n",
|
||||
" gpu_memory_utilization = 0.85\n",
|
||||
" elif accelerator_type == \"NVIDIA_H100_80GB\":\n",
|
||||
" accelerator_count = 1\n",
|
||||
" machine_type = \"a3-highgpu-1g\"\n",
|
||||
" gpu_memory_utilization = 0.85\n",
|
||||
" else:\n",
|
||||
" raise ValueError(\n",
|
||||
" \"Recommended machine settings not found for accelerator type: %s\"\n",
|
||||
" % accelerator_type\n",
|
||||
" )\n",
|
||||
"elif \"Phi-4\" == MODEL_ID:\n",
|
||||
" max_model_len = 16384\n",
|
||||
" if accelerator_type == \"NVIDIA_L4\":\n",
|
||||
" accelerator_count = 2\n",
|
||||
" machine_type = \"g2-standard-24\"\n",
|
||||
" gpu_memory_utilization = 0.85\n",
|
||||
" elif accelerator_type == \"NVIDIA_A100_80GB\":\n",
|
||||
" accelerator_count = 1\n",
|
||||
" machine_type = \"a2-ultragpu-1g\"\n",
|
||||
" gpu_memory_utilization = 0.85\n",
|
||||
" else:\n",
|
||||
" raise ValueError(\n",
|
||||
" \"Recommended machine settings not found for accelerator type: %s\"\n",
|
||||
" % accelerator_type\n",
|
||||
" )\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"Invalid model id: %s\" % MODEL_ID)\n",
|
||||
"\n",
|
||||
"common_util.check_quota(\n",
|
||||
" project_id=PROJECT_ID,\n",
|
||||
" region=REGION,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" is_for_training=False,\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def deploy_model_vllm(\n",
|
||||
" model_name: str,\n",
|
||||
" model_id: str,\n",
|
||||
" publisher: str,\n",
|
||||
" publisher_model_id: str,\n",
|
||||
" service_account: str,\n",
|
||||
" base_model_id: str = None,\n",
|
||||
" machine_type: str = \"g2-standard-8\",\n",
|
||||
" accelerator_type: str = \"NVIDIA_L4\",\n",
|
||||
" accelerator_count: int = 1,\n",
|
||||
" gpu_memory_utilization: float = 0.9,\n",
|
||||
" max_model_len: int = 4096,\n",
|
||||
" dtype: str = \"auto\",\n",
|
||||
" enable_trust_remote_code: bool = False,\n",
|
||||
" enforce_eager: bool = False,\n",
|
||||
" enable_lora: bool = False,\n",
|
||||
" enable_chunked_prefill: bool = False,\n",
|
||||
" enable_prefix_cache: bool = False,\n",
|
||||
" host_prefix_kv_cache_utilization_target: float = 0.0,\n",
|
||||
" max_loras: int = 1,\n",
|
||||
" max_cpu_loras: int = 8,\n",
|
||||
" use_dedicated_endpoint: bool = False,\n",
|
||||
" max_num_seqs: int = 256,\n",
|
||||
" model_type: str = None,\n",
|
||||
" enable_llama_tool_parser: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys trained models with vLLM into Vertex AI.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
" display_name=f\"{model_name}-endpoint\",\n",
|
||||
" dedicated_endpoint_enabled=use_dedicated_endpoint,\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" if not base_model_id:\n",
|
||||
" base_model_id = model_id\n",
|
||||
"\n",
|
||||
" # See https://docs.vllm.ai/en/latest/models/engine_args.html for a list of possible arguments with descriptions.\n",
|
||||
" vllm_args = [\n",
|
||||
" \"python\",\n",
|
||||
" \"-m\",\n",
|
||||
" \"vllm.entrypoints.api_server\",\n",
|
||||
" \"--host=0.0.0.0\",\n",
|
||||
" \"--port=8080\",\n",
|
||||
" f\"--model={model_id}\",\n",
|
||||
" f\"--tensor-parallel-size={accelerator_count}\",\n",
|
||||
" \"--swap-space=16\",\n",
|
||||
" f\"--max-model-len={max_model_len}\",\n",
|
||||
" f\"--dtype={dtype}\",\n",
|
||||
" f\"--max-loras={max_loras}\",\n",
|
||||
" f\"--max-cpu-loras={max_cpu_loras}\",\n",
|
||||
" f\"--max-num-seqs={max_num_seqs}\",\n",
|
||||
" \"--disable-log-stats\",\n",
|
||||
" ]\n",
|
||||
"\n",
|
||||
" if gpu_memory_utilization:\n",
|
||||
" vllm_args.append(f\"--gpu-memory-utilization={gpu_memory_utilization}\")\n",
|
||||
"\n",
|
||||
" if enable_trust_remote_code:\n",
|
||||
" vllm_args.append(\"--trust-remote-code\")\n",
|
||||
"\n",
|
||||
" if enforce_eager:\n",
|
||||
" vllm_args.append(\"--enforce-eager\")\n",
|
||||
"\n",
|
||||
" if enable_lora:\n",
|
||||
" vllm_args.append(\"--enable-lora\")\n",
|
||||
"\n",
|
||||
" if enable_chunked_prefill:\n",
|
||||
" vllm_args.append(\"--enable-chunked-prefill\")\n",
|
||||
"\n",
|
||||
" if enable_prefix_cache:\n",
|
||||
" vllm_args.append(\"--enable-prefix-caching\")\n",
|
||||
"\n",
|
||||
" if 0 < host_prefix_kv_cache_utilization_target < 1:\n",
|
||||
" vllm_args.append(\n",
|
||||
" f\"--host-prefix-kv-cache-utilization-target={host_prefix_kv_cache_utilization_target}\"\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" if model_type:\n",
|
||||
" vllm_args.append(f\"--model-type={model_type}\")\n",
|
||||
"\n",
|
||||
" if enable_llama_tool_parser:\n",
|
||||
" vllm_args.append(\"--enable-auto-tool-choice\")\n",
|
||||
" vllm_args.append(\"--tool-call-parser=vertex-llama-3\")\n",
|
||||
"\n",
|
||||
" env_vars = {\n",
|
||||
" \"MODEL_ID\": base_model_id,\n",
|
||||
" \"DEPLOY_SOURCE\": \"notebook\",\n",
|
||||
" }\n",
|
||||
"\n",
|
||||
" # HF_TOKEN is not a compulsory field and may not be defined.\n",
|
||||
" try:\n",
|
||||
" if HF_TOKEN:\n",
|
||||
" env_vars[\"HF_TOKEN\"] = HF_TOKEN\n",
|
||||
" except NameError:\n",
|
||||
" pass\n",
|
||||
"\n",
|
||||
" model = aiplatform.Model.upload(\n",
|
||||
" display_name=model_name,\n",
|
||||
" serving_container_image_uri=VLLM_DOCKER_URI,\n",
|
||||
" serving_container_args=vllm_args,\n",
|
||||
" serving_container_ports=[8080],\n",
|
||||
" serving_container_predict_route=\"/generate\",\n",
|
||||
" serving_container_health_route=\"/ping\",\n",
|
||||
" serving_container_environment_variables=env_vars,\n",
|
||||
" serving_container_shared_memory_size_mb=(16 * 1024), # 16 GB\n",
|
||||
" serving_container_deployment_timeout=7200,\n",
|
||||
" model_garden_source_model_name=(\n",
|
||||
" f\"publishers/{publisher}/models/{publisher_model_id}\"\n",
|
||||
" ),\n",
|
||||
" )\n",
|
||||
" print(\n",
|
||||
" f\"Deploying {model_name} on {machine_type} with {accelerator_count} {accelerator_type} GPU(s).\"\n",
|
||||
" )\n",
|
||||
" model.deploy(\n",
|
||||
" endpoint=endpoint,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" service_account=service_account,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_phi4_deployment.ipynb\",\n",
|
||||
" \"NOTEBOOK_ENVIRONMENT\": common_util.get_deploy_source(),\n",
|
||||
" },\n",
|
||||
" )\n",
|
||||
" print(\"endpoint_name:\", endpoint.name)\n",
|
||||
"\n",
|
||||
" return model, endpoint\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"# @markdown Set `use_dedicated_endpoint` to False if you don't want to use [dedicated endpoint](https://cloud.google.com/vertex-ai/docs/general/deployment#create-dedicated-endpoint).\n",
|
||||
"use_dedicated_endpoint = True # @param {type:\"boolean\"}\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"models[\"vllm_gpu\"], endpoints[\"vllm_gpu\"] = deploy_model_vllm(\n",
|
||||
" model_name=common_util.get_job_name_with_datetime(prefix=MODEL_ID),\n",
|
||||
" model_id=model_id,\n",
|
||||
" publisher=\"microsoft\",\n",
|
||||
" publisher_model_id=\"phi-4\",\n",
|
||||
" service_account=SERVICE_ACCOUNT,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" max_model_len=max_model_len,\n",
|
||||
" gpu_memory_utilization=gpu_memory_utilization,\n",
|
||||
" dtype=vllm_dtype,\n",
|
||||
" enable_trust_remote_code=enable_trust_remote_code,\n",
|
||||
"> **Note**: If the model requires accepting a license agreement (EULA), set the `accept_eula=True` flag in the deploy call. Set `use_dedicated_endpoint` to False if you don't want to use [dedicated endpoint](https://cloud.google.com/vertex-ai/docs/general/deployment#create-dedicated-endpoint)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "wX1itVTvXdEP"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "MRmPFEPoGzsB"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "PHBtn8DQp-ID"
|
||||
},
|
||||
"source": [
|
||||
"Alternatively, you can select one of the verified deployment configurations listed above."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "ADsJG8JYqI6c"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai-restricted/vertex-vision-model-garden-dockers/hex-llm-serve:stable\",\n",
|
||||
" machine_type=\"ct5lp-hightpu-4t\",\n",
|
||||
" accelerator_type=\"ACCELERATOR_TYPE_UNSPECIFIED\",\n",
|
||||
" accelerator_count=0,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "kqSUK2CwsImi"
|
||||
},
|
||||
"source": [
|
||||
"To further customize your deployment, you can configure:\n",
|
||||
"\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
"- **Compute Resources**: Machine type, replica count (min/max), accelerator type and quantity.\n",
|
||||
"- **Infrastructure**: Use Spot VMs, reservation affinity, or dedicated endpoints.\n",
|
||||
"- **Serving Container**: Customize container image, ports, health checks, and environment variables.\n",
|
||||
"\n",
|
||||
"See the [Model Garden SDK README](https://github.com/googleapis/python-aiplatform/blob/main/vertexai/model_garden/README.md) for advanced configuration options."
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -485,281 +473,7 @@
|
||||
" \"raw_response\": raw_response,\n",
|
||||
" },\n",
|
||||
"]\n",
|
||||
"response = endpoints[\"vllm_gpu\"].predict(\n",
|
||||
" instances=instances, use_dedicated_endpoint=use_dedicated_endpoint\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"for prediction in response.predictions:\n",
|
||||
" print(prediction)\n",
|
||||
"\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "OHKQj8V8d3gb"
|
||||
},
|
||||
"source": [
|
||||
"## Deploy prebuilt Phi-4 models with HexLLM"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "5kkOzZ_jd3gb"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Deploy\n",
|
||||
"\n",
|
||||
"# @markdown This section uploads prebuilt Phi-4 models to Model Registry and deploys it to a Vertex AI Endpoint. It takes 15 minutes to 1 hour to finish depending on the size of the model.\n",
|
||||
"\n",
|
||||
"# @markdown Select one of the four model variations.\n",
|
||||
"MODEL_ID = \"Phi-4\" # @param [\"Phi-4\", \"Phi-4-reasoning\", \"Phi-4-reasoning-plus\"] {isTemplate:true}\n",
|
||||
"TPU_DEPLOYMENT_REGION = \"us-west1\" # @param [\"us-west1\", \"us-central1\"] {isTemplate:true}\n",
|
||||
"model_path_prefix = \"microsoft\"\n",
|
||||
"model_id = os.path.join(model_path_prefix, MODEL_ID)\n",
|
||||
"\n",
|
||||
"# The pre-built serving docker images.\n",
|
||||
"HEXLLM_DOCKER_URI = \"us-docker.pkg.dev/vertex-ai-restricted/vertex-vision-model-garden-dockers/hex-llm-serve:phi4\"\n",
|
||||
"\n",
|
||||
"# @markdown Find Vertex AI prediction TPUv5e machine types in\n",
|
||||
"# @markdown https://cloud.google.com/vertex-ai/docs/predictions/use-tpu#deploy_a_model.\n",
|
||||
"\n",
|
||||
"# @markdown | Model Version | Default Max Model Length | Default TPU configuration |\n",
|
||||
"# @markdown |----------------------------|------------------|-----------------------------|\n",
|
||||
"# @markdown | Phi-4 | 16384 | 4 TPU_V5e ct5lp-hightpu-4t |\n",
|
||||
"# @markdown | Phi-4-reasoning | 32768 | 4 TPU_V5e ct5lp-hightpu-4t |\n",
|
||||
"# @markdown | Phi-4-reasoning-plus | 32768 | 4 TPU_V5e ct5lp-hightpu-4t |\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"# Note: 1 TPU V5 chip has only one core.\n",
|
||||
"tpu_type = \"TPU_V5e\"\n",
|
||||
"\n",
|
||||
"if \"Phi-4-reasoning\" in MODEL_ID:\n",
|
||||
" tpu_count = 4\n",
|
||||
" tpu_topo = \"1x4\"\n",
|
||||
" max_model_len = 32768\n",
|
||||
" machine_type = \"ct5lp-hightpu-4t\"\n",
|
||||
"elif \"Phi-4\" in MODEL_ID:\n",
|
||||
" tpu_count = 4\n",
|
||||
" tpu_topo = \"1x4\"\n",
|
||||
" max_model_len = 16384\n",
|
||||
" machine_type = \"ct5lp-hightpu-4t\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(f\"Unsupported MODEL_ID: {MODEL_ID}\")\n",
|
||||
"\n",
|
||||
"common_util.check_quota(\n",
|
||||
" project_id=PROJECT_ID,\n",
|
||||
" region=TPU_DEPLOYMENT_REGION,\n",
|
||||
" accelerator_type=tpu_type,\n",
|
||||
" accelerator_count=tpu_count,\n",
|
||||
" is_for_training=False,\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"# Server parameters.\n",
|
||||
"tensor_parallel_size = tpu_count\n",
|
||||
"\n",
|
||||
"# Fraction of HBM memory allocated for KV cache after model loading. A larger value improves throughput but gives higher risk of TPU out-of-memory errors with long prompts.\n",
|
||||
"hbm_utilization_factor = 0.85\n",
|
||||
"\n",
|
||||
"max_running_seqs = 256\n",
|
||||
"\n",
|
||||
"# Endpoint configurations.\n",
|
||||
"min_replica_count = 1\n",
|
||||
"max_replica_count = 1\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def deploy_model_hexllm(\n",
|
||||
" model_name: str,\n",
|
||||
" model_id: str,\n",
|
||||
" publisher: str,\n",
|
||||
" publisher_model_id: str,\n",
|
||||
" service_account: str = None,\n",
|
||||
" base_model_id: str = None,\n",
|
||||
" data_parallel_size: int = 1,\n",
|
||||
" tensor_parallel_size: int = 1,\n",
|
||||
" machine_type: str = \"ct5lp-hightpu-1t\",\n",
|
||||
" tpu_topology: str = \"1x1\",\n",
|
||||
" disagg_topology: str = None,\n",
|
||||
" hbm_utilization_factor: float = 0.6,\n",
|
||||
" max_running_seqs: int = 256,\n",
|
||||
" decode_seqs_padding: int = None,\n",
|
||||
" max_model_len: int = 4096,\n",
|
||||
" enable_prefix_cache_hbm: bool = False,\n",
|
||||
" endpoint_id: str = \"\",\n",
|
||||
" min_replica_count: int = 1,\n",
|
||||
" max_replica_count: int = 1,\n",
|
||||
" use_dedicated_endpoint: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys models with Hex-LLM on TPU in Vertex AI.\"\"\"\n",
|
||||
" if endpoint_id:\n",
|
||||
" aip_endpoint_name = (\n",
|
||||
" f\"projects/{PROJECT_ID}/locations/{REGION}/endpoints/{endpoint_id}\"\n",
|
||||
" )\n",
|
||||
" endpoint = aiplatform.Endpoint(aip_endpoint_name)\n",
|
||||
" else:\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
" display_name=f\"{model_name}-endpoint\",\n",
|
||||
" location=TPU_DEPLOYMENT_REGION,\n",
|
||||
" dedicated_endpoint_enabled=use_dedicated_endpoint,\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" if not base_model_id:\n",
|
||||
" base_model_id = model_id\n",
|
||||
"\n",
|
||||
" if not tensor_parallel_size:\n",
|
||||
" tensor_parallel_size = int(machine_type[-2])\n",
|
||||
"\n",
|
||||
" num_hosts = int(tpu_topology.split(\"x\")[0])\n",
|
||||
"\n",
|
||||
" # Learn more about the supported arguments and environment variables at https://cloud.google.com/vertex-ai/generative-ai/docs/open-models/use-hex-llm#config-server.\n",
|
||||
" hexllm_args = [\n",
|
||||
" \"--host=0.0.0.0\",\n",
|
||||
" \"--port=7080\",\n",
|
||||
" f\"--model={model_id}\",\n",
|
||||
" f\"--data_parallel_size={data_parallel_size}\",\n",
|
||||
" f\"--tensor_parallel_size={tensor_parallel_size}\",\n",
|
||||
" f\"--num_hosts={num_hosts}\",\n",
|
||||
" f\"--hbm_utilization_factor={hbm_utilization_factor}\",\n",
|
||||
" f\"--max_running_seqs={max_running_seqs}\",\n",
|
||||
" f\"--max_model_len={max_model_len}\",\n",
|
||||
" ]\n",
|
||||
"\n",
|
||||
" if decode_seqs_padding is not None:\n",
|
||||
" hexllm_args.append(f\"--decode_seqs_padding={decode_seqs_padding}\")\n",
|
||||
"\n",
|
||||
" if disagg_topology:\n",
|
||||
" hexllm_args.append(f\"--disagg_topo={disagg_topology}\")\n",
|
||||
" if enable_prefix_cache_hbm and not disagg_topology:\n",
|
||||
" hexllm_args.append(\"--enable_prefix_cache_hbm\")\n",
|
||||
"\n",
|
||||
" env_vars = {\n",
|
||||
" \"MODEL_ID\": base_model_id,\n",
|
||||
" \"HEX_LLM_LOG_LEVEL\": \"info\",\n",
|
||||
" \"DEPLOY_SOURCE\": \"notebook\",\n",
|
||||
" }\n",
|
||||
"\n",
|
||||
" # HF_TOKEN is not a compulsory field and may not be defined.\n",
|
||||
" try:\n",
|
||||
" if HF_TOKEN:\n",
|
||||
" env_vars.update({\"HF_TOKEN\": HF_TOKEN})\n",
|
||||
" except:\n",
|
||||
" pass\n",
|
||||
"\n",
|
||||
" model = aiplatform.Model.upload(\n",
|
||||
" display_name=model_name,\n",
|
||||
" serving_container_image_uri=HEXLLM_DOCKER_URI,\n",
|
||||
" serving_container_command=[\"python\", \"-m\", \"hex_llm.server.api_server\"],\n",
|
||||
" serving_container_args=hexllm_args,\n",
|
||||
" serving_container_ports=[7080],\n",
|
||||
" serving_container_predict_route=\"/generate\",\n",
|
||||
" serving_container_health_route=\"/ping\",\n",
|
||||
" serving_container_environment_variables=env_vars,\n",
|
||||
" serving_container_shared_memory_size_mb=(16 * 1024), # 16 GB\n",
|
||||
" serving_container_deployment_timeout=7200,\n",
|
||||
" location=TPU_DEPLOYMENT_REGION,\n",
|
||||
" model_garden_source_model_name=(\n",
|
||||
" f\"publishers/{publisher}/models/{publisher_model_id}\"\n",
|
||||
" ),\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" model.deploy(\n",
|
||||
" endpoint=endpoint,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" tpu_topology=tpu_topology if num_hosts > 1 else None,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" service_account=service_account,\n",
|
||||
" min_replica_count=min_replica_count,\n",
|
||||
" max_replica_count=max_replica_count,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_phi4_deployment.ipynb\",\n",
|
||||
" \"NOTEBOOK_ENVIRONMENT\": common_util.get_deploy_source(),\n",
|
||||
" },\n",
|
||||
" )\n",
|
||||
" return model, endpoint\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"# @markdown Set `use_dedicated_endpoint` to False if you don't want to use [dedicated endpoint](https://cloud.google.com/vertex-ai/docs/general/deployment#create-dedicated-endpoint).\n",
|
||||
"use_dedicated_endpoint = True # @param {type:\"boolean\"}\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"models[\"hexllm_tpu\"], endpoints[\"hexllm_tpu\"] = deploy_model_hexllm(\n",
|
||||
" model_name=common_util.get_job_name_with_datetime(prefix=MODEL_ID),\n",
|
||||
" model_id=model_id,\n",
|
||||
" publisher=\"microsoft\",\n",
|
||||
" publisher_model_id=\"phi-4\",\n",
|
||||
" service_account=SERVICE_ACCOUNT,\n",
|
||||
" tensor_parallel_size=tensor_parallel_size,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" tpu_topology=tpu_topo,\n",
|
||||
" hbm_utilization_factor=hbm_utilization_factor,\n",
|
||||
" max_running_seqs=max_running_seqs,\n",
|
||||
" max_model_len=max_model_len,\n",
|
||||
" min_replica_count=min_replica_count,\n",
|
||||
" max_replica_count=max_replica_count,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "zxsr8p5Md3gb"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Predict\n",
|
||||
"\n",
|
||||
"# @markdown Once deployment succeeds, you can send requests to the endpoint with text prompts based on your `template`. Note that the first few prompts will take longer to execute.\n",
|
||||
"\n",
|
||||
"# @markdown Additionally, you can moderate the generated text with Vertex AI. See [Moderate text documentation](https://cloud.google.com/natural-language/docs/moderating-text) for more details.\n",
|
||||
"\n",
|
||||
"# @markdown Example:\n",
|
||||
"\n",
|
||||
"# @markdown ```\n",
|
||||
"# @markdown > What is a car?\n",
|
||||
"# @markdown > A car is a four-wheeled vehicle designed for the transportation of passengers and their belongings.\n",
|
||||
"# @markdown ```\n",
|
||||
"\n",
|
||||
"# @markdown Additionally, you can moderate the generated text with Vertex AI. See [Moderate text documentation](https://cloud.google.com/natural-language/docs/moderating-text) for more details.\n",
|
||||
"\n",
|
||||
"# Loads an existing endpoint instance using the endpoint name:\n",
|
||||
"# - Using `endpoint_name = endpoint.name` allows us to get the endpoint\n",
|
||||
"# name of the endpoint `endpoint` created in the cell above.\n",
|
||||
"# - Alternatively, you can set `endpoint_name = \"1234567890123456789\"` to load\n",
|
||||
"# an existing endpoint with the ID 1234567890123456789.\n",
|
||||
"# You may uncomment the code below to load an existing endpoint:\n",
|
||||
"# endpoint_name = endpoint_without_peft.name\n",
|
||||
"# # endpoint_name = \"\" # @param {type:\"string\"}\n",
|
||||
"# aip_endpoint_name = (\n",
|
||||
"# f\"projects/{PROJECT_ID}/locations/{REGION}/endpoints/{endpoint_name}\"\n",
|
||||
"# )\n",
|
||||
"# endpoint = aiplatform.Endpoint(aip_endpoint_name)\n",
|
||||
"\n",
|
||||
"prompt = \"What is a car?\" # @param {type: \"string\"}\n",
|
||||
"# @markdown If you encounter the issue like `ServiceUnavailable: 503 Took too long to respond when processing`, you can reduce the maximum number of output tokens, such as set `max_tokens` as 20.\n",
|
||||
"max_tokens = 50 # @param {type: \"integer\"}\n",
|
||||
"temperature = 1.0 # @param {type: \"number\"}\n",
|
||||
"top_p = 1.0 # @param {type: \"number\"}\n",
|
||||
"top_k = 1 # @param {type: \"integer\"}\n",
|
||||
"\n",
|
||||
"# Overrides parameters for inferences.\n",
|
||||
"instances = [\n",
|
||||
" {\n",
|
||||
" \"prompt\": prompt,\n",
|
||||
" \"max_tokens\": max_tokens,\n",
|
||||
" \"temperature\": temperature,\n",
|
||||
" \"top_p\": top_p,\n",
|
||||
" \"top_k\": top_k,\n",
|
||||
" },\n",
|
||||
"]\n",
|
||||
"response = endpoints[\"hexllm_tpu\"].predict(\n",
|
||||
"response = endpoint.predict(\n",
|
||||
" instances=instances, use_dedicated_endpoint=use_dedicated_endpoint\n",
|
||||
")\n",
|
||||
"\n",
|
||||
@@ -788,20 +502,10 @@
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Delete the models and endpoints\n",
|
||||
"# @markdown Delete the experiment models and endpoints to recycle the resources\n",
|
||||
"# @markdown and avoid unnecessary continuous charges that may incur.\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"# Undeploy model and delete endpoint.\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)\n",
|
||||
"\n",
|
||||
"# Delete models.\n",
|
||||
"for model in models.values():\n",
|
||||
" model.delete()\n",
|
||||
"\n",
|
||||
"delete_bucket = False # @param {type:\"boolean\"}\n",
|
||||
"if delete_bucket:\n",
|
||||
" ! gsutil -m rm -r $BUCKET_NAME"
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
||||
@@ -112,7 +112,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -111,7 +111,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -165,14 +165,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -232,7 +237,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model_version = \"blip2-opt-2.7b\" # @param [\"blip2-opt-2.7b\", \"blip2-opt-2.7b-image-to-text\", \"blip2-opt-2.7b-visual-question-answering\"] {isTemplate:true}\n",
|
||||
"model_version = \"blip2-opt-2.7b-image-to-text\" # @param [\"blip2-opt-2.7b\", \"blip2-opt-2.7b-image-to-text\", \"blip2-opt-2.7b-visual-question-answering\"] {isTemplate:true}\n",
|
||||
"MODEL_NAME = f\"salesforce/blip2-opt-2.7-b@{model_version}\""
|
||||
]
|
||||
},
|
||||
@@ -329,6 +334,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -338,7 +355,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -362,16 +379,35 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-transformers-serve\",\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/pytorch-inference.cu125.0-4.ubuntu2204.py310\",\n",
|
||||
" machine_type=\"n1-standard-8\",\n",
|
||||
" accelerator_type=\"NVIDIA_TESLA_T4\",\n",
|
||||
" accelerator_count=1,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -424,9 +460,9 @@
|
||||
"import requests\n",
|
||||
"from PIL import Image\n",
|
||||
"\n",
|
||||
"if os.environ.get(\"VERTEX_PRODUCT\") != \"COLAB_ENTERPRISE\":\n",
|
||||
" ! pip install --upgrade tensorflow\n",
|
||||
"! git clone https://github.com/GoogleCloudPlatform/vertex-ai-samples.git\n",
|
||||
"# Import the necessary packages.\n",
|
||||
"! rm -rf vertex-ai-samples && git clone https://github.com/GoogleCloudPlatform/vertex-ai-samples.git\n",
|
||||
"! cd vertex-ai-samples\n",
|
||||
"\n",
|
||||
"common_util = importlib.import_module(\n",
|
||||
" \"vertex-ai-samples.notebooks.community.model_garden.docker_source_codes.notebook_util.common_util\"\n",
|
||||
@@ -444,9 +480,6 @@
|
||||
"source": [
|
||||
"# @title Image Captioning\n",
|
||||
"\n",
|
||||
"if \"visual-question-answering\" in MODEL_NAME:\n",
|
||||
" raise ValueError(\"Use VQA (Visual-Question-Answering) section instead.\")\n",
|
||||
"\n",
|
||||
"INPUT_IMAGE = \"http://images.cocodataset.org/val2017/000000039769.jpg\" # @param\n",
|
||||
"\n",
|
||||
"\n",
|
||||
@@ -481,9 +514,6 @@
|
||||
"source": [
|
||||
"# @title VQA (Visual-Question-Answering)\n",
|
||||
"\n",
|
||||
"if \"visual-question-answering\" not in MODEL_NAME:\n",
|
||||
" raise ValueError(\"Use Image Captioning section instead.\")\n",
|
||||
"\n",
|
||||
"INPUT_IMAGE = \"https://media.newyorker.com/cartoons/63dc6847be24a6a76d90eb99/master/w_1160,c_limit/230213_a26611_838.jpg\" # @param\n",
|
||||
"\n",
|
||||
"image = common_util.download_image(INPUT_IMAGE)\n",
|
||||
@@ -520,7 +550,7 @@
|
||||
"source": [
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
@@ -107,7 +107,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%pip install --upgrade --force-reinstall --quiet 'google-cloud-aiplatform>=1.106.0' 'openai' 'google-auth' 'requests'"
|
||||
"%pip install --upgrade --force-reinstall --quiet 'google-cloud-aiplatform>=1.106.0' 'openai' 'google-auth==2.27.0' 'requests==2.32.3'"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -165,14 +165,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -329,6 +334,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -338,7 +355,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -362,7 +379,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/pytorch-inference.cu125.0-4.ubuntu2204.py310:model-garden.pytorch-inference-0-4-gpu-release_20250708.04_p0\",\n",
|
||||
@@ -372,6 +389,25 @@
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -438,7 +474,7 @@
|
||||
"# @title Clean up resources\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
@@ -100,7 +100,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -107,7 +107,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -160,14 +160,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -324,6 +329,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -333,7 +350,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -357,7 +374,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-diffusers-serve-opt:20240605_1400_RC00\",\n",
|
||||
@@ -367,6 +384,25 @@
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -469,7 +505,7 @@
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
@@ -99,7 +99,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -1281,7 +1281,7 @@
|
||||
"common_util.check_quota(\n",
|
||||
" project_id=PROJECT_ID,\n",
|
||||
" region=trtllm_region,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_type=trtllm_accelerator_type,\n",
|
||||
" accelerator_count=int(accelerator_count * multihost_gpu_node_count),\n",
|
||||
" is_for_training=False,\n",
|
||||
" is_spot=is_spot,\n",
|
||||
|
||||
@@ -0,0 +1,518 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "nQ6_GB7rT9rT"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Copyright 2025 Google LLC\n",
|
||||
"#\n",
|
||||
"# Licensed under the Apache License, Version 2.0 (the \"License\");\n",
|
||||
"# you may not use this file except in compliance with the License.\n",
|
||||
"# You may obtain a copy of the License at\n",
|
||||
"#\n",
|
||||
"# https://www.apache.org/licenses/LICENSE-2.0\n",
|
||||
"#\n",
|
||||
"# Unless required by applicable law or agreed to in writing, software\n",
|
||||
"# distributed under the License is distributed on an \"AS IS\" BASIS,\n",
|
||||
"# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.\n",
|
||||
"# See the License for the specific language governing permissions and\n",
|
||||
"# limitations under the License."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "ybSTiEs6UDxY"
|
||||
},
|
||||
"source": [
|
||||
"# Vertex AI Model Garden - DeepSeek-OCR\n",
|
||||
"\n",
|
||||
"<table><tbody><tr>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/notebooks/deploy-notebook?download_url=https://raw.githubusercontent.com/GoogleCloudPlatform/vertex-ai-samples/main/notebooks/community/model_garden/model_garden_pytorch_deepseek_ocr.ipynb\">\n",
|
||||
" <img alt=\"Workbench logo\" src=\"https://lh3.googleusercontent.com/UiNooY4LUgW_oTvpsNhPpQzsstV5W8F7rYgxgGBD85cWJoLmrOzhVs_ksK_vgx40SHs7jCqkTkCk=e14-rj-sc0xffffff-h130-w32\" width=\"32px\"><br> Run in Workbench\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/colab/import/https:%2F%2Fraw.githubusercontent.com%2FGoogleCloudPlatform%2Fvertex-ai-samples%2Fmain%2Fnotebooks%2Fcommunity%2Fmodel_garden%2Fmodel_garden_pytorch_deepseek_ocr.ipynb\">\n",
|
||||
" <img alt=\"Google Cloud Colab Enterprise logo\" src=\"https://lh3.googleusercontent.com/JmcxdQi-qOpctIvWKgPtrzZdJJK-J3sWE1RsfjZNwshCFgE_9fULcNpuXYTilIR2hjwN\" width=\"32px\"><br> Run in Colab Enterprise\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://github.com/GoogleCloudPlatform/vertex-ai-samples/blob/main/notebooks/community/model_garden/model_garden_pytorch_deepseek_ocr.ipynb\">\n",
|
||||
" <img alt=\"GitHub logo\" src=\"https://github.githubassets.com/assets/GitHub-Mark-ea2971cee799.png\" width=\"32px\"><br> View on GitHub\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
"</tr></tbody></table>"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "3de7470326a2"
|
||||
},
|
||||
"source": [
|
||||
"## Overview\n",
|
||||
"\n",
|
||||
"This notebook demonstrates how to deploy a **DeepSeek-OCR** open model on Google Cloud Vertex AI.\n",
|
||||
"\n",
|
||||
"### Objectives\n",
|
||||
"\n",
|
||||
"- Deploy DeepSeek-OCR using containerized backends like [vLLM](https://github.com/vllm-project/vllm) on GPU.\n",
|
||||
"- Use the deployed model to serve chat completion requests for both text and multimodal inputs.\n",
|
||||
"\n",
|
||||
"### File a Bug\n",
|
||||
"\n",
|
||||
"If you encounter issues with this notebook, report them on [GitHub](https://github.com/GoogleCloudPlatform/vertex-ai-samples/issues/new).\n",
|
||||
"\n",
|
||||
"### Costs\n",
|
||||
"\n",
|
||||
"This tutorial uses billable components of Google Cloud:\n",
|
||||
"\n",
|
||||
"- Vertex AI\n",
|
||||
"- Cloud Storage\n",
|
||||
"\n",
|
||||
"Refer to the [Vertex AI pricing](https://cloud.google.com/vertex-ai/pricing) and [Cloud Storage pricing](https://cloud.google.com/storage/pricing) pages for more information. Use the [Pricing Calculator](https://cloud.google.com/products/calculator/) to estimate your projected costs."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "jeYw-Czg-DFy"
|
||||
},
|
||||
"source": [
|
||||
"## Get Started"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "KgyhGvEzBDkj"
|
||||
},
|
||||
"source": [
|
||||
"### Install Vertex AI SDK and other required packages"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "iCacdLqG-IsH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%pip install --upgrade --force-reinstall --quiet 'google-cloud-aiplatform>=1.106.0' 'openai' 'google-auth==2.27.0' 'requests==2.32.3'"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "HUKCrpBy-3yf"
|
||||
},
|
||||
"source": [
|
||||
"### Authenticate the Notebook Environment (Colab only)\n",
|
||||
"\n",
|
||||
"If you're running this notebook in Google Colab, run the following cell to authenticate."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "JXwCT1kn-3Gu"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import sys\n",
|
||||
"\n",
|
||||
"if \"google.colab\" in sys.modules:\n",
|
||||
" from google.colab import auth\n",
|
||||
"\n",
|
||||
" auth.authenticate_user()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "AcW2nwB8-7yC"
|
||||
},
|
||||
"source": [
|
||||
"### Set Google Cloud Project Information\n",
|
||||
"\n",
|
||||
"To get started with Vertex AI, ensure you have an existing Google Cloud project and that the [Vertex AI API is enabled](https://console.cloud.google.com/flows/enableapi?apiid=aiplatform.googleapis.com).\n",
|
||||
"\n",
|
||||
"See the guide on [setting up your project and development environment](https://cloud.google.com/vertex-ai/docs/start/cloud-environment). Also confirm that [billing is enabled](https://cloud.google.com/billing/docs/how-to/modify-project).\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "eIVLp0oE--k-"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Use the environment variable if the user doesn't provide Project ID.\n",
|
||||
"import os\n",
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Q0CXrvcZH_aw"
|
||||
},
|
||||
"source": [
|
||||
"### Import libraries"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "3G2UXB82ICs6"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from vertexai import model_garden"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "upYRiGtP_-iN"
|
||||
},
|
||||
"source": [
|
||||
"## Deploy model"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "H2WC_0hXDVXc"
|
||||
},
|
||||
"source": [
|
||||
"### Choose model variant"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "u41zbNa2EoFq"
|
||||
},
|
||||
"source": [
|
||||
"You can proceed with the default model variant or select a different one."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "-fgC4NLSDkF7"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model_version = \"deepseek-ocr\" # @param [\"deepseek-ocr\"] {isTemplate:true}\n",
|
||||
"MODEL_NAME = f\"deepseek-ai/deepseek-ocr@{model_version}\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "VRnUgU8LF3_i"
|
||||
},
|
||||
"source": [
|
||||
"To see all deployable model variants available in Model Garden, use:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "-QLd-wshF6sB"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"all_model_versions = model_garden.list_deployable_models(\n",
|
||||
" model_filter=\"deepseek-ocr\", list_hf_models=False\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "N0UeFHa2GO63"
|
||||
},
|
||||
"source": [
|
||||
"Once you've selected a model variant, initialize it:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "GZiV3trBBcA3"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model = model_garden.OpenModel(MODEL_NAME)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-0cL378wFlvf"
|
||||
},
|
||||
"source": [
|
||||
"### Check the Deployment Configuration\n",
|
||||
"\n",
|
||||
"Use the `list_deploy_options()` method to view the verified deployment configurations for your selected model. This helps ensure you have sufficient resources (e.g., GPU quota) available to deploy it."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "zm73g7vFFm9N"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"deploy_options = model.list_deploy_options(concise=True)\n",
|
||||
"print(deploy_options)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "WjV499VsGwrD"
|
||||
},
|
||||
"source": [
|
||||
"### Deploy the Model\n",
|
||||
"\n",
|
||||
"Now that you’ve reviewed the deployment options, use the `deploy()` method to serve the selected open model to a Vertex AI endpoint. Deployment time may vary depending on the model size and infrastructure requirements.\n",
|
||||
"\n",
|
||||
"> **Note**: If the model requires accepting a license agreement (EULA), set the `accept_eula=True` flag in the deploy call. Set `use_dedicated_endpoint` to False if you don't want to use [dedicated endpoint](https://cloud.google.com/vertex-ai/docs/general/deployment#create-dedicated-endpoint)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "wX1itVTvXdEP"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "MRmPFEPoGzsB"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "PHBtn8DQp-ID"
|
||||
},
|
||||
"source": [
|
||||
"Alternatively, you can select one of the verified deployment configurations listed above."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "ADsJG8JYqI6c"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20251023_0916_RC01\",\n",
|
||||
" machine_type=\"a2-ultragpu-1g\",\n",
|
||||
" accelerator_type=\"NVIDIA_A100_80GB\",\n",
|
||||
" accelerator_count=1,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "kqSUK2CwsImi"
|
||||
},
|
||||
"source": [
|
||||
"To further customize your deployment, you can configure:\n",
|
||||
"\n",
|
||||
"- **Compute Resources**: Machine type, replica count (min/max), accelerator type and quantity.\n",
|
||||
"- **Infrastructure**: Use Spot VMs, reservation affinity, or dedicated endpoints.\n",
|
||||
"- **Serving Container**: Customize container image, ports, health checks, and environment variables.\n",
|
||||
"\n",
|
||||
"See the [Model Garden SDK README](https://github.com/googleapis/python-aiplatform/blob/main/vertexai/model_garden/README.md) for advanced configuration options."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OiQQZC8clmk8"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Predict\n",
|
||||
"\n",
|
||||
"# @markdown Once deployment succeeds, you can send requests to the endpoint with text prompts. Sampling parameters supported by vLLM can be found [here](https://docs.vllm.ai/en/latest/dev/sampling_params.html).\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"user_image = \"https://upload.wikimedia.org/wikipedia/commons/4/42/Degrees_of_crystallization_of_scientific_communications_-_fncom-06-00079-g009.jpeg\" # @param {type: \"string\"}\n",
|
||||
"max_tokens = 128 # @param {type: \"integer\"}\n",
|
||||
"temperature = 0.0 # @param {type: \"number\"}\n",
|
||||
"skip_special_tokens = False # @param {type: \"boolean\"}\n",
|
||||
"stream = False # @param {type: \"boolean\"}\n",
|
||||
"\n",
|
||||
"instances = [\n",
|
||||
" {\n",
|
||||
" \"@requestFormat\": \"chatCompletions\",\n",
|
||||
" \"messages\": [\n",
|
||||
" {\n",
|
||||
" \"role\": \"user\",\n",
|
||||
" \"content\": [\n",
|
||||
" {\"type\": \"text\", \"text\": \"Free OCR\"},\n",
|
||||
" {\n",
|
||||
" \"type\": \"image_url\",\n",
|
||||
" \"image_url\": {\n",
|
||||
" \"url\": user_image,\n",
|
||||
" },\n",
|
||||
" },\n",
|
||||
" ],\n",
|
||||
" },\n",
|
||||
" ],\n",
|
||||
" \"stream\": stream,\n",
|
||||
" \"temperature\": temperature,\n",
|
||||
" \"max_tokens\": max_tokens,\n",
|
||||
" \"extra_args\": {\n",
|
||||
" \"ngram_size\": 30,\n",
|
||||
" \"window_size\": 90,\n",
|
||||
" \"whitelist_token_ids\": [128821, 128822],\n",
|
||||
" },\n",
|
||||
" \"skip_special_tokens\": skip_special_tokens,\n",
|
||||
" },\n",
|
||||
"]\n",
|
||||
"\n",
|
||||
"response = endpoint.predict(instances=instances)\n",
|
||||
"print(response.predictions)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Z6Umyddcliad"
|
||||
},
|
||||
"source": [
|
||||
"## Clean up resources"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "K2IZVGu2lYvJ"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Delete the endpoints\n",
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "model_garden_pytorch_deepseek_ocr.ipynb",
|
||||
"toc_visible": true
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
@@ -0,0 +1,594 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "YXhbYF11R6oJ"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Copyright 2025 Google LLC\n",
|
||||
"#\n",
|
||||
"# Licensed under the Apache License, Version 2.0 (the \"License\");\n",
|
||||
"# you may not use this file except in compliance with the License.\n",
|
||||
"# You may obtain a copy of the License at\n",
|
||||
"#\n",
|
||||
"# https://www.apache.org/licenses/LICENSE-2.0\n",
|
||||
"#\n",
|
||||
"# Unless required by applicable law or agreed to in writing, software\n",
|
||||
"# distributed under the License is distributed on an \"AS IS\" BASIS,\n",
|
||||
"# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.\n",
|
||||
"# See the License for the specific language governing permissions and\n",
|
||||
"# limitations under the License."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "vbPdpEwmShMY"
|
||||
},
|
||||
"source": [
|
||||
" # Vertex AI Model Garden - DeepSeek-V3.2\n",
|
||||
"\n",
|
||||
"<table><tbody><tr>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/notebooks/deploy-notebook?download_url=https://raw.githubusercontent.com/GoogleCloudPlatform/vertex-ai-samples/main/notebooks/community/model_garden/model_garden_pytorch_deepseek_v3_2_deployment.ipynb\">\n",
|
||||
" <img alt=\"Workbench logo\" src=\"https://lh3.googleusercontent.com/UiNooY4LUgW_oTvpsNhPpQzsstV5W8F7rYgxgGBD85cWJoLmrOzhVs_ksK_vgx40SHs7jCqkTkCk=e14-rj-sc0xffffff-h130-w32\" width=\"32px\"><br> Run in Workbench\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/colab/import/https:%2F%2Fraw.githubusercontent.com%2FGoogleCloudPlatform%2Fvertex-ai-samples%2Fmain%2Fnotebooks%2Fcommunity%2Fmodel_garden%2Fmodel_garden_pytorch_deepseek_v3_2_deployment.ipynb\">\n",
|
||||
" <img alt=\"Google Cloud Colab Enterprise logo\" src=\"https://lh3.googleusercontent.com/JmcxdQi-qOpctIvWKgPtrzZdJJK-J3sWE1RsfjZNwshCFgE_9fULcNpuXYTilIR2hjwN\" width=\"32px\"><br> Run in Colab Enterprise\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://github.com/GoogleCloudPlatform/vertex-ai-samples/blob/main/notebooks/community/model_garden/model_garden_pytorch_deepseek_v3_2_deployment.ipynb\">\n",
|
||||
" <img alt=\"GitHub logo\" src=\"https://github.githubassets.com/assets/GitHub-Mark-ea2971cee799.png\" width=\"32px\"><br> View on GitHub\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
"</tr></tbody></table>"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "3de7470326a2"
|
||||
},
|
||||
"source": [
|
||||
"## Overview\n",
|
||||
"\n",
|
||||
"This notebook demonstrates how to deploy a **DeepSeek-V3.2** open model on Google Cloud Vertex AI.\n",
|
||||
"\n",
|
||||
"### Objectives\n",
|
||||
"\n",
|
||||
"- Deploy DeepSeek-V3.2 using containerized backends like [vLLM](https://github.com/vllm-project/vllm) on GPU.\n",
|
||||
"- Use the deployed model to serve chat completion requests for both text and multimodal inputs.\n",
|
||||
"\n",
|
||||
"### File a Bug\n",
|
||||
"\n",
|
||||
"If you encounter issues with this notebook, report them on [GitHub](https://github.com/GoogleCloudPlatform/vertex-ai-samples/issues/new).\n",
|
||||
"\n",
|
||||
"### Costs\n",
|
||||
"\n",
|
||||
"This tutorial uses billable components of Google Cloud:\n",
|
||||
"\n",
|
||||
"- Vertex AI\n",
|
||||
"- Cloud Storage\n",
|
||||
"\n",
|
||||
"Refer to the [Vertex AI pricing](https://cloud.google.com/vertex-ai/pricing) and [Cloud Storage pricing](https://cloud.google.com/storage/pricing) pages for more information. Use the [Pricing Calculator](https://cloud.google.com/products/calculator/) to estimate your projected costs."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "jeYw-Czg-DFy"
|
||||
},
|
||||
"source": [
|
||||
"## Get Started"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "KgyhGvEzBDkj"
|
||||
},
|
||||
"source": [
|
||||
"### Install Vertex AI SDK and other required packages"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "iCacdLqG-IsH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%pip install --upgrade --force-reinstall --quiet 'google-cloud-aiplatform>=1.106.0' 'openai' 'google-auth==2.27.0' 'requests==2.32.3'"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "HUKCrpBy-3yf"
|
||||
},
|
||||
"source": [
|
||||
"### Authenticate the Notebook Environment (Colab only)\n",
|
||||
"\n",
|
||||
"If you're running this notebook in Google Colab, run the following cell to authenticate."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "JXwCT1kn-3Gu"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import sys\n",
|
||||
"\n",
|
||||
"if \"google.colab\" in sys.modules:\n",
|
||||
" from google.colab import auth\n",
|
||||
"\n",
|
||||
" auth.authenticate_user()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "AcW2nwB8-7yC"
|
||||
},
|
||||
"source": [
|
||||
"### Set Google Cloud Project Information\n",
|
||||
"\n",
|
||||
"To get started with Vertex AI, ensure you have an existing Google Cloud project and that the [Vertex AI API is enabled](https://console.cloud.google.com/flows/enableapi?apiid=aiplatform.googleapis.com).\n",
|
||||
"\n",
|
||||
"See the guide on [setting up your project and development environment](https://cloud.google.com/vertex-ai/docs/start/cloud-environment). Also confirm that [billing is enabled](https://cloud.google.com/billing/docs/how-to/modify-project).\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "eIVLp0oE--k-"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Use the environment variable if the user doesn't provide Project ID.\n",
|
||||
"import os\n",
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Q0CXrvcZH_aw"
|
||||
},
|
||||
"source": [
|
||||
"### Import libraries"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "3G2UXB82ICs6"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from vertexai import model_garden"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "upYRiGtP_-iN"
|
||||
},
|
||||
"source": [
|
||||
"## Deploy model"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "H2WC_0hXDVXc"
|
||||
},
|
||||
"source": [
|
||||
"### Choose model variant"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "u41zbNa2EoFq"
|
||||
},
|
||||
"source": [
|
||||
"You can proceed with the default model variant or select a different one."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "-fgC4NLSDkF7"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model_version = \"deepseek-v3-2-exp-base\" # @param [\"deepseek-v3-2-exp\", \"deepseek-v3-2-exp-base\"] {isTemplate:true}\n",
|
||||
"MODEL_NAME = f\"deepseek-ai/deepseek-v3-2@{model_version}\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "VRnUgU8LF3_i"
|
||||
},
|
||||
"source": [
|
||||
"To see all deployable model variants available in Model Garden, use:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "-QLd-wshF6sB"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"all_model_versions = model_garden.list_deployable_models(\n",
|
||||
" model_filter=\"deepseek-v3-2\", list_hf_models=False\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "N0UeFHa2GO63"
|
||||
},
|
||||
"source": [
|
||||
"Once you've selected a model variant, initialize it:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "GZiV3trBBcA3"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model = model_garden.OpenModel(MODEL_NAME)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-0cL378wFlvf"
|
||||
},
|
||||
"source": [
|
||||
"### Check the Deployment Configuration\n",
|
||||
"\n",
|
||||
"Use the `list_deploy_options()` method to view the verified deployment configurations for your selected model. This helps ensure you have sufficient resources (e.g., GPU quota) available to deploy it."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "zm73g7vFFm9N"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"deploy_options = model.list_deploy_options(concise=True)\n",
|
||||
"print(deploy_options)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "WjV499VsGwrD"
|
||||
},
|
||||
"source": [
|
||||
"### Deploy the Model\n",
|
||||
"\n",
|
||||
"Now that you’ve reviewed the deployment options, use the `deploy()` method to serve the selected open model to a Vertex AI endpoint. Deployment time may vary depending on the model size and infrastructure requirements.\n",
|
||||
"\n",
|
||||
"> **Note**: If the model requires accepting a license agreement (EULA), set the `accept_eula=True` flag in the deploy call. Set `use_dedicated_endpoint` to False if you don't want to use [dedicated endpoint](https://cloud.google.com/vertex-ai/docs/general/deployment#create-dedicated-endpoint)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "wX1itVTvXdEP"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "MRmPFEPoGzsB"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "PHBtn8DQp-ID"
|
||||
},
|
||||
"source": [
|
||||
"Alternatively, you can select one of the verified deployment configurations listed above."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "ADsJG8JYqI6c"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20250930_0916_RC01\",\n",
|
||||
" machine_type=\"a4-highgpu-8g\",\n",
|
||||
" accelerator_type=\"NVIDIA_B200\",\n",
|
||||
" accelerator_count=8,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "kqSUK2CwsImi"
|
||||
},
|
||||
"source": [
|
||||
"To further customize your deployment, you can configure:\n",
|
||||
"\n",
|
||||
"- **Compute Resources**: Machine type, replica count (min/max), accelerator type and quantity.\n",
|
||||
"- **Infrastructure**: Use Spot VMs, reservation affinity, or dedicated endpoints.\n",
|
||||
"- **Serving Container**: Customize container image, ports, health checks, and environment variables.\n",
|
||||
"\n",
|
||||
"See the [Model Garden SDK README](https://github.com/googleapis/python-aiplatform/blob/main/vertexai/model_garden/README.md) for advanced configuration options."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "5ptrDoPkSghh"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Raw predict\n",
|
||||
"\n",
|
||||
"# @markdown Once deployment succeeds, you can send requests to the endpoint with text prompts. Sampling parameters supported by vLLM can be found [here](https://docs.vllm.ai/en/latest/dev/sampling_params.html).\n",
|
||||
"\n",
|
||||
"# @markdown Example:\n",
|
||||
"\n",
|
||||
"# @markdown ```\n",
|
||||
"# @markdown Human: What is a car?\n",
|
||||
"# @markdown Assistant: A car, or a motor car, is a road-connected human-transportation system used to move people or goods from one place to another. The term also encompasses a wide range of vehicles, including motorboats, trains, and aircrafts. Cars typically have four wheels, a cabin for passengers, and an engine or motor. They have been around since the early 19th century and are now one of the most popular forms of transportation, used for daily commuting, shopping, and other purposes.\n",
|
||||
"# @markdown ```\n",
|
||||
"# @markdown Additionally, you can moderate the generated text with Vertex AI. See [Moderate text documentation](https://cloud.google.com/natural-language/docs/moderating-text) for more details.\n",
|
||||
"\n",
|
||||
"# Loads an existing endpoint instance using the endpoint name:\n",
|
||||
"# - Using `endpoint_name = endpoint.name` allows us to get the\n",
|
||||
"# endpoint name of the endpoint `endpoint` created in the cell\n",
|
||||
"# above.\n",
|
||||
"# - Alternatively, you can set `endpoint_name = \"1234567890123456789\"` to load\n",
|
||||
"# an existing endpoint with the ID 1234567890123456789.\n",
|
||||
"# You may uncomment the code below to load an existing endpoint.\n",
|
||||
"\n",
|
||||
"# endpoint_name = \"\" # @param {type:\"string\"}\n",
|
||||
"# aip_endpoint_name = (\n",
|
||||
"# f\"projects/{PROJECT_ID}/locations/{REGION}/endpoints/{endpoint_name}\"\n",
|
||||
"# )\n",
|
||||
"# endpoint = aiplatform.Endpoint(aip_endpoint_name)\n",
|
||||
"\n",
|
||||
"prompt = \"What is a car?\" # @param {type: \"string\"}\n",
|
||||
"# @markdown If you encounter an issue like `ServiceUnavailable: 503 Took too long to respond when processing`, you can reduce the maximum number of output tokens, by lowering `max_tokens`.\n",
|
||||
"max_tokens = 50 # @param {type:\"integer\"}\n",
|
||||
"temperature = 1.0 # @param {type:\"number\"}\n",
|
||||
"top_p = 1.0 # @param {type:\"number\"}\n",
|
||||
"top_k = 1 # @param {type:\"integer\"}\n",
|
||||
"# @markdown Set `raw_response` to `True` to obtain the raw model output. Set `raw_response` to `False` to apply additional formatting in the structure of `\"Prompt:\\n{prompt.strip()}\\nOutput:\\n{output}\"`.\n",
|
||||
"raw_response = False # @param {type:\"boolean\"}\n",
|
||||
"\n",
|
||||
"# Overrides parameters for inferences.\n",
|
||||
"instances = [\n",
|
||||
" {\n",
|
||||
" \"prompt\": prompt,\n",
|
||||
" \"max_tokens\": max_tokens,\n",
|
||||
" \"temperature\": temperature,\n",
|
||||
" \"top_p\": top_p,\n",
|
||||
" \"top_k\": top_k,\n",
|
||||
" \"raw_response\": raw_response,\n",
|
||||
" },\n",
|
||||
"]\n",
|
||||
"response = endpoint.predict(\n",
|
||||
" instances=instances, use_dedicated_endpoint=use_dedicated_endpoint\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"for prediction in response.predictions:\n",
|
||||
" print(prediction)\n",
|
||||
"\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "AMjpQGSfYORn"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Chat completion\n",
|
||||
"\n",
|
||||
"if use_dedicated_endpoint:\n",
|
||||
" DEDICATED_ENDPOINT_DNS = endpoint.gca_resource.dedicated_endpoint_dns\n",
|
||||
"ENDPOINT_RESOURCE_NAME = endpoint.resource_name\n",
|
||||
"\n",
|
||||
"# @title Chat Completions Inference\n",
|
||||
"\n",
|
||||
"# @markdown Once deployment succeeds, you can send requests to the endpoint using the OpenAI SDK.\n",
|
||||
"\n",
|
||||
"# @markdown First you will need to install the SDK and some auth-related dependencies.\n",
|
||||
"\n",
|
||||
"! pip install -qU openai google-auth requests\n",
|
||||
"\n",
|
||||
"# @markdown Next fill out some request parameters:\n",
|
||||
"\n",
|
||||
"user_message = \"How is your day going?\" # @param {type: \"string\"}\n",
|
||||
"# @markdown If you encounter the issue like `ServiceUnavailable: 503 Took too long to respond when processing`, you can reduce the maximum number of output tokens, such as set `max_tokens` as 20.\n",
|
||||
"max_tokens = 50 # @param {type: \"integer\"}\n",
|
||||
"temperature = 1.0 # @param {type: \"number\"}\n",
|
||||
"stream = False # @param {type: \"boolean\"}\n",
|
||||
"\n",
|
||||
"# @markdown Now we can send a request.\n",
|
||||
"\n",
|
||||
"import google.auth\n",
|
||||
"import openai\n",
|
||||
"\n",
|
||||
"creds, project = google.auth.default()\n",
|
||||
"auth_req = google.auth.transport.requests.Request()\n",
|
||||
"creds.refresh(auth_req)\n",
|
||||
"\n",
|
||||
"BASE_URL = (\n",
|
||||
" f\"https://{REGION}-aiplatform.googleapis.com/v1beta1/{ENDPOINT_RESOURCE_NAME}\"\n",
|
||||
")\n",
|
||||
"try:\n",
|
||||
" if use_dedicated_endpoint:\n",
|
||||
" BASE_URL = f\"https://{DEDICATED_ENDPOINT_DNS}/v1beta1/{ENDPOINT_RESOURCE_NAME}\"\n",
|
||||
"except NameError:\n",
|
||||
" pass\n",
|
||||
"\n",
|
||||
"client = openai.OpenAI(base_url=BASE_URL, api_key=creds.token)\n",
|
||||
"\n",
|
||||
"model_response = client.chat.completions.create(\n",
|
||||
" model=\"\",\n",
|
||||
" messages=[{\"role\": \"user\", \"content\": user_message}],\n",
|
||||
" temperature=temperature,\n",
|
||||
" max_tokens=max_tokens,\n",
|
||||
" stream=stream,\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"if stream:\n",
|
||||
" usage = None\n",
|
||||
" contents = []\n",
|
||||
" for chunk in model_response:\n",
|
||||
" if chunk.usage is not None:\n",
|
||||
" usage = chunk.usage\n",
|
||||
" continue\n",
|
||||
" print(chunk.choices[0].delta.content, end=\"\")\n",
|
||||
" contents.append(chunk.choices[0].delta.content)\n",
|
||||
" print(f\"\\n\\n{usage}\")\n",
|
||||
"else:\n",
|
||||
" print(model_response)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "XQ_xFlmPYU_V"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Delete the endpoints\n",
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "model_garden_pytorch_deepseek_v3_2_deployment.ipynb",
|
||||
"toc_visible": true
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
@@ -109,7 +109,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
+1
-1
@@ -113,7 +113,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -109,7 +109,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -99,7 +99,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
+3
-1
@@ -97,7 +97,7 @@
|
||||
"# @title Install Python Packages for Finetuning\n",
|
||||
"\n",
|
||||
"# @markdown 1. Install google-cloud-aiplatform package and restart the session if instructed.\n",
|
||||
"! pip install --upgrade --quiet 'google-cloud-aiplatform>=1.66.0'\n",
|
||||
"! pip install --upgrade --quiet google-cloud-aiplatform==1.130.0\n",
|
||||
"\n",
|
||||
"# @markdown 2. Install packages to validate dataset with template.\n",
|
||||
"! pip install --upgrade --quiet accelerate==0.31.0\n",
|
||||
@@ -708,6 +708,7 @@
|
||||
" max_num_seqs: int = 256,\n",
|
||||
" model_type: str = None,\n",
|
||||
" enable_llama_tool_parser: bool = False,\n",
|
||||
" is_spot: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys trained models with vLLM into Vertex AI.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
@@ -802,6 +803,7 @@
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" service_account=service_account,\n",
|
||||
" spot=is_spot,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_pytorch_gemma_peft_finetuning_hf.ipynb\",\n",
|
||||
" \"NOTEBOOK_ENVIRONMENT\": get_deploy_source(),\n",
|
||||
|
||||
@@ -165,14 +165,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -329,6 +334,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -338,7 +355,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -362,16 +379,35 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20250807_0916_RC01_maas\",\n",
|
||||
" machine_type=\"a3-highgpu-2g\",\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/sglang-serve.cu124.0-4.ubuntu2204.py310:model-garden.sglang-0-4-release_20250831.00_p0\",\n",
|
||||
" machine_type=\"a3-highgpu-8g\",\n",
|
||||
" accelerator_type=\"NVIDIA_H100_80GB\",\n",
|
||||
" accelerator_count=2,\n",
|
||||
" accelerator_count=8,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -549,7 +585,7 @@
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
@@ -0,0 +1,647 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "SgQ6t5bqZVlH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Copyright 2025 Google LLC\n",
|
||||
"#\n",
|
||||
"# Licensed under the Apache License, Version 2.0 (the \"License\");\n",
|
||||
"# you may not use this file except in compliance with the License.\n",
|
||||
"# You may obtain a copy of the License at\n",
|
||||
"#\n",
|
||||
"# https://www.apache.org/licenses/LICENSE-2.0\n",
|
||||
"#\n",
|
||||
"# Unless required by applicable law or agreed to in writing, software\n",
|
||||
"# distributed under the License is distributed on an \"AS IS\" BASIS,\n",
|
||||
"# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.\n",
|
||||
"# See the License for the specific language governing permissions and\n",
|
||||
"# limitations under the License."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "99c1c3fc2ca5"
|
||||
},
|
||||
"source": [
|
||||
"# Vertex AI Model Garden - GPT OSS (Deployment on G4)\n",
|
||||
"\n",
|
||||
"<table><tbody><tr>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/notebooks/deploy-notebook?download_url=https://raw.githubusercontent.com/GoogleCloudPlatform/vertex-ai-samples/main/notebooks/community/model_garden/model_garden_pytorch_gpt_oss_g4_deployment.ipynb\">\n",
|
||||
" <img alt=\"Workbench logo\" src=\"https://lh3.googleusercontent.com/UiNooY4LUgW_oTvpsNhPpQzsstV5W8F7rYgxgGBD85cWJoLmrOzhVs_ksK_vgx40SHs7jCqkTkCk=e14-rj-sc0xffffff-h130-w32\" width=\"32px\"><br> Run in Workbench\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/colab/import/https:%2F%2Fraw.githubusercontent.com%2FGoogleCloudPlatform%2Fvertex-ai-samples%2Fmain%2Fnotebooks%2Fcommunity%2Fmodel_garden%2Fmodel_garden_pytorch_gpt_oss_g4_deployment.ipynb\">\n",
|
||||
" <img alt=\"Google Cloud Colab Enterprise logo\" src=\"https://lh3.googleusercontent.com/JmcxdQi-qOpctIvWKgPtrzZdJJK-J3sWE1RsfjZNwshCFgE_9fULcNpuXYTilIR2hjwN\" width=\"32px\"><br> Run in Colab Enterprise\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://github.com/GoogleCloudPlatform/vertex-ai-samples/blob/main/notebooks/community/model_garden/model_garden_pytorch_gpt_oss_g4_deployment.ipynb\">\n",
|
||||
" <img alt=\"GitHub logo\" src=\"https://github.githubassets.com/assets/GitHub-Mark-ea2971cee799.png\" width=\"32px\"><br> View on GitHub\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
"</tr></tbody></table>"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "3de7470326a2"
|
||||
},
|
||||
"source": [
|
||||
"## Overview\n",
|
||||
"\n",
|
||||
"This notebook demonstrates serving [GPT OSS](https://huggingface.co/collections/openai/gpt-oss-68911959590a1634ba11c7a4) models with [vLLM](https://github.com/vllm-project/vllm) on G4 machines with NVIDIA RTX Pro 6000 GPUs.\n",
|
||||
"\n",
|
||||
"### Objective\n",
|
||||
"\n",
|
||||
"- Deploy GPT OSS variants on G4 machines with vLLM.\n",
|
||||
"\n",
|
||||
"### File a bug\n",
|
||||
"\n",
|
||||
"File a bug on [GitHub](https://github.com/GoogleCloudPlatform/vertex-ai-samples/issues/new) if you encounter any issue with the notebook.\n",
|
||||
"\n",
|
||||
"### Costs\n",
|
||||
"\n",
|
||||
"This tutorial uses billable components of Google Cloud:\n",
|
||||
"\n",
|
||||
"* Vertex AI\n",
|
||||
"* Cloud Storage\n",
|
||||
"\n",
|
||||
"Learn about [Vertex AI pricing](https://cloud.google.com/vertex-ai/pricing), [Cloud Storage pricing](https://cloud.google.com/storage/pricing), and use the [Pricing Calculator](https://cloud.google.com/products/calculator/) to generate a cost estimate based on your projected usage."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "264c07757582"
|
||||
},
|
||||
"source": [
|
||||
"## Before you begin"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 1,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "ax7zWynUDcjk"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Request for quota\n",
|
||||
"\n",
|
||||
"# @markdown To deploy with G4 machines, check that you have sufficient quota: [CustomModelServingRTXPRO6000GPUsPerProjectPerRegion](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_rtx_pro_6000_gpus). Find the available region(s) [here](https://cloud.google.com/vertex-ai/docs/general/locations#region_considerations).\n",
|
||||
"\n",
|
||||
"# @markdown If you don't have sufficient quota, request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown You can also use Compute Engine reservations with Vertex Prediction following the instructions [here](https://cloud.google.com/vertex-ai/docs/predictions/use-reservations). Note that the GCE quota for the shared reservation will be managed separately. Shared reservation is the only GCE consumption mode."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "YXFGIp1l-qtT"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Setup Google Cloud project\n",
|
||||
"\n",
|
||||
"# @markdown 1. [Make sure that billing is enabled for your project](https://cloud.google.com/billing/docs/how-to/modify-project).\n",
|
||||
"\n",
|
||||
"# @markdown 2. **[Optional]** Set region. If not set, the region will be set automatically according to Colab Enterprise environment.\n",
|
||||
"\n",
|
||||
"REGION = \"\" # @param {type:\"string\"}\n",
|
||||
"\n",
|
||||
"# Upgrade Vertex AI SDK.\n",
|
||||
"! pip3 install --upgrade --quiet 'google-cloud-aiplatform==1.103.0'\n",
|
||||
"\n",
|
||||
"# Import the necessary packages\n",
|
||||
"import importlib\n",
|
||||
"import os\n",
|
||||
"from typing import Tuple\n",
|
||||
"\n",
|
||||
"import requests\n",
|
||||
"from google import auth\n",
|
||||
"from google.cloud import aiplatform\n",
|
||||
"\n",
|
||||
"# Upgrade Vertex AI SDK.\n",
|
||||
"if os.environ.get(\"VERTEX_PRODUCT\") != \"COLAB_ENTERPRISE\":\n",
|
||||
" ! pip install --upgrade tensorflow\n",
|
||||
"! git clone https://github.com/GoogleCloudPlatform/vertex-ai-samples.git\n",
|
||||
"\n",
|
||||
"common_util = importlib.import_module(\n",
|
||||
" \"vertex-ai-samples.notebooks.community.model_garden.docker_source_codes.notebook_util.common_util\"\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"LABEL = \"vllm_gpu\"\n",
|
||||
"models, endpoints = {}, {}\n",
|
||||
"\n",
|
||||
"# Get the default cloud project id.\n",
|
||||
"PROJECT_ID = os.environ[\"GOOGLE_CLOUD_PROJECT\"]\n",
|
||||
"\n",
|
||||
"# Get the default region for launching jobs.\n",
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ[\"GOOGLE_CLOUD_REGION\"]\n",
|
||||
"\n",
|
||||
"# Initialize Vertex AI API.\n",
|
||||
"print(\"Initializing Vertex AI API.\")\n",
|
||||
"aiplatform.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"! gcloud config set project $PROJECT_ID\n",
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"vertexai.init(\n",
|
||||
" project=PROJECT_ID,\n",
|
||||
" location=REGION,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "z-XybZjtgF9M"
|
||||
},
|
||||
"source": [
|
||||
"## Deploy GPT OSS models with vLLM"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "E8OiHHNNE_wj"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Set the model variants\n",
|
||||
"\n",
|
||||
"# @markdown Set the model to deploy.\n",
|
||||
"\n",
|
||||
"base_model_name = \"gpt-oss-20b\" # @param [\"gpt-oss-20b\"] {isTemplate:true}\n",
|
||||
"hf_model_id = \"openai/\" + base_model_name\n",
|
||||
"model_user_id = \"gpt-oss\"\n",
|
||||
"model_id = f\"gs://vertex-model-garden-restricted-us/{hf_model_id}\"\n",
|
||||
"\n",
|
||||
"PUBLISHER_MODEL_NAME = (\n",
|
||||
" f\"publishers/openai/models/{model_user_id}@{base_model_name.lower()}\"\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"# @markdown Set use_dedicated_endpoint to False if you don't want to use [dedicated endpoint](https://cloud.google.com/vertex-ai/docs/general/deployment#create-dedicated-endpoint). Note that [dedicated endpoint does not support VPC Service Controls](https://cloud.google.com/vertex-ai/docs/predictions/choose-endpoint-type), uncheck the box if you are using VPC-SC.\n",
|
||||
"use_dedicated_endpoint = True # @param {type:\"boolean\"}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "acd75fc92341"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Deploy with customized configs\n",
|
||||
"\n",
|
||||
"# @markdown This section uploads GPT OSS models to Model Registry and deploys them to a Vertex Prediction Endpoint. It takes ~1 hour to finish.\n",
|
||||
"\n",
|
||||
"# @markdown The pre-built serving docker image.\n",
|
||||
"VLLM_DOCKER_URI = \"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20250905_0916_RC01\"\n",
|
||||
"\n",
|
||||
"# @markdown Find Vertex AI prediction supported accelerators and regions at https://cloud.google.com/vertex-ai/docs/predictions/configure-compute.\n",
|
||||
"accelerator_type = \"NVIDIA_RTX_PRO_6000\" # @param [\"NVIDIA_RTX_PRO_6000\"] {isTemplate:true}\n",
|
||||
"if accelerator_type == \"NVIDIA_RTX_PRO_6000\":\n",
|
||||
" accelerator_count = 1\n",
|
||||
" machine_type = \"g4-standard-48\"\n",
|
||||
" resource_id = \"custom_model_serving_nvidia_rtx_pro_6000_gpus\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"Sample deployment options are not available.\")\n",
|
||||
"\n",
|
||||
"common_util.check_quota(\n",
|
||||
" project_id=PROJECT_ID,\n",
|
||||
" region=REGION,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" is_for_training=False,\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"max_model_len = 131072\n",
|
||||
"gpu_memory_utilization = 0.9\n",
|
||||
"\n",
|
||||
"# @markdown To enable the auto-scaling in deployment, you can set the following options:\n",
|
||||
"\n",
|
||||
"min_replica_count = 1 # @param {type:\"integer\"}\n",
|
||||
"max_replica_count = 1 # @param {type:\"integer\"}\n",
|
||||
"required_replica_count = 1 # @param {type:\"integer\"}\n",
|
||||
"\n",
|
||||
"# @markdown Set the target of GPU duty cycle or CPU usage between 1 and 100 for auto-scaling.\n",
|
||||
"autoscale_by_gpu_duty_cycle_target = 0 # @param {type:\"integer\"}\n",
|
||||
"autoscale_by_cpu_usage_target = 0 # @param {type:\"integer\"}\n",
|
||||
"\n",
|
||||
"# @markdown Note: GPU duty cycle is not the most accurate metric for scaling workloads. More advanced auto-scaling metrics are coming soon. See [the public doc](https://cloud.google.com/vertex-ai/docs/reference/rest/v1/DedicatedResources#AutoscalingMetricSpec) for more details.\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def deploy_model_vllm(\n",
|
||||
" model_name: str,\n",
|
||||
" model_id: str,\n",
|
||||
" publisher: str,\n",
|
||||
" publisher_model_id: str,\n",
|
||||
" base_model_id: str = None,\n",
|
||||
" machine_type: str = \"g2-standard-8\",\n",
|
||||
" accelerator_type: str = \"NVIDIA_L4\",\n",
|
||||
" accelerator_count: int = 1,\n",
|
||||
" gpu_memory_utilization: float = 0.9,\n",
|
||||
" max_model_len: int = 4096,\n",
|
||||
" dtype: str = \"auto\",\n",
|
||||
" enable_trust_remote_code: bool = False,\n",
|
||||
" enforce_eager: bool = False,\n",
|
||||
" enable_lora: bool = False,\n",
|
||||
" enable_chunked_prefill: bool = False,\n",
|
||||
" enable_prefix_cache: bool = False,\n",
|
||||
" host_prefix_kv_cache_utilization_target: float = 0.0,\n",
|
||||
" max_loras: int = 1,\n",
|
||||
" max_cpu_loras: int = 8,\n",
|
||||
" use_dedicated_endpoint: bool = False,\n",
|
||||
" max_num_seqs: int = 256,\n",
|
||||
" model_type: str = None,\n",
|
||||
" enable_llama_tool_parser: bool = False,\n",
|
||||
" min_replica_count: int = 1,\n",
|
||||
" max_replica_count: int = 1,\n",
|
||||
" required_replica_count: int = 1,\n",
|
||||
" autoscale_by_gpu_duty_cycle_target: int = 0,\n",
|
||||
" autoscale_by_cpu_usage_target: int = 0,\n",
|
||||
" is_spot: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys trained models with vLLM into Vertex AI.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
" display_name=f\"{model_name}-endpoint\",\n",
|
||||
" dedicated_endpoint_enabled=use_dedicated_endpoint,\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" if not base_model_id:\n",
|
||||
" base_model_id = model_id\n",
|
||||
"\n",
|
||||
" # See https://docs.vllm.ai/en/latest/models/engine_args.html for a list of possible arguments with descriptions.\n",
|
||||
" vllm_args = [\n",
|
||||
" \"python\",\n",
|
||||
" \"-m\",\n",
|
||||
" \"vllm.entrypoints.api_server\",\n",
|
||||
" \"--host=0.0.0.0\",\n",
|
||||
" \"--port=8080\",\n",
|
||||
" f\"--model={model_id}\",\n",
|
||||
" f\"--tensor-parallel-size={accelerator_count}\",\n",
|
||||
" \"--swap-space=16\",\n",
|
||||
" f\"--max-model-len={max_model_len}\",\n",
|
||||
" f\"--dtype={dtype}\",\n",
|
||||
" f\"--max-loras={max_loras}\",\n",
|
||||
" f\"--max-cpu-loras={max_cpu_loras}\",\n",
|
||||
" f\"--max-num-seqs={max_num_seqs}\",\n",
|
||||
" \"--disable-log-stats\",\n",
|
||||
" ]\n",
|
||||
"\n",
|
||||
" if gpu_memory_utilization:\n",
|
||||
" vllm_args.append(f\"--gpu-memory-utilization={gpu_memory_utilization}\")\n",
|
||||
"\n",
|
||||
" if enable_trust_remote_code:\n",
|
||||
" vllm_args.append(\"--trust-remote-code\")\n",
|
||||
"\n",
|
||||
" if enforce_eager:\n",
|
||||
" vllm_args.append(\"--enforce-eager\")\n",
|
||||
"\n",
|
||||
" if enable_lora:\n",
|
||||
" vllm_args.append(\"--enable-lora\")\n",
|
||||
"\n",
|
||||
" if enable_chunked_prefill:\n",
|
||||
" vllm_args.append(\"--enable-chunked-prefill\")\n",
|
||||
"\n",
|
||||
" if enable_prefix_cache:\n",
|
||||
" vllm_args.append(\"--enable-prefix-caching\")\n",
|
||||
"\n",
|
||||
" if 0 < host_prefix_kv_cache_utilization_target < 1:\n",
|
||||
" vllm_args.append(\n",
|
||||
" f\"--host-prefix-kv-cache-utilization-target={host_prefix_kv_cache_utilization_target}\"\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" if model_type:\n",
|
||||
" vllm_args.append(f\"--model-type={model_type}\")\n",
|
||||
"\n",
|
||||
" if enable_llama_tool_parser:\n",
|
||||
" if \"Llama-4\" not in model_id:\n",
|
||||
" vllm_args.append(\"--enable-auto-tool-choice\")\n",
|
||||
" vllm_args.append(\"--tool-call-parser=vertex-llama-3\")\n",
|
||||
" else:\n",
|
||||
" vllm_args.append(\"--enable-auto-tool-choice\")\n",
|
||||
" vllm_args.append(\"--tool-call-parser=llama3_json\")\n",
|
||||
"\n",
|
||||
" env_vars = {\n",
|
||||
" \"MODEL_ID\": base_model_id,\n",
|
||||
" \"DEPLOY_SOURCE\": \"notebook\",\n",
|
||||
" }\n",
|
||||
"\n",
|
||||
" # HF_TOKEN is not a compulsory field and may not be defined.\n",
|
||||
" try:\n",
|
||||
" if HF_TOKEN:\n",
|
||||
" env_vars[\"HF_TOKEN\"] = HF_TOKEN\n",
|
||||
" except NameError:\n",
|
||||
" pass\n",
|
||||
"\n",
|
||||
" model = aiplatform.Model.upload(\n",
|
||||
" display_name=model_name,\n",
|
||||
" serving_container_image_uri=VLLM_DOCKER_URI,\n",
|
||||
" serving_container_args=vllm_args,\n",
|
||||
" serving_container_ports=[8080],\n",
|
||||
" serving_container_predict_route=\"/generate\",\n",
|
||||
" serving_container_health_route=\"/ping\",\n",
|
||||
" serving_container_environment_variables=env_vars,\n",
|
||||
" serving_container_shared_memory_size_mb=(16 * 1024), # 16 GB\n",
|
||||
" serving_container_deployment_timeout=7200,\n",
|
||||
" model_garden_source_model_name=(\n",
|
||||
" f\"publishers/{publisher}/models/{publisher_model_id}\"\n",
|
||||
" ),\n",
|
||||
" )\n",
|
||||
" print(\n",
|
||||
" f\"Deploying {model_name} on {machine_type} with {accelerator_count} {accelerator_type} GPU(s).\"\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" creds, _ = auth.default()\n",
|
||||
" auth_req = auth.transport.requests.Request()\n",
|
||||
" creds.refresh(auth_req)\n",
|
||||
"\n",
|
||||
" url = f\"https://{REGION}-aiplatform.googleapis.com/ui/projects/{PROJECT_ID}/locations/{REGION}/endpoints/{endpoint.name}:deployModel\"\n",
|
||||
" headers = {\n",
|
||||
" \"Content-Type\": \"application/json\",\n",
|
||||
" \"Authorization\": f\"Bearer {creds.token}\",\n",
|
||||
" }\n",
|
||||
" data = {\n",
|
||||
" \"deployedModel\": {\n",
|
||||
" \"model\": model.resource_name,\n",
|
||||
" \"displayName\": model_name,\n",
|
||||
" \"dedicatedResources\": {\n",
|
||||
" \"machineSpec\": {\n",
|
||||
" \"machineType\": machine_type,\n",
|
||||
" \"acceleratorType\": accelerator_type,\n",
|
||||
" \"acceleratorCount\": accelerator_count,\n",
|
||||
" },\n",
|
||||
" \"minReplicaCount\": min_replica_count,\n",
|
||||
" \"requiredReplicaCount\": required_replica_count,\n",
|
||||
" \"maxReplicaCount\": max_replica_count,\n",
|
||||
" },\n",
|
||||
" \"system_labels\": {\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_pytorch_gpt_oss_g4_deployment.ipynb\",\n",
|
||||
" \"NOTEBOOK_ENVIRONMENT\": common_util.get_deploy_source(),\n",
|
||||
" },\n",
|
||||
" },\n",
|
||||
" }\n",
|
||||
" if is_spot:\n",
|
||||
" data[\"deployedModel\"][\"dedicatedResources\"][\"spot\"] = True\n",
|
||||
" if autoscale_by_gpu_duty_cycle_target > 0 or autoscale_by_cpu_usage_target > 0:\n",
|
||||
" data[\"deployedModel\"][\"dedicatedResources\"][\"autoscalingMetricSpecs\"] = []\n",
|
||||
" if autoscale_by_gpu_duty_cycle_target > 0:\n",
|
||||
" data[\"deployedModel\"][\"dedicatedResources\"][\n",
|
||||
" \"autoscalingMetricSpecs\"\n",
|
||||
" ].append(\n",
|
||||
" {\n",
|
||||
" \"metricName\": \"aiplatform.googleapis.com/prediction/online/accelerator/duty_cycle\",\n",
|
||||
" \"target\": autoscale_by_gpu_duty_cycle_target,\n",
|
||||
" }\n",
|
||||
" )\n",
|
||||
" if autoscale_by_cpu_usage_target > 0:\n",
|
||||
" data[\"deployedModel\"][\"dedicatedResources\"][\n",
|
||||
" \"autoscalingMetricSpecs\"\n",
|
||||
" ].append(\n",
|
||||
" {\n",
|
||||
" \"metricName\": \"aiplatform.googleapis.com/prediction/online/cpu/utilization\",\n",
|
||||
" \"target\": autoscale_by_cpu_usage_target,\n",
|
||||
" }\n",
|
||||
" )\n",
|
||||
" response = requests.post(url, headers=headers, json=data)\n",
|
||||
" print(f\"Deploy Model response: {response.json()}\")\n",
|
||||
" if response.status_code != 200 or \"name\" not in response.json():\n",
|
||||
" raise ValueError(f\"Failed to deploy model: {response.text}\")\n",
|
||||
" common_util.poll_and_wait(response.json()[\"name\"], REGION, 7200)\n",
|
||||
" print(\"endpoint_name:\", endpoint.name)\n",
|
||||
"\n",
|
||||
" return model, endpoint\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"models[\"vllm_gpu\"], endpoints[\"vllm_gpu\"] = deploy_model_vllm(\n",
|
||||
" model_name=common_util.get_job_name_with_datetime(prefix=\"gpt-oss-serve\"),\n",
|
||||
" model_id=model_id,\n",
|
||||
" publisher=\"openai\",\n",
|
||||
" publisher_model_id=\"gpt-oss\",\n",
|
||||
" base_model_id=hf_model_id,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" gpu_memory_utilization=gpu_memory_utilization,\n",
|
||||
" max_model_len=max_model_len,\n",
|
||||
" enable_trust_remote_code=False,\n",
|
||||
" enforce_eager=False,\n",
|
||||
" enable_lora=False,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" min_replica_count=min_replica_count,\n",
|
||||
" max_replica_count=max_replica_count,\n",
|
||||
" required_replica_count=required_replica_count,\n",
|
||||
" autoscale_by_gpu_duty_cycle_target=autoscale_by_gpu_duty_cycle_target,\n",
|
||||
" autoscale_by_cpu_usage_target=autoscale_by_cpu_usage_target,\n",
|
||||
")\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "rDHsCOqvFYBi"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Raw predict\n",
|
||||
"\n",
|
||||
"# @markdown Once deployment succeeds, you can send requests to the endpoint with text prompts. Sampling parameters supported by vLLM can be found [here](https://docs.vllm.ai/en/latest/dev/sampling_params.html).\n",
|
||||
"\n",
|
||||
"# @markdown Example:\n",
|
||||
"\n",
|
||||
"# @markdown ```\n",
|
||||
"# @markdown Human: What is a car?\n",
|
||||
"# @markdown Assistant: A car, or a motor car, is a road-connected human-transportation system used to move people or goods from one place to another. The term also encompasses a wide range of vehicles, including motorboats, trains, and aircrafts. Cars typically have four wheels, a cabin for passengers, and an engine or motor. They have been around since the early 19th century and are now one of the most popular forms of transportation, used for daily commuting, shopping, and other purposes.\n",
|
||||
"# @markdown ```\n",
|
||||
"# @markdown Additionally, you can moderate the generated text with Vertex AI. See [Moderate text documentation](https://cloud.google.com/natural-language/docs/moderating-text) for more details.\n",
|
||||
"\n",
|
||||
"# Loads an existing endpoint instance using the endpoint name:\n",
|
||||
"# - Using `endpoint_name = endpoint.name` allows us to get the\n",
|
||||
"# endpoint name of the endpoint `endpoint` created in the cell\n",
|
||||
"# above.\n",
|
||||
"# - Alternatively, you can set `endpoint_name = \"1234567890123456789\"` to load\n",
|
||||
"# an existing endpoint with the ID 1234567890123456789.\n",
|
||||
"# You may uncomment the code below to load an existing endpoint.\n",
|
||||
"\n",
|
||||
"# endpoint_name = \"\" # @param {type:\"string\"}\n",
|
||||
"# aip_endpoint_name = (\n",
|
||||
"# f\"projects/{PROJECT_ID}/locations/{REGION}/endpoints/{endpoint_name}\"\n",
|
||||
"# )\n",
|
||||
"# endpoint = aiplatform.Endpoint(aip_endpoint_name)\n",
|
||||
"\n",
|
||||
"prompt = \"What is a car?\" # @param {type: \"string\"}\n",
|
||||
"# @markdown If you encounter an issue like `ServiceUnavailable: 503 Took too long to respond when processing`, you can reduce the maximum number of output tokens, by lowering `max_tokens`.\n",
|
||||
"max_tokens = 50 # @param {type:\"integer\"}\n",
|
||||
"temperature = 1.0 # @param {type:\"number\"}\n",
|
||||
"top_p = 1.0 # @param {type:\"number\"}\n",
|
||||
"top_k = 1 # @param {type:\"integer\"}\n",
|
||||
"# @markdown Set `raw_response` to `True` to obtain the raw model output. Set `raw_response` to `False` to apply additional formatting in the structure of `\"Prompt:\\n{prompt.strip()}\\nOutput:\\n{output}\"`.\n",
|
||||
"raw_response = False # @param {type:\"boolean\"}\n",
|
||||
"\n",
|
||||
"# Overrides parameters for inferences.\n",
|
||||
"instances = [\n",
|
||||
" {\n",
|
||||
" \"prompt\": prompt,\n",
|
||||
" \"max_tokens\": max_tokens,\n",
|
||||
" \"temperature\": temperature,\n",
|
||||
" \"top_p\": top_p,\n",
|
||||
" \"top_k\": top_k,\n",
|
||||
" \"raw_response\": raw_response,\n",
|
||||
" },\n",
|
||||
"]\n",
|
||||
"response = endpoints[\"vllm_gpu\"].predict(\n",
|
||||
" instances=instances, use_dedicated_endpoint=use_dedicated_endpoint\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"for prediction in response.predictions:\n",
|
||||
" print(prediction)\n",
|
||||
"\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "LSG9ITWTbTb7"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Chat completion\n",
|
||||
"\n",
|
||||
"if use_dedicated_endpoint:\n",
|
||||
" DEDICATED_ENDPOINT_DNS = endpoints[\"vllm_gpu\"].gca_resource.dedicated_endpoint_dns\n",
|
||||
"ENDPOINT_RESOURCE_NAME = endpoints[\"vllm_gpu\"].resource_name\n",
|
||||
"\n",
|
||||
"# @title Chat Completions Inference\n",
|
||||
"\n",
|
||||
"# @markdown Once deployment succeeds, you can send requests to the endpoint using the OpenAI SDK.\n",
|
||||
"\n",
|
||||
"# @markdown First you will need to install the SDK and some auth-related dependencies.\n",
|
||||
"\n",
|
||||
"! pip install -qU openai google-auth requests\n",
|
||||
"\n",
|
||||
"# @markdown Next fill out some request parameters:\n",
|
||||
"\n",
|
||||
"user_message = \"How is your day going?\" # @param {type: \"string\"}\n",
|
||||
"# @markdown If you encounter the issue like `ServiceUnavailable: 503 Took too long to respond when processing`, you can reduce the maximum number of output tokens, such as set `max_tokens` as 20.\n",
|
||||
"max_tokens = 50 # @param {type: \"integer\"}\n",
|
||||
"temperature = 1.0 # @param {type: \"number\"}\n",
|
||||
"stream = False # @param {type: \"boolean\"}\n",
|
||||
"\n",
|
||||
"# @markdown Now we can send a request.\n",
|
||||
"\n",
|
||||
"import google.auth\n",
|
||||
"import openai\n",
|
||||
"\n",
|
||||
"creds, project = google.auth.default()\n",
|
||||
"auth_req = google.auth.transport.requests.Request()\n",
|
||||
"creds.refresh(auth_req)\n",
|
||||
"\n",
|
||||
"BASE_URL = (\n",
|
||||
" f\"https://{REGION}-aiplatform.googleapis.com/v1beta1/{ENDPOINT_RESOURCE_NAME}\"\n",
|
||||
")\n",
|
||||
"try:\n",
|
||||
" if use_dedicated_endpoint:\n",
|
||||
" BASE_URL = f\"https://{DEDICATED_ENDPOINT_DNS}/v1beta1/{ENDPOINT_RESOURCE_NAME}\"\n",
|
||||
"except NameError:\n",
|
||||
" pass\n",
|
||||
"\n",
|
||||
"client = openai.OpenAI(base_url=BASE_URL, api_key=creds.token)\n",
|
||||
"\n",
|
||||
"model_response = client.chat.completions.create(\n",
|
||||
" model=\"\",\n",
|
||||
" messages=[{\"role\": \"user\", \"content\": user_message}],\n",
|
||||
" temperature=temperature,\n",
|
||||
" max_tokens=max_tokens,\n",
|
||||
" stream=stream,\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"if stream:\n",
|
||||
" usage = None\n",
|
||||
" contents = []\n",
|
||||
" for chunk in model_response:\n",
|
||||
" if chunk.usage is not None:\n",
|
||||
" usage = chunk.usage\n",
|
||||
" continue\n",
|
||||
" print(chunk.choices[0].delta.content, end=\"\")\n",
|
||||
" contents.append(chunk.choices[0].delta.content)\n",
|
||||
" print(f\"\\n\\n{usage}\")\n",
|
||||
"else:\n",
|
||||
" print(model_response)\n",
|
||||
"\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "tqtxJakIapIg"
|
||||
},
|
||||
"source": [
|
||||
"## Clean up resources"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "kzgEmmd0aiUM"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Delete the models and endpoints\n",
|
||||
"\n",
|
||||
"# @markdown Delete the experiment models and endpoints to recycle the resources\n",
|
||||
"# @markdown and avoid unnecessary continuous charges that may incur.\n",
|
||||
"\n",
|
||||
"# Undeploy model and delete endpoint.\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)\n",
|
||||
"\n",
|
||||
"# Delete models.\n",
|
||||
"for model in models.values():\n",
|
||||
" model.delete()"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "model_garden_pytorch_gpt_oss_g4_deployment.ipynb",
|
||||
"toc_visible": true
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
@@ -109,7 +109,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -123,7 +123,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -111,7 +111,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -109,7 +109,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -4,11 +4,12 @@
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "7d9bbf86da5e"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Copyright 2024 Google LLC\n",
|
||||
"# Copyright 2025 Google LLC\n",
|
||||
"#\n",
|
||||
"# Licensed under the Apache License, Version 2.0 (the \"License\");\n",
|
||||
"# you may not use this file except in compliance with the License.\n",
|
||||
@@ -31,291 +32,395 @@
|
||||
"source": [
|
||||
"# Vertex AI Model Garden - LaMa\n",
|
||||
"\n",
|
||||
"<table align=\"left\">\n",
|
||||
" <td>\n",
|
||||
" <a href=\"https://colab.research.google.com/github/GoogleCloudPlatform/vertex-ai-samples/blob/main/notebooks/community/model_garden/model_garden_pytorch_lama.ipynb\">\n",
|
||||
" <img src=\"https://cloud.google.com/ml-engine/images/colab-logo-32px.png\" alt=\"Colab logo\"> Run in Colab\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td>\n",
|
||||
" <a href=\"https://github.com/GoogleCloudPlatform/vertex-ai-samples/blob/main/notebooks/community/model_garden/model_garden_pytorch_lama.ipynb\">\n",
|
||||
" <img src=\"https://github.githubassets.com/assets/GitHub-Mark-ea2971cee799.png\" alt=\"GitHub logo\">\n",
|
||||
" View on GitHub\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td>\n",
|
||||
"<table><tbody><tr>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/notebooks/deploy-notebook?download_url=https://raw.githubusercontent.com/GoogleCloudPlatform/vertex-ai-samples/main/notebooks/community/model_garden/model_garden_pytorch_lama.ipynb\">\n",
|
||||
" <img src=\"https://lh3.googleusercontent.com/UiNooY4LUgW_oTvpsNhPpQzsstV5W8F7rYgxgGBD85cWJoLmrOzhVs_ksK_vgx40SHs7jCqkTkCk=e14-rj-sc0xffffff-h130-w32\" alt=\"Vertex AI logo\">\n",
|
||||
"Open in Vertex AI Workbench\n",
|
||||
" <img alt=\"Workbench logo\" src=\"https://lh3.googleusercontent.com/UiNooY4LUgW_oTvpsNhPpQzsstV5W8F7rYgxgGBD85cWJoLmrOzhVs_ksK_vgx40SHs7jCqkTkCk=e14-rj-sc0xffffff-h130-w32\" width=\"32px\"><br> Run in Workbench\n",
|
||||
" </a>\n",
|
||||
" (a Python-3 CPU notebook is recommended)\n",
|
||||
" </td>\n",
|
||||
"</table>"
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/colab/import/https:%2F%2Fraw.githubusercontent.com%2FGoogleCloudPlatform%2Fvertex-ai-samples%2Fmain%2Fnotebooks%2Fcommunity%2Fmodel_garden%2Fmodel_garden_pytorch_lama.ipynb\">\n",
|
||||
" <img alt=\"Google Cloud Colab Enterprise logo\" src=\"https://lh3.googleusercontent.com/JmcxdQi-qOpctIvWKgPtrzZdJJK-J3sWE1RsfjZNwshCFgE_9fULcNpuXYTilIR2hjwN\" width=\"32px\"><br> Run in Colab Enterprise\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://github.com/GoogleCloudPlatform/vertex-ai-samples/blob/main/notebooks/community/model_garden/model_garden_pytorch_lama.ipynb\">\n",
|
||||
" <img alt=\"GitHub logo\" src=\"https://github.githubassets.com/assets/GitHub-Mark-ea2971cee799.png\" width=\"32px\"><br> View on GitHub\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
"</tr></tbody></table>"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "cd8433ec804a"
|
||||
"id": "3de7470326a2"
|
||||
},
|
||||
"source": [
|
||||
"## Overview\n",
|
||||
"\n",
|
||||
"This notebook demonstrates deploying a prebuilt [LaMa](https://github.com/advimman/lama) model in Vertex AI.\n",
|
||||
"This notebook demonstrates how to deploy a **LaMa** open model on Google Cloud Vertex AI.\n",
|
||||
"\n",
|
||||
"### Objective\n",
|
||||
"### Objectives\n",
|
||||
"\n",
|
||||
"- Deploy a prebuilt LaMa model to a Vertex Endpoint and query it.\n",
|
||||
"- Deploy LaMa using containerized backends like [vLLM](https://github.com/vllm-project/vllm) on GPU.\n",
|
||||
"- Use the deployed model to serve chat completion requests for both text and multimodal inputs.\n",
|
||||
"\n",
|
||||
"### File a Bug\n",
|
||||
"\n",
|
||||
"If you encounter issues with this notebook, report them on [GitHub](https://github.com/GoogleCloudPlatform/vertex-ai-samples/issues/new).\n",
|
||||
"\n",
|
||||
"### Costs\n",
|
||||
"\n",
|
||||
"This tutorial uses billable components of Google Cloud:\n",
|
||||
"\n",
|
||||
"* Vertex AI\n",
|
||||
"- Vertex AI\n",
|
||||
"- Cloud Storage\n",
|
||||
"\n",
|
||||
"Learn about [Vertex AI pricing](https://cloud.google.com/vertex-ai/pricing) and use the [Pricing Calculator](https://cloud.google.com/products/calculator/) to generate a cost estimate based on your projected usage."
|
||||
"Refer to the [Vertex AI pricing](https://cloud.google.com/vertex-ai/pricing) and [Cloud Storage pricing](https://cloud.google.com/storage/pricing) pages for more information. Use the [Pricing Calculator](https://cloud.google.com/products/calculator/) to estimate your projected costs."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Gl3bjJsV3k4J"
|
||||
"id": "jeYw-Czg-DFy"
|
||||
},
|
||||
"source": [
|
||||
"## Before you begin\n",
|
||||
"\n",
|
||||
"**NOTE**: Jupyter runs lines prefixed with `!` as shell commands, and it interpolates Python variables prefixed with `$` into these commands."
|
||||
"## Get Started"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "CaCslNQE37P_"
|
||||
"id": "KgyhGvEzBDkj"
|
||||
},
|
||||
"source": [
|
||||
"### Setup notebook"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "fb671e75ca7b"
|
||||
},
|
||||
"source": [
|
||||
"#### Colab only\n",
|
||||
"Run the following commands for Colab and skip this section if you are using Workbench."
|
||||
"### Install Vertex AI SDK and other required packages"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "dc8ee367fb42"
|
||||
"cellView": "form",
|
||||
"id": "iCacdLqG-IsH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"google.colab\" in str(get_ipython()):\n",
|
||||
" ! pip3 install --upgrade google-cloud-aiplatform\n",
|
||||
" from google.colab import auth as google_auth\n",
|
||||
"\n",
|
||||
" google_auth.authenticate_user()\n",
|
||||
" ! pip3 install --upgrade pip\n",
|
||||
"\n",
|
||||
" # Restart the notebook kernel after installs.\n",
|
||||
" import IPython\n",
|
||||
"\n",
|
||||
" app = IPython.Application.instance()\n",
|
||||
" app.kernel.do_shutdown(True)"
|
||||
"%pip install --upgrade --force-reinstall --quiet 'google-cloud-aiplatform>=1.106.0' 'openai' 'google-auth==2.27.0' 'requests==2.32.3'"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "bb7adab99e41"
|
||||
"id": "HUKCrpBy-3yf"
|
||||
},
|
||||
"source": [
|
||||
"### Setup Google Cloud project\n",
|
||||
"### Authenticate the Notebook Environment (Colab only)\n",
|
||||
"\n",
|
||||
"1. [Select or create a Google Cloud project](https://console.cloud.google.com/cloud-resource-manager). When you first create an account, you get a $300 free credit towards your compute/storage costs.\n",
|
||||
"\n",
|
||||
"1. [Make sure that billing is enabled for your project](https://cloud.google.com/billing/docs/how-to/modify-project).\n",
|
||||
"\n",
|
||||
"1. [Enable the Vertex AI API and Compute Engine API](https://console.cloud.google.com/flows/enableapi?apiid=aiplatform.googleapis.com,compute_component).\n",
|
||||
"\n",
|
||||
"1. [Create a Cloud Storage bucket](https://cloud.google.com/storage/docs/creating-buckets) for storing experiment outputs.\n",
|
||||
"\n",
|
||||
"1. [Create a service account](https://cloud.google.com/iam/docs/service-accounts-create#iam-service-accounts-create-console) with `Vertex AI User` and `Storage Object Admin` roles for deploying fine tuned model to Vertex AI endpoint."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "6c460088b873"
|
||||
},
|
||||
"source": [
|
||||
"Fill following variables for experiments environment:"
|
||||
"If you're running this notebook in Google Colab, run the following cell to authenticate."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "855d6b96f291"
|
||||
"cellView": "form",
|
||||
"id": "JXwCT1kn-3Gu"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Cloud project id.\n",
|
||||
"PROJECT_ID = \"\" # @param {type:\"string\"}\n",
|
||||
"import sys\n",
|
||||
"\n",
|
||||
"# The region you want to launch jobs in.\n",
|
||||
"REGION = \"us-central1\" # @param {type:\"string\"}\n",
|
||||
"if \"google.colab\" in sys.modules:\n",
|
||||
" from google.colab import auth\n",
|
||||
"\n",
|
||||
"# The Cloud Storage bucket for storing experiments output.\n",
|
||||
"GCS_BUCKET = \"gs://\" # @param {type:\"string\"}\n",
|
||||
"\n",
|
||||
"# The service account for deploying fine tuned model.\n",
|
||||
"# The service account looks like:\n",
|
||||
"# '<account_name>@<project>.iam.gserviceaccount.com'\n",
|
||||
"SERVICE_ACCOUNT = \"\" # @param {type:\"string\"}"
|
||||
" auth.authenticate_user()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "e828eb320337"
|
||||
"id": "AcW2nwB8-7yC"
|
||||
},
|
||||
"source": [
|
||||
"Initialize Vertex-AI API:"
|
||||
"### Set Google Cloud Project Information\n",
|
||||
"\n",
|
||||
"To get started with Vertex AI, ensure you have an existing Google Cloud project and that the [Vertex AI API is enabled](https://console.cloud.google.com/flows/enableapi?apiid=aiplatform.googleapis.com).\n",
|
||||
"\n",
|
||||
"See the guide on [setting up your project and development environment](https://cloud.google.com/vertex-ai/docs/start/cloud-environment). Also confirm that [billing is enabled](https://cloud.google.com/billing/docs/how-to/modify-project).\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "12cd25839741"
|
||||
"cellView": "form",
|
||||
"id": "eIVLp0oE--k-"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from google.cloud import aiplatform\n",
|
||||
"# Use the environment variable if the user doesn't provide Project ID.\n",
|
||||
"import os\n",
|
||||
"\n",
|
||||
"aiplatform.init(project=PROJECT_ID, location=REGION, staging_bucket=GCS_BUCKET)"
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "2cc825514deb"
|
||||
"id": "Q0CXrvcZH_aw"
|
||||
},
|
||||
"source": [
|
||||
"### Define constants"
|
||||
"### Import libraries"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "b42bd4fa2b2d"
|
||||
"cellView": "form",
|
||||
"id": "3G2UXB82ICs6"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# The pre-built serving docker image. It contains serving scripts and models.\n",
|
||||
"SERVE_DOCKER_URI = \"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/lama-serve:20240125_0903_RC00\""
|
||||
"from vertexai import model_garden"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "0c250872074f"
|
||||
"id": "upYRiGtP_-iN"
|
||||
},
|
||||
"source": [
|
||||
"### Define common functions"
|
||||
"## Deploy model"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "H2WC_0hXDVXc"
|
||||
},
|
||||
"source": [
|
||||
"### Choose model variant"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "u41zbNa2EoFq"
|
||||
},
|
||||
"source": [
|
||||
"You can proceed with the default model variant or select a different one."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "8759e624ebc0"
|
||||
"cellView": "form",
|
||||
"id": "-fgC4NLSDkF7"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import base64\n",
|
||||
"from datetime import datetime\n",
|
||||
"from io import BytesIO\n",
|
||||
"from typing import List, Tuple\n",
|
||||
"model_version = \"lama\" # @param [\"lama\"] {isTemplate:true}\n",
|
||||
"MODEL_NAME = f\"advimman/lama@{model_version}\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "VRnUgU8LF3_i"
|
||||
},
|
||||
"source": [
|
||||
"To see all deployable model variants available in Model Garden, use:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "-QLd-wshF6sB"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"all_model_versions = model_garden.list_deployable_models(\n",
|
||||
" model_filter=\"lama\", list_hf_models=False\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "N0UeFHa2GO63"
|
||||
},
|
||||
"source": [
|
||||
"Once you've selected a model variant, initialize it:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "GZiV3trBBcA3"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model = model_garden.OpenModel(MODEL_NAME)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-0cL378wFlvf"
|
||||
},
|
||||
"source": [
|
||||
"### Check the Deployment Configuration\n",
|
||||
"\n",
|
||||
"import requests\n",
|
||||
"from google.cloud import aiplatform\n",
|
||||
"from PIL import Image\n",
|
||||
"Use the `list_deploy_options()` method to view the verified deployment configurations for your selected model. This helps ensure you have sufficient resources (e.g., GPU quota) available to deploy it."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "zm73g7vFFm9N"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"deploy_options = model.list_deploy_options(concise=True)\n",
|
||||
"print(deploy_options)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "WjV499VsGwrD"
|
||||
},
|
||||
"source": [
|
||||
"### Deploy the Model\n",
|
||||
"\n",
|
||||
"Now that you’ve reviewed the deployment options, use the `deploy()` method to serve the selected open model to a Vertex AI endpoint. Deployment time may vary depending on the model size and infrastructure requirements.\n",
|
||||
"\n",
|
||||
"def create_job_name(prefix: str) -> str:\n",
|
||||
" \"\"\"Return a timestamped string.\"\"\"\n",
|
||||
" now = datetime.now().strftime(\"%Y%m%d_%H%M%S\")\n",
|
||||
" job_name = f\"{prefix}-{now}\"\n",
|
||||
" return job_name\n",
|
||||
"> **Note**: If the model requires accepting a license agreement (EULA), set the `accept_eula=True` flag in the deploy call. Set `use_dedicated_endpoint` to False if you don't want to use [dedicated endpoint](https://cloud.google.com/vertex-ai/docs/general/deployment#create-dedicated-endpoint)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "wX1itVTvXdEP"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "MRmPFEPoGzsB"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "PHBtn8DQp-ID"
|
||||
},
|
||||
"source": [
|
||||
"Alternatively, you can select one of the verified deployment configurations listed above."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "ADsJG8JYqI6c"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/lama-serve:20240125_0903_RC00\",\n",
|
||||
" machine_type=\"g2-standard-24\",\n",
|
||||
" accelerator_type=\"NVIDIA_L4\",\n",
|
||||
" accelerator_count=2,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "kqSUK2CwsImi"
|
||||
},
|
||||
"source": [
|
||||
"To further customize your deployment, you can configure:\n",
|
||||
"\n",
|
||||
"- **Compute Resources**: Machine type, replica count (min/max), accelerator type and quantity.\n",
|
||||
"- **Infrastructure**: Use Spot VMs, reservation affinity, or dedicated endpoints.\n",
|
||||
"- **Serving Container**: Customize container image, ports, health checks, and environment variables.\n",
|
||||
"\n",
|
||||
"def download_image(url: str) -> Image.Image:\n",
|
||||
" \"\"\"Get image given a URL.\"\"\"\n",
|
||||
" response = requests.get(url)\n",
|
||||
" return Image.open(BytesIO(response.content))\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def image_to_base64(image: Image.Image, format=\"JPEG\") -> str:\n",
|
||||
" \"\"\"Convert an image to its base64 representation.\"\"\"\n",
|
||||
" buffer = BytesIO()\n",
|
||||
" image.save(buffer, format=format)\n",
|
||||
" image_str = base64.b64encode(buffer.getvalue()).decode(\"utf-8\")\n",
|
||||
" return image_str\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def base64_to_image(image_str: str) -> Image.Image:\n",
|
||||
" \"\"\"Convert an image from its base64 representation.\"\"\"\n",
|
||||
" image = Image.open(BytesIO(base64.b64decode(image_str)))\n",
|
||||
" return image\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def image_grid(imgs: List[Image.Image], rows: int = 2, cols: int = 2):\n",
|
||||
" \"\"\"Display images in a grid.\"\"\"\n",
|
||||
" w, h = imgs[0].size\n",
|
||||
" grid = Image.new(\"RGB\", size=(cols * w, rows * h))\n",
|
||||
" for i, img in enumerate(imgs):\n",
|
||||
" grid.paste(img, box=(i % cols * w, i // cols * h))\n",
|
||||
" return grid\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def deploy_model(\n",
|
||||
" model_name: str,\n",
|
||||
" machine_type: str = \"g2-standard-24\",\n",
|
||||
" accelerator_type: str = \"NVIDIA_L4\",\n",
|
||||
" accelerator_count: int = 2,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Upload a model to Model registry and deploy it to a Vertex Endpoint.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(display_name=f\"{model_name}-endpoint\")\n",
|
||||
" serving_env = {\"MODEL_ID\": \"lama\", \"DEPLOY_SOURCE\": \"notebook\"}\n",
|
||||
"\n",
|
||||
" model = aiplatform.Model.upload(\n",
|
||||
" display_name=model_name,\n",
|
||||
" serving_container_image_uri=SERVE_DOCKER_URI,\n",
|
||||
" serving_container_ports=[7080],\n",
|
||||
" serving_container_predict_route=\"/predictions/lama\",\n",
|
||||
" serving_container_health_route=\"/ping\",\n",
|
||||
" serving_container_environment_variables=serving_env,\n",
|
||||
" model_garden_source_model_name=\"publishers/advimman/models/lama\"\n",
|
||||
" )\n",
|
||||
" model.deploy(\n",
|
||||
" endpoint=endpoint,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" service_account=SERVICE_ACCOUNT,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_pytorch_lama.ipynb\"\n",
|
||||
" },\n",
|
||||
" )\n",
|
||||
" return model, endpoint"
|
||||
"See the [Model Garden SDK README](https://github.com/googleapis/python-aiplatform/blob/main/vertexai/model_garden/README.md) for advanced configuration options."
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -333,11 +438,14 @@
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "ivIxrAvNntMM"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Download and unzip images and masks.\n",
|
||||
"!pip install gdown\n",
|
||||
"\n",
|
||||
"!gdown --fuzzy https://drive.google.com/file/d/1p3g1XWECRuybw423aKWmToi6YrjZWq3n/view?usp=drive_link\n",
|
||||
"!unzip LaMa_test_images.zip\n",
|
||||
"\n",
|
||||
@@ -345,50 +453,6 @@
|
||||
"!ls LaMa_test_images"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "90d3c379090e"
|
||||
},
|
||||
"source": [
|
||||
"## Upload and deploy models"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "1cc26e68d7b0"
|
||||
},
|
||||
"source": [
|
||||
"This section uploads the LaMa model to Model Registry and deploys it on the Endpoint.\n",
|
||||
"\n",
|
||||
"When deployed on two L4 GPUs, the averaged inference time of a request is ~15 seconds.\n",
|
||||
"\n",
|
||||
"The model deployment step will take ~15 minutes to complete."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"id": "a881564da1d8"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model, endpoint = deploy_model(\n",
|
||||
" model_name=create_job_name(\"lama\"),\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "80b3fd2ace09"
|
||||
},
|
||||
"source": [
|
||||
"NOTE: The model weights will be downloaded after the deployment succeeds. Thus additional 5 minutes of waiting time is needed **after** the above model deployment step succeeds and before you run the next step below. Otherwise you might see a `ServiceUnavailable: 503 502:Bad Gateway` error when you send requests to the endpoint."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -402,10 +466,23 @@
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "K-Pu4TMSNy81"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import importlib\n",
|
||||
"\n",
|
||||
"from PIL import Image\n",
|
||||
"\n",
|
||||
"# Import the necessary packages.\n",
|
||||
"! rm -rf vertex-ai-samples && git clone https://github.com/GoogleCloudPlatform/vertex-ai-samples.git\n",
|
||||
"! cd vertex-ai-samples\n",
|
||||
"\n",
|
||||
"common_util = importlib.import_module(\n",
|
||||
" \"vertex-ai-samples.notebooks.community.model_garden.docker_source_codes.notebook_util.common_util\"\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"init_image_name = \"bench2\" # @param {type:\"string\"}\n",
|
||||
"init_mask_name = \"bench2_mask\" # @param {type:\"string\"}\n",
|
||||
"\n",
|
||||
@@ -429,19 +506,21 @@
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "ca1761afb66f"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"instances = [\n",
|
||||
" {\n",
|
||||
" \"image\": image_to_base64(init_image),\n",
|
||||
" \"mask\": image_to_base64(mask_image),\n",
|
||||
" \"image\": common_util.image_to_base64(init_image),\n",
|
||||
" \"mask\": common_util.image_to_base64(mask_image),\n",
|
||||
" \"refine\": True,\n",
|
||||
" },\n",
|
||||
"]\n",
|
||||
"\n",
|
||||
"response = endpoint.predict(instances=instances)\n",
|
||||
"output_image = [base64_to_image(image) for image in response.predictions][0]\n",
|
||||
"output_image = [common_util.base64_to_image(image) for image in response.predictions][0]\n",
|
||||
"display(output_image)"
|
||||
]
|
||||
},
|
||||
@@ -458,15 +537,17 @@
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "911406c1561e"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Undeploy model and delete endpoint.\n",
|
||||
"endpoint.delete(force=True)\n",
|
||||
"# @title Delete the endpoints\n",
|
||||
"\n",
|
||||
"# Delete models.\n",
|
||||
"model.delete()"
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
],
|
||||
|
||||
@@ -110,7 +110,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -136,7 +136,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -131,7 +131,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -104,7 +104,8 @@
|
||||
"! pip install --upgrade --quiet gcsfs==2024.3.1\n",
|
||||
"! pip install --upgrade --quiet accelerate==0.34.2\n",
|
||||
"! pip install --upgrade --quiet transformers==4.47.1\n",
|
||||
"! pip install --upgrade --quiet datasets==2.20.0"
|
||||
"! pip install --upgrade --quiet datasets==2.20.0\n",
|
||||
"! pip install --upgrade --quiet google-cloud-aiplatform==1.130.0"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -139,7 +140,7 @@
|
||||
"\n",
|
||||
"REGION = \"\" # @param {type:\"string\"}\n",
|
||||
"\n",
|
||||
"# Import the necessary packages\n",
|
||||
"# Import the necessary packages.\n",
|
||||
"! rm -rf vertex-ai-samples && git clone https://github.com/GoogleCloudPlatform/vertex-ai-samples.git\n",
|
||||
"! cd vertex-ai-samples && git reset --hard 7ae13b346a72ee2a2dc8152dd40c6ddd72d6c810\n",
|
||||
"\n",
|
||||
@@ -266,9 +267,7 @@
|
||||
" VERTEX_AI_MODEL_GARDEN_LLAMA3_1\n",
|
||||
" ), \"Click the agreement of Llama3.1 in Vertex AI Model Garden, and get the GCS path of the model artifacts.\"\n",
|
||||
"\n",
|
||||
"MODEL_BUCKET = VERTEX_AI_MODEL_GARDEN_LLAMA3_1\n",
|
||||
"\n",
|
||||
"# @markdown ---"
|
||||
"MODEL_BUCKET = VERTEX_AI_MODEL_GARDEN_LLAMA3_1"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -451,6 +450,13 @@
|
||||
"# @markdown Acceletor type to use for training.\n",
|
||||
"training_accelerator_type = \"NVIDIA_A100_80GB\" # @param [\"NVIDIA_A100_80GB\", \"NVIDIA_H100_80GB\"]\n",
|
||||
"\n",
|
||||
"# @markdown Set the Training Region. If not set, it will be set to default region.\n",
|
||||
"TRAINING_REGION = \"\" # @param {type: \"string\"}\n",
|
||||
"if not TRAINING_REGION:\n",
|
||||
" TRAINING_REGION = REGION\n",
|
||||
"\n",
|
||||
"aiplatform.init(location=TRAINING_REGION)\n",
|
||||
"\n",
|
||||
"# The pre-built training docker image.\n",
|
||||
"if training_accelerator_type == \"NVIDIA_A100_80GB\":\n",
|
||||
" repo = \"us-docker.pkg.dev/vertex-ai-restricted\"\n",
|
||||
@@ -466,7 +472,7 @@
|
||||
" is_restricted_image = False\n",
|
||||
" is_dynamic_workload_scheduler = True\n",
|
||||
" dws_kwargs = {\n",
|
||||
" \"max_wait_duration\": 1800, # 30 minutes\n",
|
||||
" \"max_wait_duration\": 5400, # 90 minutes\n",
|
||||
" \"scheduling_strategy\": gca_custom_job_compat.Scheduling.Strategy.FLEX_START,\n",
|
||||
" }\n",
|
||||
"\n",
|
||||
@@ -544,7 +550,7 @@
|
||||
"\n",
|
||||
"common_util.check_quota(\n",
|
||||
" project_id=PROJECT_ID,\n",
|
||||
" region=REGION,\n",
|
||||
" region=TRAINING_REGION,\n",
|
||||
" accelerator_type=training_accelerator_type,\n",
|
||||
" accelerator_count=per_node_accelerator_count * replica_count,\n",
|
||||
" is_for_training=True,\n",
|
||||
@@ -701,18 +707,28 @@
|
||||
"# @markdown Set `RUN_EVALUATION` to False to skip the evaluation job.\n",
|
||||
"RUN_EVALUATION = True # @param {type:\"boolean\"}\n",
|
||||
"\n",
|
||||
"# @markdown Set the Evaluation Region. If not set, it will be set to default region.\n",
|
||||
"EVAL_REGION = \"\" # @param {type: \"string\"}\n",
|
||||
"if not EVAL_REGION:\n",
|
||||
" EVAL_REGION = REGION\n",
|
||||
"\n",
|
||||
"aiplatform.init(location=EVAL_REGION)\n",
|
||||
"\n",
|
||||
"if \"8b\" in base_model_id.lower():\n",
|
||||
" eval_machine_type = \"g2-standard-24\"\n",
|
||||
" eval_accelerator_type = \"NVIDIA_L4\"\n",
|
||||
" eval_accelerator_count = 2\n",
|
||||
" dws_kwargs = {}\n",
|
||||
" is_dynamic_workload_scheduler = False\n",
|
||||
" dws_kwargs = {\n",
|
||||
" \"max_wait_duration\": 10800, # 180 minutes\n",
|
||||
" \"scheduling_strategy\": gca_custom_job_compat.Scheduling.Strategy.FLEX_START,\n",
|
||||
" }\n",
|
||||
" is_dynamic_workload_scheduler = True\n",
|
||||
"elif \"70b\" in base_model_id.lower():\n",
|
||||
" eval_machine_type = \"a2-ultragpu-4g\"\n",
|
||||
" eval_accelerator_type = \"NVIDIA_A100_80GB\"\n",
|
||||
" eval_accelerator_count = 4\n",
|
||||
" dws_kwargs = {\n",
|
||||
" \"max_wait_duration\": 1800, # 30 minutes\n",
|
||||
" \"max_wait_duration\": 5400, # 90 minutes\n",
|
||||
" \"scheduling_strategy\": gca_custom_job_compat.Scheduling.Strategy.FLEX_START,\n",
|
||||
" }\n",
|
||||
" is_dynamic_workload_scheduler = True\n",
|
||||
@@ -756,7 +772,7 @@
|
||||
" ]\n",
|
||||
" common_util.check_quota(\n",
|
||||
" project_id=PROJECT_ID,\n",
|
||||
" region=REGION,\n",
|
||||
" region=EVAL_REGION,\n",
|
||||
" accelerator_type=eval_accelerator_type,\n",
|
||||
" accelerator_count=eval_accelerator_count,\n",
|
||||
" is_for_training=True,\n",
|
||||
@@ -801,6 +817,16 @@
|
||||
"# The pre-built serving docker image for vLLM.\n",
|
||||
"VLLM_DOCKER_URI = \"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20250116_0916_RC00\"\n",
|
||||
"\n",
|
||||
"# @markdown Choose whether to use a [Spot VM](https://cloud.google.com/compute/docs/instances/spot) for the deployment.\n",
|
||||
"is_spot = False # @param {type:\"boolean\"}\n",
|
||||
"\n",
|
||||
"# @markdown Set the Deployment Region. If not set, it will be set to default region.\n",
|
||||
"DEPLOY_REGION = \"\" # @param {type: \"string\"}\n",
|
||||
"if not DEPLOY_REGION:\n",
|
||||
" DEPLOY_REGION = REGION\n",
|
||||
"\n",
|
||||
"aiplatform.init(location=DEPLOY_REGION)\n",
|
||||
"\n",
|
||||
"# Find Vertex AI prediction supported accelerators and regions [here](https://cloud.google.com/vertex-ai/docs/predictions/configure-compute).\n",
|
||||
"if \"8b\" in base_model_id.lower():\n",
|
||||
" machine_type = \"g2-standard-12\"\n",
|
||||
@@ -819,7 +845,7 @@
|
||||
"\n",
|
||||
"common_util.check_quota(\n",
|
||||
" project_id=PROJECT_ID,\n",
|
||||
" region=REGION,\n",
|
||||
" region=DEPLOY_REGION,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=per_node_accelerator_count,\n",
|
||||
" is_for_training=False,\n",
|
||||
@@ -873,6 +899,7 @@
|
||||
" max_num_seqs: int = 256,\n",
|
||||
" model_type: str = None,\n",
|
||||
" enable_llama_tool_parser: bool = False,\n",
|
||||
" is_spot: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys trained models with vLLM into Vertex AI.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
@@ -967,6 +994,7 @@
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" service_account=service_account,\n",
|
||||
" spot=is_spot,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_pytorch_llama3_1_finetuning.ipynb\",\n",
|
||||
" \"NOTEBOOK_ENVIRONMENT\": get_deploy_source(),\n",
|
||||
@@ -1025,6 +1053,7 @@
|
||||
" max_model_len=max_model_len,\n",
|
||||
" enable_lora=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" is_spot=is_spot,\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
|
||||
+1
-1
@@ -136,7 +136,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -127,7 +127,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
@@ -1274,7 +1274,7 @@
|
||||
"\n",
|
||||
"# @markdown Next fill out some request parameters:\n",
|
||||
"\n",
|
||||
"user_image = \"https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg\"\n",
|
||||
"user_image = \"https://images.google.com/images/branding/googlelogo/2x/googlelogo_color_272x92dp.png\"\n",
|
||||
"user_message = \"What is in the image?\" # @param {type: \"string\"}\n",
|
||||
"# @markdown If you encounter the issue like `ServiceUnavailable: 503 Took too long to respond when processing`, you can reduce the maximum number of output tokens, such as set `max_tokens` as 20.\n",
|
||||
"max_tokens = 50 # @param {type: \"integer\"}\n",
|
||||
|
||||
@@ -165,14 +165,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -329,6 +334,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -338,7 +355,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -362,16 +379,35 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai-restricted/vertex-vision-model-garden-dockers/hex-llm-serve:stable\",\n",
|
||||
" machine_type=\"ct6e-standard-8t\",\n",
|
||||
" accelerator_type=\"ACCELERATOR_TYPE_UNSPECIFIED\",\n",
|
||||
" accelerator_count=0,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/sglang-serve.cu124.0-4.ubuntu2204.py310:model-garden.sglang-0-4-release_20250831.00_p0\",\n",
|
||||
" machine_type=\"a3-ultragpu-8g\",\n",
|
||||
" accelerator_type=\"NVIDIA_H200_141GB\",\n",
|
||||
" accelerator_count=8,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -834,7 +870,7 @@
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
@@ -104,7 +104,8 @@
|
||||
"! pip install --upgrade --quiet gcsfs==2024.3.1\n",
|
||||
"! pip install --upgrade --quiet accelerate==0.34.2\n",
|
||||
"! pip install --upgrade --quiet transformers==4.47.1\n",
|
||||
"! pip install --upgrade --quiet datasets==2.20.0"
|
||||
"! pip install --upgrade --quiet datasets==2.20.0\n",
|
||||
"! pip install --upgrade --quiet google-cloud-aiplatform==1.130.0"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -849,6 +850,7 @@
|
||||
" max_num_seqs: int = 256,\n",
|
||||
" model_type: str = None,\n",
|
||||
" enable_llama_tool_parser: bool = False,\n",
|
||||
" is_spot: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys trained models with vLLM into Vertex AI.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
@@ -943,6 +945,7 @@
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" service_account=service_account,\n",
|
||||
" spot=is_spot,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_pytorch_llama3_3_finetuning.ipynb\",\n",
|
||||
" \"NOTEBOOK_ENVIRONMENT\": get_deploy_source(),\n",
|
||||
|
||||
+553
@@ -0,0 +1,553 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "SgQ6t5bqZVlH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Copyright 2025 Google LLC\n",
|
||||
"#\n",
|
||||
"# Licensed under the Apache License, Version 2.0 (the \"License\");\n",
|
||||
"# you may not use this file except in compliance with the License.\n",
|
||||
"# You may obtain a copy of the License at\n",
|
||||
"#\n",
|
||||
"# https://www.apache.org/licenses/LICENSE-2.0\n",
|
||||
"#\n",
|
||||
"# Unless required by applicable law or agreed to in writing, software\n",
|
||||
"# distributed under the License is distributed on an \"AS IS\" BASIS,\n",
|
||||
"# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.\n",
|
||||
"# See the License for the specific language governing permissions and\n",
|
||||
"# limitations under the License."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "99c1c3fc2ca5"
|
||||
},
|
||||
"source": [
|
||||
"# Vertex AI Model Garden - Llama 3.3 (Deployment on TPU7x)\n",
|
||||
"\n",
|
||||
"<table><tbody><tr>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/notebooks/deploy-notebook?download_url=https://raw.githubusercontent.com/GoogleCloudPlatform/vertex-ai-samples/main/notebooks/community/model_garden/model_garden_pytorch_llama3_3_tpu7x_deployment.ipynb\">\n",
|
||||
" <img alt=\"Workbench logo\" src=\"https://lh3.googleusercontent.com/UiNooY4LUgW_oTvpsNhPpQzsstV5W8F7rYgxgGBD85cWJoLmrOzhVs_ksK_vgx40SHs7jCqkTkCk=e14-rj-sc0xffffff-h130-w32\" width=\"32px\"><br> Run in Workbench\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/colab/import/https:%2F%2Fraw.githubusercontent.com%2FGoogleCloudPlatform%2Fvertex-ai-samples%2Fmain%2Fnotebooks%2Fcommunity%2Fmodel_garden%2Fmodel_garden_pytorch_llama3_3_tpu7x_deployment.ipynb\">\n",
|
||||
" <img alt=\"Google Cloud Colab Enterprise logo\" src=\"https://lh3.googleusercontent.com/JmcxdQi-qOpctIvWKgPtrzZdJJK-J3sWE1RsfjZNwshCFgE_9fULcNpuXYTilIR2hjwN\" width=\"32px\"><br> Run in Colab Enterprise\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://github.com/GoogleCloudPlatform/vertex-ai-samples/blob/main/notebooks/community/model_garden/model_garden_pytorch_llama3_3_tpu7x_deployment.ipynb\">\n",
|
||||
" <img alt=\"GitHub logo\" src=\"https://github.githubassets.com/assets/GitHub-Mark-ea2971cee799.png\" width=\"32px\"><br> View on GitHub\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
"</tr></tbody></table>"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "3de7470326a2"
|
||||
},
|
||||
"source": [
|
||||
"## Overview\n",
|
||||
"\n",
|
||||
"This notebook demonstrates serving [meta-llama/Llama-3.3-70B-Instruct](https://huggingface.co/meta-llama/Llama-3.3-70B-Instruct) models with [vLLM TPU](https://github.com/vllm-project/vllm) on [TPU7x](https://docs.cloud.google.com/tpu/docs/tpu7x) machines.\n",
|
||||
"\n",
|
||||
"### Objective\n",
|
||||
"\n",
|
||||
"- Deploy meta-llama/Llama-3.3-70B-Instruct on TPU7x machines with vLLM TPU.\n",
|
||||
"\n",
|
||||
"### File a bug\n",
|
||||
"\n",
|
||||
"File a bug on [GitHub](https://github.com/GoogleCloudPlatform/vertex-ai-samples/issues/new) if you encounter any issue with the notebook.\n",
|
||||
"\n",
|
||||
"### Costs\n",
|
||||
"\n",
|
||||
"This tutorial uses billable components of Google Cloud:\n",
|
||||
"\n",
|
||||
"* Vertex AI\n",
|
||||
"* Cloud Storage\n",
|
||||
"\n",
|
||||
"Learn about [Vertex AI pricing](https://cloud.google.com/vertex-ai/pricing), [Cloud Storage pricing](https://cloud.google.com/storage/pricing), and use the [Pricing Calculator](https://cloud.google.com/products/calculator/) to generate a cost estimate based on your projected usage."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "264c07757582"
|
||||
},
|
||||
"source": [
|
||||
"## Before you begin"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": 1,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "ax7zWynUDcjk"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Request for quota\n",
|
||||
"\n",
|
||||
"# @markdown To deploy with TPU7x machines, check that you have sufficient quota: [CustomModelServing7XTPUPerProjectPerRegion](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_tpu7x). Find the available region(s) [here](https://cloud.google.com/vertex-ai/docs/general/locations#region_considerations).\n",
|
||||
"\n",
|
||||
"# @markdown If you don't have sufficient quota, request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown You can also use Compute Engine reservations with Vertex Prediction following the instructions [here](https://cloud.google.com/vertex-ai/docs/predictions/use-reservations). Note that the GCE quota for the shared reservation will be managed separately. Shared reservation is the only GCE consumption mode."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "YXFGIp1l-qtT"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Setup Google Cloud project\n",
|
||||
"\n",
|
||||
"# @markdown 1. [Make sure that billing is enabled for your project](https://cloud.google.com/billing/docs/how-to/modify-project).\n",
|
||||
"\n",
|
||||
"# @markdown 2. **[Optional]** Set region. If not set, the region will be set automatically according to Colab Enterprise environment.\n",
|
||||
"\n",
|
||||
"REGION = \"\" # @param {type:\"string\"}\n",
|
||||
"\n",
|
||||
"# Upgrade Vertex AI SDK.\n",
|
||||
"! pip3 install --upgrade --quiet 'google-cloud-aiplatform==1.103.0'\n",
|
||||
"\n",
|
||||
"# Import the necessary packages\n",
|
||||
"import importlib # noqa: F401\n",
|
||||
"import os # noqa: F401\n",
|
||||
"from typing import Tuple # noqa: F401\n",
|
||||
"\n",
|
||||
"from google.cloud import aiplatform # noqa: F401\n",
|
||||
"\n",
|
||||
"# Upgrade Vertex AI SDK.\n",
|
||||
"if os.environ.get(\"VERTEX_PRODUCT\") != \"COLAB_ENTERPRISE\":\n",
|
||||
" ! pip install --upgrade tensorflow\n",
|
||||
"! git clone https://github.com/GoogleCloudPlatform/vertex-ai-samples.git\n",
|
||||
"\n",
|
||||
"common_util = importlib.import_module(\n",
|
||||
" \"vertex-ai-samples.notebooks.community.model_garden.docker_source_codes.notebook_util.common_util\"\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"LABEL = \"vllm_tpu\"\n",
|
||||
"models, endpoints = {}, {}\n",
|
||||
"\n",
|
||||
"# Get the default cloud project id.\n",
|
||||
"PROJECT_ID = os.environ[\"GOOGLE_CLOUD_PROJECT\"]\n",
|
||||
"\n",
|
||||
"# Get the default region for launching jobs.\n",
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ[\"GOOGLE_CLOUD_REGION\"]\n",
|
||||
"\n",
|
||||
"# Initialize Vertex AI API.\n",
|
||||
"print(\"Initializing Vertex AI API.\")\n",
|
||||
"aiplatform.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"! gcloud config set project $PROJECT_ID\n",
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"vertexai.init(\n",
|
||||
" project=PROJECT_ID,\n",
|
||||
" location=REGION,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "z-XybZjtgF9M"
|
||||
},
|
||||
"source": [
|
||||
"## Deploy Llama 3.3 with vLLM TPU"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "E8OiHHNNE_wj"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Set the model variants\n",
|
||||
"\n",
|
||||
"# @markdown Set the model to deploy.\n",
|
||||
"\n",
|
||||
"base_model_name = \"Llama-3.3-70B-Instruct\" # @param [\"Llama-3.3-70B-Instruct\"] {isTemplate:true}\n",
|
||||
"hf_model_id = \"meta-llama/\" + base_model_name\n",
|
||||
"model_user_id = \"llama3-3\"\n",
|
||||
"model_id = f\"gs://vertex-model-garden-restricted-us/llama3.3/{base_model_name}\"\n",
|
||||
"\n",
|
||||
"PUBLISHER_MODEL_NAME = (\n",
|
||||
" f\"publishers/meta/models/{model_user_id}@{base_model_name.lower()}\"\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"# @markdown Set use_dedicated_endpoint to False if you don't want to use [dedicated endpoint](https://cloud.google.com/vertex-ai/docs/general/deployment#create-dedicated-endpoint). Note that [dedicated endpoint does not support VPC Service Controls](https://cloud.google.com/vertex-ai/docs/predictions/choose-endpoint-type), uncheck the box if you are using VPC-SC.\n",
|
||||
"use_dedicated_endpoint = True # @param {type:\"boolean\"}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "acd75fc92341"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Deploy with customized configs\n",
|
||||
"\n",
|
||||
"# @markdown This section uploads the Llama-3.3-70B-Instruct model to Model Registry and deploys them to a Vertex Prediction Endpoint. It takes ~1 hour to finish.\n",
|
||||
"\n",
|
||||
"# @markdown The pre-built serving docker image.\n",
|
||||
"vLLM_TPU_DOCKER_URI = (\n",
|
||||
" \"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/vllm-serve:tpu7x\"\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"# @markdown Find Vertex AI prediction supported accelerators and regions at https://cloud.google.com/vertex-ai/docs/predictions/configure-compute.\n",
|
||||
"machine_type = \"tpu7x-standard-4t\" # @param [\"tpu7x-standard-1t\"] {isTemplate:true}\n",
|
||||
"if machine_type == \"tpu7x-standard-4t\":\n",
|
||||
" accelerator_type = \"TPU_7x\"\n",
|
||||
" accelerator_count = 4\n",
|
||||
" tensor_parallel_size = 8\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"Sample deployment options are not available.\")\n",
|
||||
"\n",
|
||||
"common_util.check_quota(\n",
|
||||
" project_id=PROJECT_ID,\n",
|
||||
" region=REGION,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" is_for_training=False,\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"TPU_DEPLOYMENT_REGION = REGION\n",
|
||||
"max_model_len = 65536\n",
|
||||
"max_num_seqs = 128\n",
|
||||
"max_num_batched_tokens = 1024\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def deploy_model_vllm_tpu(\n",
|
||||
" model_name: str,\n",
|
||||
" model_id: str,\n",
|
||||
" publisher: str,\n",
|
||||
" publisher_model_id: str,\n",
|
||||
" base_model_id: str = None,\n",
|
||||
" tensor_parallel_size: int = 1,\n",
|
||||
" machine_type: str = \"ct6e-standard-1t\",\n",
|
||||
" tpu_topology: str = \"1x1\",\n",
|
||||
" max_model_len: int = 4096,\n",
|
||||
" max_num_seqs: int = None,\n",
|
||||
" max_num_batched_tokens: int = None,\n",
|
||||
" enable_chunked_prefill: bool = False,\n",
|
||||
" enable_prefix_cache: bool = False,\n",
|
||||
" endpoint_id: str = \"\",\n",
|
||||
" min_replica_count: int = 1,\n",
|
||||
" max_replica_count: int = 1,\n",
|
||||
" use_dedicated_endpoint: bool = False,\n",
|
||||
" model_type: str = None,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys models with vLLM on TPU in Vertex AI.\"\"\"\n",
|
||||
" if endpoint_id:\n",
|
||||
" aip_endpoint_name = (\n",
|
||||
" f\"projects/{PROJECT_ID}/locations/{REGION}/endpoints/{endpoint_id}\"\n",
|
||||
" )\n",
|
||||
" endpoint = aiplatform.Endpoint(aip_endpoint_name)\n",
|
||||
" else:\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
" display_name=f\"{model_name}-endpoint\",\n",
|
||||
" location=TPU_DEPLOYMENT_REGION,\n",
|
||||
" dedicated_endpoint_enabled=use_dedicated_endpoint,\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" if not base_model_id:\n",
|
||||
" base_model_id = model_id\n",
|
||||
"\n",
|
||||
" if not tensor_parallel_size:\n",
|
||||
" tensor_parallel_size = int(machine_type[-2])\n",
|
||||
"\n",
|
||||
" num_hosts = int(tpu_topology.split(\"x\")[0])\n",
|
||||
"\n",
|
||||
" vllmtpu_args = [\n",
|
||||
" \"python\",\n",
|
||||
" \"-m\",\n",
|
||||
" \"vllm.entrypoints.api_server\",\n",
|
||||
" \"--host=0.0.0.0\",\n",
|
||||
" \"--port=7080\",\n",
|
||||
" f\"--model={model_id}\",\n",
|
||||
" f\"--tensor-parallel-size={tensor_parallel_size}\",\n",
|
||||
" f\"--max-model-len={max_model_len}\",\n",
|
||||
" ]\n",
|
||||
"\n",
|
||||
" if enable_chunked_prefill:\n",
|
||||
" vllmtpu_args.append(\"--enable-chunked-prefill\")\n",
|
||||
"\n",
|
||||
" if enable_prefix_cache:\n",
|
||||
" vllmtpu_args.append(\"--enable-prefix-caching\")\n",
|
||||
"\n",
|
||||
" if max_num_seqs is not None:\n",
|
||||
" vllmtpu_args.append(f\"--max-num-seqs={max_num_seqs}\")\n",
|
||||
"\n",
|
||||
" if max_num_batched_tokens is not None:\n",
|
||||
" vllmtpu_args.append(f\"--max-num-batched-tokens={max_num_batched_tokens}\")\n",
|
||||
"\n",
|
||||
" env_vars = {\n",
|
||||
" \"MODEL_ID\": base_model_id,\n",
|
||||
" \"DEPLOY_SOURCE\": \"notebook\",\n",
|
||||
" \"VLLM_USE_V1\": \"1\",\n",
|
||||
" }\n",
|
||||
"\n",
|
||||
" # HF_TOKEN is not a compulsory field and may not be defined.\n",
|
||||
" try:\n",
|
||||
" if HF_TOKEN:\n",
|
||||
" env_vars[\"HF_TOKEN\"] = HF_TOKEN\n",
|
||||
" except NameError:\n",
|
||||
" pass\n",
|
||||
"\n",
|
||||
" model = aiplatform.Model.upload(\n",
|
||||
" display_name=model_name,\n",
|
||||
" serving_container_image_uri=vLLM_TPU_DOCKER_URI,\n",
|
||||
" serving_container_args=vllmtpu_args,\n",
|
||||
" serving_container_ports=[7080],\n",
|
||||
" serving_container_predict_route=\"/generate\",\n",
|
||||
" serving_container_health_route=\"/ping\",\n",
|
||||
" serving_container_environment_variables=env_vars,\n",
|
||||
" serving_container_shared_memory_size_mb=(16 * 1024), # 16 GB\n",
|
||||
" serving_container_deployment_timeout=7200,\n",
|
||||
" model_garden_source_model_name=(\n",
|
||||
" f\"publishers/{publisher}/models/{publisher_model_id}\"\n",
|
||||
" ),\n",
|
||||
" location=TPU_DEPLOYMENT_REGION,\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" model.deploy(\n",
|
||||
" endpoint=endpoint,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" tpu_topology=tpu_topology if num_hosts > 1 else None,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" min_replica_count=min_replica_count,\n",
|
||||
" max_replica_count=max_replica_count,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_pytorch_llama3_3_tpu7x_deployment.ipynb\",\n",
|
||||
" },\n",
|
||||
" )\n",
|
||||
" return model, endpoint\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"models[\"vllm_tpu\"], endpoints[\"vllm_tpu\"] = deploy_model_vllm_tpu(\n",
|
||||
" model_name=common_util.get_job_name_with_datetime(prefix=\"llama3-3-serve\"),\n",
|
||||
" model_id=model_id,\n",
|
||||
" publisher=\"meta\",\n",
|
||||
" publisher_model_id=\"llama3-3\",\n",
|
||||
" base_model_id=hf_model_id,\n",
|
||||
" tensor_parallel_size=tensor_parallel_size,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" max_model_len=max_model_len,\n",
|
||||
" max_num_seqs=max_num_seqs,\n",
|
||||
" max_num_batched_tokens=max_num_batched_tokens,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "rDHsCOqvFYBi"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Raw predict\n",
|
||||
"\n",
|
||||
"# @markdown Once deployment succeeds, you can send requests to the endpoint with text prompts. Sampling parameters supported by vLLM can be found [here](https://docs.vllm.ai/en/latest/dev/sampling_params.html).\n",
|
||||
"\n",
|
||||
"# @markdown Example:\n",
|
||||
"\n",
|
||||
"# @markdown ```\n",
|
||||
"# @markdown Human: What is a car?\n",
|
||||
"# @markdown Assistant: A car, or a motor car, is a road-connected human-transportation system used to move people or goods from one place to another. The term also encompasses a wide range of vehicles, including motorboats, trains, and aircrafts. Cars typically have four wheels, a cabin for passengers, and an engine or motor. They have been around since the early 19th century and are now one of the most popular forms of transportation, used for daily commuting, shopping, and other purposes.\n",
|
||||
"# @markdown ```\n",
|
||||
"# @markdown Additionally, you can moderate the generated text with Vertex AI. See [Moderate text documentation](https://cloud.google.com/natural-language/docs/moderating-text) for more details.\n",
|
||||
"\n",
|
||||
"# Loads an existing endpoint instance using the endpoint name:\n",
|
||||
"# - Using `endpoint_name = endpoint.name` allows us to get the\n",
|
||||
"# endpoint name of the endpoint `endpoint` created in the cell\n",
|
||||
"# above.\n",
|
||||
"# - Alternatively, you can set `endpoint_name = \"1234567890123456789\"` to load\n",
|
||||
"# an existing endpoint with the ID 1234567890123456789.\n",
|
||||
"# You may uncomment the code below to load an existing endpoint.\n",
|
||||
"\n",
|
||||
"# endpoint_name = \"\" # @param {type:\"string\"}\n",
|
||||
"# aip_endpoint_name = (\n",
|
||||
"# f\"projects/{PROJECT_ID}/locations/{REGION}/endpoints/{endpoint_name}\"\n",
|
||||
"# )\n",
|
||||
"# endpoint = aiplatform.Endpoint(aip_endpoint_name)\n",
|
||||
"\n",
|
||||
"prompt = \"What is a car?\" # @param {type: \"string\"}\n",
|
||||
"# @markdown If you encounter an issue like `ServiceUnavailable: 503 Took too long to respond when processing`, you can reduce the maximum number of output tokens, by lowering `max_tokens`.\n",
|
||||
"max_tokens = 50 # @param {type:\"integer\"}\n",
|
||||
"temperature = 1.0 # @param {type:\"number\"}\n",
|
||||
"top_p = 1.0 # @param {type:\"number\"}\n",
|
||||
"top_k = 1 # @param {type:\"integer\"}\n",
|
||||
"# @markdown Set `raw_response` to `True` to obtain the raw model output. Set `raw_response` to `False` to apply additional formatting in the structure of `\"Prompt:\\n{prompt.strip()}\\nOutput:\\n{output}\"`.\n",
|
||||
"raw_response = False # @param {type:\"boolean\"}\n",
|
||||
"\n",
|
||||
"# Overrides parameters for inferences.\n",
|
||||
"instances = [\n",
|
||||
" {\n",
|
||||
" \"prompt\": prompt,\n",
|
||||
" \"max_tokens\": max_tokens,\n",
|
||||
" \"temperature\": temperature,\n",
|
||||
" \"top_p\": top_p,\n",
|
||||
" \"top_k\": top_k,\n",
|
||||
" \"raw_response\": raw_response,\n",
|
||||
" },\n",
|
||||
"]\n",
|
||||
"response = endpoints[\"vllm_tpu\"].predict(\n",
|
||||
" instances=instances, use_dedicated_endpoint=use_dedicated_endpoint\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"for prediction in response.predictions:\n",
|
||||
" print(prediction)\n",
|
||||
"\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "LSG9ITWTbTb7"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Chat completion\n",
|
||||
"\n",
|
||||
"if use_dedicated_endpoint:\n",
|
||||
" DEDICATED_ENDPOINT_DNS = endpoints[\"vllm_tpu\"].gca_resource.dedicated_endpoint_dns\n",
|
||||
"ENDPOINT_RESOURCE_NAME = endpoints[\"vllm_tpu\"].resource_name\n",
|
||||
"\n",
|
||||
"# @title Chat Completions Inference\n",
|
||||
"\n",
|
||||
"# @markdown Once deployment succeeds, you can send requests to the endpoint using the OpenAI SDK.\n",
|
||||
"\n",
|
||||
"# @markdown First you will need to install the SDK and some auth-related dependencies.\n",
|
||||
"\n",
|
||||
"! pip install -qU openai google-auth requests\n",
|
||||
"\n",
|
||||
"# @markdown Next fill out some request parameters:\n",
|
||||
"\n",
|
||||
"user_message = \"How is your day going?\" # @param {type: \"string\"}\n",
|
||||
"# @markdown If you encounter the issue like `ServiceUnavailable: 503 Took too long to respond when processing`, you can reduce the maximum number of output tokens, such as set `max_tokens` as 20.\n",
|
||||
"max_tokens = 50 # @param {type: \"integer\"}\n",
|
||||
"temperature = 1.0 # @param {type: \"number\"}\n",
|
||||
"stream = False # @param {type: \"boolean\"}\n",
|
||||
"\n",
|
||||
"# @markdown Now we can send a request.\n",
|
||||
"\n",
|
||||
"import google.auth\n",
|
||||
"import openai\n",
|
||||
"\n",
|
||||
"creds, project = google.auth.default()\n",
|
||||
"auth_req = google.auth.transport.requests.Request()\n",
|
||||
"creds.refresh(auth_req)\n",
|
||||
"\n",
|
||||
"BASE_URL = (\n",
|
||||
" f\"https://{REGION}-aiplatform.googleapis.com/v1beta1/{ENDPOINT_RESOURCE_NAME}\"\n",
|
||||
")\n",
|
||||
"try:\n",
|
||||
" if use_dedicated_endpoint:\n",
|
||||
" BASE_URL = f\"https://{DEDICATED_ENDPOINT_DNS}/v1beta1/{ENDPOINT_RESOURCE_NAME}\"\n",
|
||||
"except NameError:\n",
|
||||
" pass\n",
|
||||
"\n",
|
||||
"client = openai.OpenAI(base_url=BASE_URL, api_key=creds.token)\n",
|
||||
"\n",
|
||||
"model_response = client.chat.completions.create(\n",
|
||||
" model=\"\",\n",
|
||||
" messages=[{\"role\": \"user\", \"content\": user_message}],\n",
|
||||
" temperature=temperature,\n",
|
||||
" max_tokens=max_tokens,\n",
|
||||
" stream=stream,\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"if stream:\n",
|
||||
" usage = None\n",
|
||||
" contents = []\n",
|
||||
" for chunk in model_response:\n",
|
||||
" if chunk.usage is not None:\n",
|
||||
" usage = chunk.usage\n",
|
||||
" continue\n",
|
||||
" print(chunk.choices[0].delta.content, end=\"\")\n",
|
||||
" contents.append(chunk.choices[0].delta.content)\n",
|
||||
" print(f\"\\n\\n{usage}\")\n",
|
||||
"else:\n",
|
||||
" print(model_response)\n",
|
||||
"\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "tqtxJakIapIg"
|
||||
},
|
||||
"source": [
|
||||
"## Clean up resources"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "kzgEmmd0aiUM"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Delete the models and endpoints\n",
|
||||
"\n",
|
||||
"# @markdown Delete the experiment models and endpoints to recycle the resources\n",
|
||||
"# @markdown and avoid unnecessary continuous charges that may incur.\n",
|
||||
"\n",
|
||||
"# Undeploy model and delete endpoint.\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)\n",
|
||||
"\n",
|
||||
"# Delete models.\n",
|
||||
"for model in models.values():\n",
|
||||
" model.delete()"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "model_garden_pytorch_llama3_3_tpu7x_deployment.ipynb",
|
||||
"toc_visible": true
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
@@ -105,7 +105,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -108,7 +108,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -165,14 +165,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -329,6 +334,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -338,7 +355,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -362,16 +379,35 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20250417_0916_RC01\",\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/sglang-serve.cu124.0-4.ubuntu2204.py310:model-garden.sglang-0-4-release_20250831.00_p0\",\n",
|
||||
" machine_type=\"a3-highgpu-8g\",\n",
|
||||
" accelerator_type=\"NVIDIA_H100_80GB\",\n",
|
||||
" accelerator_count=8,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -628,7 +664,7 @@
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
@@ -165,14 +165,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -329,6 +334,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -338,7 +355,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -362,7 +379,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20250601_0916_RC01\",\n",
|
||||
@@ -372,6 +389,25 @@
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -464,7 +500,7 @@
|
||||
"# @title Delete the models and endpoints\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
@@ -0,0 +1,529 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "SgQ6t5bqZVlH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Copyright 2025 Google LLC\n",
|
||||
"#\n",
|
||||
"# Licensed under the Apache License, Version 2.0 (the \"License\");\n",
|
||||
"# you may not use this file except in compliance with the License.\n",
|
||||
"# You may obtain a copy of the License at\n",
|
||||
"#\n",
|
||||
"# https://www.apache.org/licenses/LICENSE-2.0\n",
|
||||
"#\n",
|
||||
"# Unless required by applicable law or agreed to in writing, software\n",
|
||||
"# distributed under the License is distributed on an \"AS IS\" BASIS,\n",
|
||||
"# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.\n",
|
||||
"# See the License for the specific language governing permissions and\n",
|
||||
"# limitations under the License."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "99c1c3fc2ca5"
|
||||
},
|
||||
"source": [
|
||||
"# Vertex AI Model Garden - MiniMax-M2 (Deployment)\n",
|
||||
"\n",
|
||||
"<table><tbody><tr>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/notebooks/deploy-notebook?download_url=https://raw.githubusercontent.com/GoogleCloudPlatform/vertex-ai-samples/main/notebooks/community/model_garden/model_garden_pytorch_minimax_m2_deployment.ipynb\">\n",
|
||||
" <img alt=\"Workbench logo\" src=\"https://lh3.googleusercontent.com/UiNooY4LUgW_oTvpsNhPpQzsstV5W8F7rYgxgGBD85cWJoLmrOzhVs_ksK_vgx40SHs7jCqkTkCk=e14-rj-sc0xffffff-h130-w32\" width=\"32px\"><br> Run in Workbench\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/colab/import/https:%2F%2Fraw.githubusercontent.com%2FGoogleCloudPlatform%2Fvertex-ai-samples%2Fmain%2Fnotebooks%2Fcommunity%2Fmodel_garden%2Fmodel_garden_pytorch_minimax_m2_deployment.ipynb\">\n",
|
||||
" <img alt=\"Google Cloud Colab Enterprise logo\" src=\"https://lh3.googleusercontent.com/JmcxdQi-qOpctIvWKgPtrzZdJJK-J3sWE1RsfjZNwshCFgE_9fULcNpuXYTilIR2hjwN\" width=\"32px\"><br> Run in Colab Enterprise\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://github.com/GoogleCloudPlatform/vertex-ai-samples/blob/main/notebooks/community/model_garden/model_garden_pytorch_minimax_m2_deployment.ipynb\">\n",
|
||||
" <img alt=\"GitHub logo\" src=\"https://github.githubassets.com/assets/GitHub-Mark-ea2971cee799.png\" width=\"32px\"><br> View on GitHub\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
"</tr></tbody></table>"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "3de7470326a2"
|
||||
},
|
||||
"source": [
|
||||
"## Overview\n",
|
||||
"\n",
|
||||
"This notebook demonstrates how to deploy a **MiniMax-M2** open model on Google Cloud Vertex AI.\n",
|
||||
"\n",
|
||||
"### Objectives\n",
|
||||
"\n",
|
||||
"- Deploy MiniMax-M2 using containerized backends like [vLLM](https://github.com/vllm-project/vllm) on GPU.\n",
|
||||
"- Use the deployed model to serve chat completion requests for both text and multimodal inputs.\n",
|
||||
"\n",
|
||||
"### File a Bug\n",
|
||||
"\n",
|
||||
"If you encounter issues with this notebook, report them on [GitHub](https://github.com/GoogleCloudPlatform/vertex-ai-samples/issues/new).\n",
|
||||
"\n",
|
||||
"### Costs\n",
|
||||
"\n",
|
||||
"This tutorial uses billable components of Google Cloud:\n",
|
||||
"\n",
|
||||
"- Vertex AI\n",
|
||||
"- Cloud Storage\n",
|
||||
"\n",
|
||||
"Refer to the [Vertex AI pricing](https://cloud.google.com/vertex-ai/pricing) and [Cloud Storage pricing](https://cloud.google.com/storage/pricing) pages for more information. Use the [Pricing Calculator](https://cloud.google.com/products/calculator/) to estimate your projected costs."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "jeYw-Czg-DFy"
|
||||
},
|
||||
"source": [
|
||||
"## Get Started"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "KgyhGvEzBDkj"
|
||||
},
|
||||
"source": [
|
||||
"### Install Vertex AI SDK and other required packages"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "iCacdLqG-IsH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%pip install --upgrade --force-reinstall --quiet 'google-cloud-aiplatform>=1.106.0' 'openai' 'google-auth==2.27.0' 'requests==2.32.3'"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "HUKCrpBy-3yf"
|
||||
},
|
||||
"source": [
|
||||
"### Authenticate the Notebook Environment (Colab only)\n",
|
||||
"\n",
|
||||
"If you're running this notebook in Google Colab, run the following cell to authenticate."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "JXwCT1kn-3Gu"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import sys\n",
|
||||
"\n",
|
||||
"if \"google.colab\" in sys.modules:\n",
|
||||
" from google.colab import auth\n",
|
||||
"\n",
|
||||
" auth.authenticate_user()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "AcW2nwB8-7yC"
|
||||
},
|
||||
"source": [
|
||||
"### Set Google Cloud Project Information\n",
|
||||
"\n",
|
||||
"To get started with Vertex AI, ensure you have an existing Google Cloud project and that the [Vertex AI API is enabled](https://console.cloud.google.com/flows/enableapi?apiid=aiplatform.googleapis.com).\n",
|
||||
"\n",
|
||||
"See the guide on [setting up your project and development environment](https://cloud.google.com/vertex-ai/docs/start/cloud-environment). Also confirm that [billing is enabled](https://cloud.google.com/billing/docs/how-to/modify-project).\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "eIVLp0oE--k-"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Use the environment variable if the user doesn't provide Project ID.\n",
|
||||
"import os\n",
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Q0CXrvcZH_aw"
|
||||
},
|
||||
"source": [
|
||||
"### Import libraries"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "3G2UXB82ICs6"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from vertexai import model_garden"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "upYRiGtP_-iN"
|
||||
},
|
||||
"source": [
|
||||
"## Deploy model"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "H2WC_0hXDVXc"
|
||||
},
|
||||
"source": [
|
||||
"### Choose model variant"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "u41zbNa2EoFq"
|
||||
},
|
||||
"source": [
|
||||
"You can proceed with the default model variant or select a different one."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "-fgC4NLSDkF7"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model_version = \"minimax-m2\" # @param [\"minimax-m2\"] {isTemplate:true}\n",
|
||||
"MODEL_NAME = f\"minimaxai/minimax-m2@{model_version}\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "VRnUgU8LF3_i"
|
||||
},
|
||||
"source": [
|
||||
"To see all deployable model variants available in Model Garden, use:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "-QLd-wshF6sB"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"all_model_versions = model_garden.list_deployable_models(\n",
|
||||
" model_filter=\"minimax-m2\", list_hf_models=False\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "N0UeFHa2GO63"
|
||||
},
|
||||
"source": [
|
||||
"Once you've selected a model variant, initialize it:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "GZiV3trBBcA3"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model = model_garden.OpenModel(MODEL_NAME)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-0cL378wFlvf"
|
||||
},
|
||||
"source": [
|
||||
"### Check the Deployment Configuration\n",
|
||||
"\n",
|
||||
"Use the `list_deploy_options()` method to view the verified deployment configurations for your selected model. This helps ensure you have sufficient resources (e.g., GPU quota) available to deploy it."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "zm73g7vFFm9N"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"deploy_options = model.list_deploy_options(concise=True)\n",
|
||||
"print(deploy_options)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "WjV499VsGwrD"
|
||||
},
|
||||
"source": [
|
||||
"### Deploy the Model\n",
|
||||
"\n",
|
||||
"Now that you’ve reviewed the deployment options, use the `deploy()` method to serve the selected open model to a Vertex AI endpoint. Deployment time may vary depending on the model size and infrastructure requirements.\n",
|
||||
"\n",
|
||||
"> **Note**: If the model requires accepting a license agreement (EULA), set the `accept_eula=True` flag in the deploy call. Set `use_dedicated_endpoint` to False if you don't want to use [dedicated endpoint](https://cloud.google.com/vertex-ai/docs/general/deployment#create-dedicated-endpoint)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "wX1itVTvXdEP"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "MRmPFEPoGzsB"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "PHBtn8DQp-ID"
|
||||
},
|
||||
"source": [
|
||||
"Alternatively, you can select one of the verified deployment configurations listed above."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "ADsJG8JYqI6c"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-sglang-serve:sglang-airlock-20251028-1830\",\n",
|
||||
" machine_type=\"a3-highgpu-8g\",\n",
|
||||
" accelerator_type=\"NVIDIA_H100_80GB\",\n",
|
||||
" accelerator_count=8,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "kqSUK2CwsImi"
|
||||
},
|
||||
"source": [
|
||||
"To further customize your deployment, you can configure:\n",
|
||||
"\n",
|
||||
"- **Compute Resources**: Machine type, replica count (min/max), accelerator type and quantity.\n",
|
||||
"- **Infrastructure**: Use Spot VMs, reservation affinity, or dedicated endpoints.\n",
|
||||
"- **Serving Container**: Customize container image, ports, health checks, and environment variables.\n",
|
||||
"\n",
|
||||
"See the [Model Garden SDK README](https://github.com/googleapis/python-aiplatform/blob/main/vertexai/model_garden/README.md) for advanced configuration options."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "AGVPzwHkn7rw"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Raw predict\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"# @markdown Once deployment succeeds, you can send requests to the endpoint with text prompts. Sampling parameters supported by SGLang can be found [here](https://docs.sglang.ai/backend/sampling_params.html).\n",
|
||||
"\n",
|
||||
"# @markdown Example:\n",
|
||||
"\n",
|
||||
"# @markdown ```\n",
|
||||
"# @markdown Write a quick sort algorithm in Python.\n",
|
||||
"# @markdown ```\n",
|
||||
"# @markdown Additionally, you can moderate the generated text with Vertex AI. See [Moderate text documentation](https://cloud.google.com/natural-language/docs/moderating-text) for more details.\n",
|
||||
"\n",
|
||||
"# Loads an existing endpoint instance using the endpoint name:\n",
|
||||
"# - Using `endpoint_name = endpoint.name` allows us to get the\n",
|
||||
"# endpoint name of the endpoint `endpoint` created in the cell\n",
|
||||
"# above.\n",
|
||||
"# - Alternatively, you can set `endpoint_name = \"1234567890123456789\"` to load\n",
|
||||
"# an existing endpoint with the ID 1234567890123456789.\n",
|
||||
"# You may uncomment the code below to load an existing endpoint.\n",
|
||||
"\n",
|
||||
"# endpoint_name = \"\" # @param {type:\"string\"}\n",
|
||||
"# aip_endpoint_name = (\n",
|
||||
"# f\"projects/{PROJECT_ID}/locations/{REGION}/endpoints/{endpoint_name}\"\n",
|
||||
"# )\n",
|
||||
"# endpoint = aiplatform.Endpoint(aip_endpoint_name)\n",
|
||||
"\n",
|
||||
"prompt = \"Write a quick sort algorithm in Python.\" # @param {type: \"string\"}\n",
|
||||
"\n",
|
||||
"max_new_tokens = 32768 # @param {type:\"integer\"}\n",
|
||||
"temperature = 0.7 # @param {type:\"number\"}\n",
|
||||
"top_p = 0.8 # @param {type:\"number\"}\n",
|
||||
"top_k = 20 # @param {type:\"number\"}\n",
|
||||
"\n",
|
||||
"# Overrides parameters for inferences.\n",
|
||||
"instances = [{\"text\": prompt}]\n",
|
||||
"parameters = {\n",
|
||||
" \"sampling_params\": {\n",
|
||||
" \"max_new_tokens\": max_new_tokens,\n",
|
||||
" \"temperature\": temperature,\n",
|
||||
" \"top_p\": top_p,\n",
|
||||
" \"top_k\": top_k,\n",
|
||||
" }\n",
|
||||
"}\n",
|
||||
"response = endpoints[LABEL].predict(\n",
|
||||
" instances=instances,\n",
|
||||
" parameters=parameters,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"for prediction in response.predictions:\n",
|
||||
" print(prediction)\n",
|
||||
"\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "JETd33jIDcjm"
|
||||
},
|
||||
"source": [
|
||||
"## Clean up resources"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "911406c1561e"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Delete the endpoints\n",
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "model_garden_pytorch_minimax_m2_deployment.ipynb",
|
||||
"toc_visible": true
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
@@ -114,7 +114,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -97,7 +97,7 @@
|
||||
"# @title Install Python Packages for Finetuning\n",
|
||||
"\n",
|
||||
"# @markdown 1. Install google-cloud-aiplatform package and restart the session if instructed.\n",
|
||||
"! pip install --upgrade --quiet 'google-cloud-aiplatform>=1.66.0'\n",
|
||||
"! pip install --upgrade --quiet google-cloud-aiplatform==1.130.0\n",
|
||||
"\n",
|
||||
"# @markdown 2. Install packages to validate dataset with template.\n",
|
||||
"! pip install --upgrade --quiet gcsfs==2024.3.1\n",
|
||||
@@ -681,6 +681,7 @@
|
||||
" max_num_seqs: int = 256,\n",
|
||||
" model_type: str = None,\n",
|
||||
" enable_llama_tool_parser: bool = False,\n",
|
||||
" is_spot: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys trained models with vLLM into Vertex AI.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
@@ -775,6 +776,7 @@
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" service_account=service_account,\n",
|
||||
" spot=is_spot,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_pytorch_mistral_peft_tuning.ipynb\",\n",
|
||||
" \"NOTEBOOK_ENVIRONMENT\": get_deploy_source(),\n",
|
||||
|
||||
@@ -120,7 +120,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -97,7 +97,7 @@
|
||||
"# @title Install Python Packages for Finetuning\n",
|
||||
"\n",
|
||||
"# @markdown 1. Install google-cloud-aiplatform package and restart the session if instructed.\n",
|
||||
"! pip install --upgrade --quiet 'google-cloud-aiplatform>=1.66.0'\n",
|
||||
"! pip install --upgrade --quiet google-cloud-aiplatform==1.130.0\n",
|
||||
"\n",
|
||||
"# @markdown 2. Install packages to validate dataset with template.\n",
|
||||
"! pip install --upgrade --quiet gcsfs==2024.3.1\n",
|
||||
@@ -686,6 +686,7 @@
|
||||
" max_num_seqs: int = 256,\n",
|
||||
" model_type: str = None,\n",
|
||||
" enable_llama_tool_parser: bool = False,\n",
|
||||
" is_spot: bool = False,\n",
|
||||
") -> Tuple[aiplatform.Model, aiplatform.Endpoint]:\n",
|
||||
" \"\"\"Deploys trained models with vLLM into Vertex AI.\"\"\"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
@@ -780,6 +781,7 @@
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" service_account=service_account,\n",
|
||||
" spot=is_spot,\n",
|
||||
" system_labels={\n",
|
||||
" \"NOTEBOOK_NAME\": \"model_garden_pytorch_mixtral_peft_tuning.ipynb\",\n",
|
||||
" \"NOTEBOOK_ENVIRONMENT\": get_deploy_source(),\n",
|
||||
|
||||
@@ -111,7 +111,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -116,7 +116,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -109,7 +109,7 @@
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -535,7 +535,6 @@
|
||||
"# )\n",
|
||||
"# endpoint = aiplatform.Endpoint(aip_endpoint_name)\n",
|
||||
"\n",
|
||||
"# @markdown A chat template formatted prompt for Gemma 3n is shown below as an example.\n",
|
||||
"prompt = \"Write a quick sort algorithm in Python.\" # @param {type: \"string\"}\n",
|
||||
"\n",
|
||||
"max_new_tokens = 32768 # @param {type:\"integer\"}\n",
|
||||
|
||||
@@ -165,14 +165,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -329,6 +334,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -338,7 +355,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -362,7 +379,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/sglang-serve.cu124.0-4.ubuntu2204.py310:20250428-1803-rc0\",\n",
|
||||
@@ -372,6 +389,25 @@
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -572,7 +608,7 @@
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
@@ -0,0 +1,540 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "CQD4DkP9HSIa"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Copyright 2025 Google LLC\n",
|
||||
"#\n",
|
||||
"# Licensed under the Apache License, Version 2.0 (the \"License\");\n",
|
||||
"# you may not use this file except in compliance with the License.\n",
|
||||
"# You may obtain a copy of the License at\n",
|
||||
"#\n",
|
||||
"# https://www.apache.org/licenses/LICENSE-2.0\n",
|
||||
"#\n",
|
||||
"# Unless required by applicable law or agreed to in writing, software\n",
|
||||
"# distributed under the License is distributed on an \"AS IS\" BASIS,\n",
|
||||
"# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.\n",
|
||||
"# See the License for the specific language governing permissions and\n",
|
||||
"# limitations under the License."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "2cMvhZ59EBXR"
|
||||
},
|
||||
"source": [
|
||||
"# Vertex AI Model Garden - Qwen3-VL (Deployment)\n",
|
||||
"\n",
|
||||
"<table><tbody><tr>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/notebooks/deploy-notebook?download_url=https://raw.githubusercontent.com/GoogleCloudPlatform/vertex-ai-samples/main/notebooks/community/model_garden/model_garden_pytorch_qwen3_vl.ipynb\">\n",
|
||||
" <img alt=\"Workbench logo\" src=\"https://lh3.googleusercontent.com/UiNooY4LUgW_oTvpsNhPpQzsstV5W8F7rYgxgGBD85cWJoLmrOzhVs_ksK_vgx40SHs7jCqkTkCk=e14-rj-sc0xffffff-h130-w32\" width=\"32px\"><br> Run in Workbench\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/colab/import/https:%2F%2Fraw.githubusercontent.com%2FGoogleCloudPlatform%2Fvertex-ai-samples%2Fmain%2Fnotebooks%2Fcommunity%2Fmodel_garden%2Fmodel_garden_pytorch_qwen3_vl.ipynb\">\n",
|
||||
" <img alt=\"Google Cloud Colab Enterprise logo\" src=\"https://lh3.googleusercontent.com/JmcxdQi-qOpctIvWKgPtrzZdJJK-J3sWE1RsfjZNwshCFgE_9fULcNpuXYTilIR2hjwN\" width=\"32px\"><br> Run in Colab Enterprise\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://github.com/GoogleCloudPlatform/vertex-ai-samples/blob/main/notebooks/community/model_garden/model_garden_pytorch_qwen3_vl.ipynb\">\n",
|
||||
" <img alt=\"GitHub logo\" src=\"https://github.githubassets.com/assets/GitHub-Mark-ea2971cee799.png\" width=\"32px\"><br> View on GitHub\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
"</tr></tbody></table>"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "3de7470326a2"
|
||||
},
|
||||
"source": [
|
||||
"## Overview\n",
|
||||
"\n",
|
||||
"This notebook demonstrates how to deploy a **Qwen 3-Vl** open model on Google Cloud Vertex AI.\n",
|
||||
"\n",
|
||||
"### Objectives\n",
|
||||
"\n",
|
||||
"- Deploy Qwen 3-Vl using containerized backends like [vLLM](https://github.com/vllm-project/vllm) on GPU.\n",
|
||||
"- Use the deployed model to serve chat completion requests for both text and multimodal inputs.\n",
|
||||
"\n",
|
||||
"### File a Bug\n",
|
||||
"\n",
|
||||
"If you encounter issues with this notebook, report them on [GitHub](https://github.com/GoogleCloudPlatform/vertex-ai-samples/issues/new).\n",
|
||||
"\n",
|
||||
"### Costs\n",
|
||||
"\n",
|
||||
"This tutorial uses billable components of Google Cloud:\n",
|
||||
"\n",
|
||||
"- Vertex AI\n",
|
||||
"- Cloud Storage\n",
|
||||
"\n",
|
||||
"Refer to the [Vertex AI pricing](https://cloud.google.com/vertex-ai/pricing) and [Cloud Storage pricing](https://cloud.google.com/storage/pricing) pages for more information. Use the [Pricing Calculator](https://cloud.google.com/products/calculator/) to estimate your projected costs."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "jeYw-Czg-DFy"
|
||||
},
|
||||
"source": [
|
||||
"## Get Started"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "KgyhGvEzBDkj"
|
||||
},
|
||||
"source": [
|
||||
"### Install Vertex AI SDK and other required packages"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "iCacdLqG-IsH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"%pip install --upgrade --force-reinstall --quiet 'google-cloud-aiplatform>=1.106.0' 'openai' 'google-auth==2.27.0' 'requests==2.32.3'"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "HUKCrpBy-3yf"
|
||||
},
|
||||
"source": [
|
||||
"### Authenticate the Notebook Environment (Colab only)\n",
|
||||
"\n",
|
||||
"If you're running this notebook in Google Colab, run the following cell to authenticate."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "JXwCT1kn-3Gu"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"import sys\n",
|
||||
"\n",
|
||||
"if \"google.colab\" in sys.modules:\n",
|
||||
" from google.colab import auth\n",
|
||||
"\n",
|
||||
" auth.authenticate_user()"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "AcW2nwB8-7yC"
|
||||
},
|
||||
"source": [
|
||||
"### Set Google Cloud Project Information\n",
|
||||
"\n",
|
||||
"To get started with Vertex AI, ensure you have an existing Google Cloud project and that the [Vertex AI API is enabled](https://console.cloud.google.com/flows/enableapi?apiid=aiplatform.googleapis.com).\n",
|
||||
"\n",
|
||||
"See the guide on [setting up your project and development environment](https://cloud.google.com/vertex-ai/docs/start/cloud-environment). Also confirm that [billing is enabled](https://cloud.google.com/billing/docs/how-to/modify-project).\n"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "eIVLp0oE--k-"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Use the environment variable if the user doesn't provide Project ID.\n",
|
||||
"import os\n",
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "Q0CXrvcZH_aw"
|
||||
},
|
||||
"source": [
|
||||
"### Import libraries"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "3G2UXB82ICs6"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"from vertexai import model_garden"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "upYRiGtP_-iN"
|
||||
},
|
||||
"source": [
|
||||
"## Deploy model"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "H2WC_0hXDVXc"
|
||||
},
|
||||
"source": [
|
||||
"### Choose model variant"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "u41zbNa2EoFq"
|
||||
},
|
||||
"source": [
|
||||
"You can proceed with the default model variant or select a different one."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "-fgC4NLSDkF7"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model_version = \"qwen3-vl-8b-instruct\" # @param [\"qwen3-vl-235b-a22b-instruct\", \"qwen3-vl-235b-a22b-instruct-fp8\", \"qwen3-vl-235b-a22b-thinking\", \"qwen3-vl-235b-a22b-thinking-fp8\", \"qwen3-vl-2b-instruct\", \"qwen3-vl-2b-instruct-fp8\", \"qwen3-vl-2b-thinking\", \"qwen3-vl-2b-thinking-fp8\", \"qwen3-vl-30b-a3b-instruct\", \"qwen3-vl-30b-a3b-instruct-fp8\", \"qwen3-vl-30b-a3b-thinking\", \"qwen3-vl-30b-a3b-thinking-fp8\", \"qwen3-vl-32b-instruct\", \"qwen3-vl-32b-instruct-fp8\", \"qwen3-vl-32b-thinking\", \"qwen3-vl-32b-thinking-fp8\", \"qwen3-vl-4b-instruct\", \"qwen3-vl-4b-instruct-fp8\", \"qwen3-vl-4b-thinking\", \"qwen3-vl-4b-thinking-fp8\", \"qwen3-vl-8b-instruct\", \"qwen3-vl-8b-instruct-fp8\", \"qwen3-vl-8b-thinking\", \"qwen3-vl-8b-thinking-fp8\"] {isTemplate:true}\n",
|
||||
"MODEL_NAME = f\"qwen/qwen3-vl@{model_version}\""
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "VRnUgU8LF3_i"
|
||||
},
|
||||
"source": [
|
||||
"To see all deployable model variants available in Model Garden, use:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "-QLd-wshF6sB"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"all_model_versions = model_garden.list_deployable_models(\n",
|
||||
" model_filter=\"qwen3-vl\", list_hf_models=False\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "N0UeFHa2GO63"
|
||||
},
|
||||
"source": [
|
||||
"Once you've selected a model variant, initialize it:"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "GZiV3trBBcA3"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"model = model_garden.OpenModel(MODEL_NAME)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-0cL378wFlvf"
|
||||
},
|
||||
"source": [
|
||||
"### Check the Deployment Configuration\n",
|
||||
"\n",
|
||||
"Use the `list_deploy_options()` method to view the verified deployment configurations for your selected model. This helps ensure you have sufficient resources (e.g., GPU quota) available to deploy it."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "zm73g7vFFm9N"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"deploy_options = model.list_deploy_options(concise=True)\n",
|
||||
"print(deploy_options)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "WjV499VsGwrD"
|
||||
},
|
||||
"source": [
|
||||
"### Deploy the Model\n",
|
||||
"\n",
|
||||
"Now that you’ve reviewed the deployment options, use the `deploy()` method to serve the selected open model to a Vertex AI endpoint. Deployment time may vary depending on the model size and infrastructure requirements.\n",
|
||||
"\n",
|
||||
"> **Note**: If the model requires accepting a license agreement (EULA), set the `accept_eula=True` flag in the deploy call. Set `use_dedicated_endpoint` to False if you don't want to use [dedicated endpoint](https://cloud.google.com/vertex-ai/docs/general/deployment#create-dedicated-endpoint)."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "wX1itVTvXdEP"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "MRmPFEPoGzsB"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "PHBtn8DQp-ID"
|
||||
},
|
||||
"source": [
|
||||
"Alternatively, you can select one of the verified deployment configurations listed above."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "ADsJG8JYqI6c"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20251003_0916_RC01\",\n",
|
||||
" machine_type=\"a3-highgpu-1g\",\n",
|
||||
" accelerator_type=\"NVIDIA_H100_80GB\",\n",
|
||||
" accelerator_count=1,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "kqSUK2CwsImi"
|
||||
},
|
||||
"source": [
|
||||
"To further customize your deployment, you can configure:\n",
|
||||
"\n",
|
||||
"- **Compute Resources**: Machine type, replica count (min/max), accelerator type and quantity.\n",
|
||||
"- **Infrastructure**: Use Spot VMs, reservation affinity, or dedicated endpoints.\n",
|
||||
"- **Serving Container**: Customize container image, ports, health checks, and environment variables.\n",
|
||||
"\n",
|
||||
"See the [Model Garden SDK README](https://github.com/googleapis/python-aiplatform/blob/main/vertexai/model_garden/README.md) for advanced configuration options."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "scQowXXcD8Fe"
|
||||
},
|
||||
"source": [
|
||||
"## Inference"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "nM50G3PYHtKG"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Inference\n",
|
||||
"if use_dedicated_endpoint:\n",
|
||||
" DEDICATED_ENDPOINT_DNS = endpoint.gca_resource.dedicated_endpoint_dns\n",
|
||||
"ENDPOINT_RESOURCE_NAME = endpoint.resource_name\n",
|
||||
"\n",
|
||||
"# @markdown Because the Qwen3 models generate detailed reasoning steps, the output is expected to be long. We recommend using streaming for a better generation experience.\n",
|
||||
"\n",
|
||||
"# @title Inference\n",
|
||||
"\n",
|
||||
"# @markdown Once deployment succeeds, you can send requests to the endpoint using the OpenAI SDK.\n",
|
||||
"\n",
|
||||
"# @markdown First you will need to install the SDK and some auth-related dependencies.\n",
|
||||
"\n",
|
||||
"! pip install -qU openai google-auth requests\n",
|
||||
"\n",
|
||||
"# @markdown Next fill out some request parameters:\n",
|
||||
"\n",
|
||||
"user_image = \"https://dashscope.oss-cn-beijing.aliyuncs.com/images/dog_and_girl.jpeg\" # @param {type: \"string\"}\n",
|
||||
"user_video = \"https://ofasys-multimodal-wlcb-3.oss-cn-wulanchabu.aliyuncs.com/sibo.ssb/datasets/cookbook/ead2e3f0e7f836c9ec51236befdaf2d843ac13a6.mp4\" # @param {type: \"string\"}\n",
|
||||
"user_message = \"Could you describe the provided image and video?\" # @param {type: \"string\"}\n",
|
||||
"# @markdown If you encounter the issue like `ServiceUnavailable: 503 Took too long to respond when processing`, you can reduce the maximum number of output tokens, such as set `max_tokens` as 20.\n",
|
||||
"max_tokens = 50 # @param {type: \"integer\"}\n",
|
||||
"temperature = 0.7 # @param {type: \"number\"}\n",
|
||||
"top_p = 0.95 # @param {type: \"number\"}\n",
|
||||
"\n",
|
||||
"# @markdown Now we can send a request.\n",
|
||||
"\n",
|
||||
"import google.auth\n",
|
||||
"import openai\n",
|
||||
"\n",
|
||||
"creds, project = google.auth.default()\n",
|
||||
"auth_req = google.auth.transport.requests.Request()\n",
|
||||
"creds.refresh(auth_req)\n",
|
||||
"\n",
|
||||
"BASE_URL = (\n",
|
||||
" f\"https://{REGION}-aiplatform.googleapis.com/v1beta1/{ENDPOINT_RESOURCE_NAME}\"\n",
|
||||
")\n",
|
||||
"try:\n",
|
||||
" if use_dedicated_endpoint:\n",
|
||||
" BASE_URL = f\"https://{DEDICATED_ENDPOINT_DNS}/v1beta1/{ENDPOINT_RESOURCE_NAME}\"\n",
|
||||
"except NameError:\n",
|
||||
" pass\n",
|
||||
"\n",
|
||||
"client = openai.OpenAI(base_url=BASE_URL, api_key=creds.token)\n",
|
||||
"\n",
|
||||
"model_response = client.chat.completions.create(\n",
|
||||
" model=\"\",\n",
|
||||
" messages=[\n",
|
||||
" {\n",
|
||||
" \"role\": \"user\",\n",
|
||||
" \"content\": [\n",
|
||||
" {\"type\": \"image_url\", \"image_url\": {\"url\": user_image}},\n",
|
||||
" {\"type\": \"video_url\", \"video_url\": {\"url\": user_video}},\n",
|
||||
" {\"type\": \"text\", \"text\": user_message},\n",
|
||||
" ],\n",
|
||||
" }\n",
|
||||
" ],\n",
|
||||
" temperature=temperature,\n",
|
||||
" max_tokens=max_tokens,\n",
|
||||
" top_p=top_p,\n",
|
||||
")\n",
|
||||
"print(model_response)\n",
|
||||
"\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "yVpBnB1aHvjQ"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Delete the endpoints\n",
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "model_garden_pytorch_qwen3_vl.ipynb",
|
||||
"toc_visible": true
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
@@ -0,0 +1,429 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "kZch0mUbRtjv"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Copyright 2025 Google LLC\n",
|
||||
"#\n",
|
||||
"# Licensed under the Apache License, Version 2.0 (the \"License\");\n",
|
||||
"# you may not use this file except in compliance with the License.\n",
|
||||
"# You may obtain a copy of the License at\n",
|
||||
"#\n",
|
||||
"# https://www.apache.org/licenses/LICENSE-2.0\n",
|
||||
"#\n",
|
||||
"# Unless required by applicable law or agreed to in writing, software\n",
|
||||
"# distributed under the License is distributed on an \"AS IS\" BASIS,\n",
|
||||
"# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.\n",
|
||||
"# See the License for the specific language governing permissions and\n",
|
||||
"# limitations under the License."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "r-0nTGMwR0OO"
|
||||
},
|
||||
"source": [
|
||||
"# Vertex AI Model Garden - Qwen Image & Qwen Image Edit\n",
|
||||
"\n",
|
||||
"<table><tbody><tr>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/notebooks/deploy-notebook?download_url=https://raw.githubusercontent.com/GoogleCloudPlatform/vertex-ai-samples/main/notebooks/community/model_garden/model_garden_pytorch_qwen_image.ipynb\">\n",
|
||||
" <img alt=\"Workbench logo\" src=\"https://lh3.googleusercontent.com/UiNooY4LUgW_oTvpsNhPpQzsstV5W8F7rYgxgGBD85cWJoLmrOzhVs_ksK_vgx40SHs7jCqkTkCk=e14-rj-sc0xffffff-h130-w32\" width=\"32px\"><br> Run in Workbench\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://console.cloud.google.com/vertex-ai/colab/import/https:%2F%2Fraw.githubusercontent.com%2FGoogleCloudPlatform%2Fvertex-ai-samples%2Fmain%2Fnotebooks%2Fcommunity%2Fmodel_garden%2Fmodel_garden_pytorch_qwen_image.ipynb\">\n",
|
||||
" <img alt=\"Google Cloud Colab Enterprise logo\" src=\"https://lh3.googleusercontent.com/JmcxdQi-qOpctIvWKgPtrzZdJJK-J3sWE1RsfjZNwshCFgE_9fULcNpuXYTilIR2hjwN\" width=\"32px\"><br> Run in Colab Enterprise\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
" <td style=\"text-align: center\">\n",
|
||||
" <a href=\"https://github.com/GoogleCloudPlatform/vertex-ai-samples/blob/main/notebooks/community/model_garden/model_garden_pytorch_qwen_image.ipynb\">\n",
|
||||
" <img alt=\"GitHub logo\" src=\"https://github.githubassets.com/assets/GitHub-Mark-ea2971cee799.png\" width=\"32px\"><br> View on GitHub\n",
|
||||
" </a>\n",
|
||||
" </td>\n",
|
||||
"</tr></tbody></table>"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "8lvZLpjASKex"
|
||||
},
|
||||
"source": [
|
||||
"## Overview\n",
|
||||
"\n",
|
||||
"This notebook demonstrates deploying the [Qwen Image](https://huggingface.co/Qwen/Qwen-Image) & [Qwen Image Edit](https://huggingface.co/Qwen/Qwen-Image-Edit) models on Vertex AI for online prediction.\n",
|
||||
"\n",
|
||||
"### Objective\n",
|
||||
"\n",
|
||||
"- Upload the model to [Model Registry](https://cloud.google.com/vertex-ai/docs/model-registry/introduction).\n",
|
||||
"- Deploy the model on [Endpoint](https://cloud.google.com/vertex-ai/docs/predictions/using-private-endpoints).\n",
|
||||
"- Run online predictions for text to image inference. \n",
|
||||
"- Run online predictions for text-guided image editing.\n",
|
||||
"\n",
|
||||
"### File a bug\n",
|
||||
"\n",
|
||||
"File a bug on [GitHub](https://github.com/GoogleCloudPlatform/vertex-ai-samples/issues/new) if you encounter any issue with the notebook.\n",
|
||||
"\n",
|
||||
"### Costs\n",
|
||||
"\n",
|
||||
"This tutorial uses billable components of Google Cloud:\n",
|
||||
"\n",
|
||||
"* Vertex AI\n",
|
||||
"* Cloud Storage\n",
|
||||
"\n",
|
||||
"Learn about [Vertex AI pricing](https://cloud.google.com/vertex-ai/pricing), [Cloud Storage pricing](https://cloud.google.com/storage/pricing), and use the [Pricing Calculator](https://cloud.google.com/products/calculator/) to generate a cost estimate based on your projected usage."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "-bowEEa8SiB9"
|
||||
},
|
||||
"source": [
|
||||
"## Run the notebook"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "ZW-t_FaiSjpO"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Setup Google Cloud project\n",
|
||||
"\n",
|
||||
"# @markdown 1. [Make sure that billing is enabled for your project](https://cloud.google.com/billing/docs/how-to/modify-project).\n",
|
||||
"\n",
|
||||
"# @markdown 2. **[Optional]** Set region. If not set, the region will be set automatically according to Colab Enterprise environment.\n",
|
||||
"\n",
|
||||
"REGION = \"\" # @param {type:\"string\"}\n",
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
"# @markdown | a3-highgpu-4g | 4 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
"# @markdown | a3-highgpu-8g | 8 NVIDIA_H100_80GB | us-central1, europe-west4, us-west1, asia-southeast1 |\n",
|
||||
"\n",
|
||||
"# Upgrade Vertex AI SDK.\n",
|
||||
"! pip3 install --upgrade --quiet 'google-cloud-aiplatform==1.103.0'\n",
|
||||
"! git clone https://github.com/GoogleCloudPlatform/vertex-ai-samples.git\n",
|
||||
"\n",
|
||||
"# Import the necessary packages\n",
|
||||
"import importlib\n",
|
||||
"import os\n",
|
||||
"\n",
|
||||
"from google.cloud import aiplatform\n",
|
||||
"\n",
|
||||
"if os.environ.get(\"VERTEX_PRODUCT\") != \"COLAB_ENTERPRISE\":\n",
|
||||
" ! pip install --upgrade tensorflow\n",
|
||||
"! git clone https://github.com/GoogleCloudPlatform/vertex-ai-samples.git\n",
|
||||
"\n",
|
||||
"common_util = importlib.import_module(\n",
|
||||
" \"vertex-ai-samples.notebooks.community.model_garden.docker_source_codes.notebook_util.common_util\"\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"LABEL = \"diffusers_gpu\"\n",
|
||||
"models, endpoints = {}, {}\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"# Get the default cloud project id.\n",
|
||||
"PROJECT_ID = os.environ[\"GOOGLE_CLOUD_PROJECT\"]\n",
|
||||
"\n",
|
||||
"# Get the default region for launching jobs.\n",
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ[\"GOOGLE_CLOUD_REGION\"]\n",
|
||||
"\n",
|
||||
"# Initialize Vertex AI API.\n",
|
||||
"print(\"Initializing Vertex AI API.\")\n",
|
||||
"aiplatform.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"! gcloud config set project $PROJECT_ID\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"vertexai.init(\n",
|
||||
" project=PROJECT_ID,\n",
|
||||
" location=REGION,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "dWP4cL9YW0Xf"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Set the model parameters\n",
|
||||
"\n",
|
||||
"# @markdown Set the model to deploy.\n",
|
||||
"base_model_name = \"Qwen-Image\" # @param [\"Qwen-Image\", \"Qwen-Image-Edit\", \"Qwen-Image-Edit-2509\"] {isTemplate:true}\n",
|
||||
"model_id = \"Qwen/\" + base_model_name\n",
|
||||
"\n",
|
||||
"task = \"text-to-image-qwen\"\n",
|
||||
"if base_model_name == \"Qwen-Image-Edit\":\n",
|
||||
" task = \"image-edit-qwen\"\n",
|
||||
"elif base_model_name == \"Qwen-Image-Edit-2509\":\n",
|
||||
" task = \"image-edit-qwen-2509\"\n",
|
||||
"\n",
|
||||
"# @markdown Choose whether to use a [Spot VM](https://cloud.google.com/compute/docs/instances/spot) for the deployment.\n",
|
||||
"is_spot = False # @param {type:\"boolean\"}\n",
|
||||
"\n",
|
||||
"# @markdown Set use_dedicated_endpoint to False if you don't want to use [dedicated endpoint](https://cloud.google.com/vertex-ai/docs/general/deployment#create-dedicated-endpoint). Note that [dedicated endpoint does not support VPC Service Controls](https://cloud.google.com/vertex-ai/docs/predictions/choose-endpoint-type), uncheck the box if you are using VPC-SC.\n",
|
||||
"use_dedicated_endpoint = True # @param {type:\"boolean\"}\n",
|
||||
"\n",
|
||||
"# @markdown Find Vertex AI prediction supported accelerators and regions at https://cloud.google.com/vertex-ai/docs/predictions/configure-compute.\n",
|
||||
"accelerator_type = \"NVIDIA_H100_80GB\" # @param [\"NVIDIA_H100_80GB\", \"NVIDIA_A100_80GB\"] {isTemplate:true}\n",
|
||||
"\n",
|
||||
"PUBLISHER_MODEL_NAME = f\"qwen/qwen-image@{base_model_name.lower()}\"\n",
|
||||
"\n",
|
||||
"if accelerator_type == \"NVIDIA_H100_80GB\":\n",
|
||||
" if is_spot:\n",
|
||||
" resource_id = \"custom_model_serving_preemptible_nvidia_h100_gpus\"\n",
|
||||
" else:\n",
|
||||
" resource_id = \"custom_model_serving_nvidia_h100_gpus\"\n",
|
||||
" if base_model_name in [\"Qwen-Image\", \"Qwen-Image-Edit\", \"Qwen-Image-Edit-2509\"]:\n",
|
||||
" machine_type = \"a3-highgpu-1g\"\n",
|
||||
" accelerator_count = 1\n",
|
||||
" else:\n",
|
||||
" raise ValueError(f\"Recommended GPU setting not found for: {base_model_name}.\")\n",
|
||||
"elif accelerator_type == \"NVIDIA_A100_80GB\":\n",
|
||||
" if is_spot:\n",
|
||||
" resource_id = \"custom_model_serving_preemptible_nvidia_a100_gpus\"\n",
|
||||
" else:\n",
|
||||
" resource_id = \"custom_model_serving_nvidia_a100_gpus\"\n",
|
||||
" if base_model_name in [\"Qwen-Image\", \"Qwen-Image-Edit\", \"Qwen-Image-Edit-2509\"]:\n",
|
||||
" machine_type = \"a2-ultragpu-1g\"\n",
|
||||
" accelerator_count = 1\n",
|
||||
" else:\n",
|
||||
" raise ValueError(f\"Recommended GPU setting not found for: {base_model_name}.\")\n",
|
||||
"else:\n",
|
||||
" raise ValueError(f\"Recommended GPU setting not found for: {base_model_name}.\")\n",
|
||||
"\n",
|
||||
"common_util.check_quota(\n",
|
||||
" project_id=PROJECT_ID,\n",
|
||||
" region=REGION,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" is_for_training=False,\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "EDPkgPJObOWl"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title [Option 1] Deploy with Model Garden SDK\n",
|
||||
"# @markdown Deploy with Gen AI model-centric SDK. This section uploads the prebuilt model to Model Registry and deploys it to a Vertex AI Endpoint. It takes 15 minutes to 1 hour to finish depending on the size of the model. See [use open models with Vertex AI](https://cloud.google.com/vertex-ai/generative-ai/docs/open-models/use-open-models) for documentation on other use cases.\n",
|
||||
"deploy_request_timeout = 1800 # 30 minutes\n",
|
||||
"from vertexai import model_garden\n",
|
||||
"\n",
|
||||
"model = model_garden.OpenModel(PUBLISHER_MODEL_NAME)\n",
|
||||
"endpoints[LABEL] = model.deploy(\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" spot=is_spot,\n",
|
||||
" deploy_request_timeout=deploy_request_timeout,\n",
|
||||
" accept_eula=False,\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"endpoint = endpoints[LABEL]\n",
|
||||
"\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "grZJ14Q1bS2t"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title [Option 2] Deploy with customized configs\n",
|
||||
"\n",
|
||||
"# @markdown This section deploys the Qwen Image & Qwen Image Edit variants.\n",
|
||||
"\n",
|
||||
"# @markdown The model deployment step will take ~15 minutes to complete.\n",
|
||||
"\n",
|
||||
"# The pre-built serving docker image. It contains serving scripts and models.\n",
|
||||
"SERVE_DOCKER_URI = \"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/pytorch-inference.cu125.0-4.ubuntu2204.py310\"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def deploy_model(model_id, task, machine_type, accelerator_type, accelerator_count):\n",
|
||||
" \"\"\"Create a Vertex AI Endpoint and deploy the specified model to the endpoint.\"\"\"\n",
|
||||
" common_util.check_quota(\n",
|
||||
" project_id=PROJECT_ID,\n",
|
||||
" region=REGION,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" is_for_training=False,\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" model_name = model_id\n",
|
||||
"\n",
|
||||
" endpoint = aiplatform.Endpoint.create(display_name=f\"{model_name}-endpoint\")\n",
|
||||
" serving_env = {\n",
|
||||
" \"MODEL_ID\": model_id,\n",
|
||||
" \"TASK\": task,\n",
|
||||
" \"DEPLOY_SOURCE\": \"notebook\",\n",
|
||||
" }\n",
|
||||
"\n",
|
||||
" model = aiplatform.Model.upload(\n",
|
||||
" display_name=model_name,\n",
|
||||
" serving_container_image_uri=SERVE_DOCKER_URI,\n",
|
||||
" serving_container_ports=[7080],\n",
|
||||
" serving_container_predict_route=\"/predict\",\n",
|
||||
" serving_container_health_route=\"/health\",\n",
|
||||
" serving_container_environment_variables=serving_env,\n",
|
||||
" model_garden_source_model_name=\"publishers/qwen/models/qwen-image\",\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" model.deploy(\n",
|
||||
" endpoint=endpoint,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" system_labels={\"NOTEBOOK_NAME\": \"model_garden_pytorch_qwen_image.ipynb\"},\n",
|
||||
" )\n",
|
||||
" return model, endpoint\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"models[LABEL], endpoints[LABEL] = deploy_model(\n",
|
||||
" model_id=model_id,\n",
|
||||
" task=task,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"print(\"endpoint_name:\", endpoints[LABEL].name)\n",
|
||||
"\n",
|
||||
"# @markdown Click \"Show Code\" to see more details."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "zR7TwjzybU7U"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Predict Qwen Image (text-only input)\n",
|
||||
"\n",
|
||||
"# @markdown Once deployment succeeds, you can send text prompt and image to the endpoint.\n",
|
||||
"\n",
|
||||
"# @markdown Once deployment succeeds, you can send requests to the endpoint with prompts.\n",
|
||||
"\n",
|
||||
"text = \"A cat waving a sign that says hello world\" # @param {type: \"string\"}\n",
|
||||
"seed = 42 # @param {type:\"number\"}\n",
|
||||
"inference_steps = 50 # @param {type:\"number\"}\n",
|
||||
"\n",
|
||||
"instances = [{\"text\": text}]\n",
|
||||
"parameters = {\"seed\": seed, \"inference_steps\": inference_steps}\n",
|
||||
"\n",
|
||||
"response = endpoints[LABEL].predict(instances=instances, parameters=parameters)\n",
|
||||
"\n",
|
||||
"images = [\n",
|
||||
" common_util.base64_to_image(prediction[\"output\"])\n",
|
||||
" for prediction in response.predictions\n",
|
||||
"]\n",
|
||||
"common_util.image_grid([init_image, images[0]], rows=1, cols=2)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "CCln_dTCbYTF"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Predict Qwen Image Edit or Qwen Image Edit 2509 (text & image input)\n",
|
||||
"\n",
|
||||
"# @markdown Once deployment succeeds, you can send text prompt and image to the endpoint.\n",
|
||||
"\n",
|
||||
"# @markdown Once deployment succeeds, you can send requests to the endpoint with prompts.\n",
|
||||
"\n",
|
||||
"text = \"Add fire to the mountain\" # @param {type: \"string\"}\n",
|
||||
"image = \"https://huggingface.co/datasets/diffusers/diffusers-images-docs/resolve/main/mountain.png\" # @param {type: \"string\"}\n",
|
||||
"num_inference_steps = 50 # @param {type: \"number\"}\n",
|
||||
"\n",
|
||||
"init_image = common_util.download_image(image)\n",
|
||||
"instances = [\n",
|
||||
" {\"text\": text, \"image\": common_util.image_to_base64(init_image)},\n",
|
||||
"]\n",
|
||||
"parameters = {\"num_inference_steps\": num_inference_steps}\n",
|
||||
"response = endpoints[LABEL].predict(instances=instances, parameters=parameters)\n",
|
||||
"images = [\n",
|
||||
" common_util.base64_to_image(prediction[\"output\"])\n",
|
||||
" for prediction in response.predictions\n",
|
||||
"]\n",
|
||||
"common_util.image_grid([init_image, images[0]], rows=1, cols=2)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "1jL8IJJ1bz4_"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Clean up resources\n",
|
||||
"\n",
|
||||
"# @markdown Delete the experiment models and endpoints to recycle the resources\n",
|
||||
"# @markdown and avoid unnecessary continuous charges that may incur.\n",
|
||||
"\n",
|
||||
"# Undeploy model and delete endpoint.\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)\n",
|
||||
"\n",
|
||||
"# Delete models.\n",
|
||||
"for model in models.values():\n",
|
||||
" model.delete()"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "model_garden_pytorch_qwen_image.ipynb",
|
||||
"toc_visible": true
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
@@ -160,14 +160,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -324,6 +329,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -333,7 +350,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -357,7 +374,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-vllm-serve:20250506_0916_RC01\",\n",
|
||||
@@ -367,6 +384,25 @@
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -481,7 +517,7 @@
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
@@ -165,14 +165,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -329,6 +334,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -338,7 +355,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -362,7 +379,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/pytorch-inference.cu125.0-4.ubuntu2204.py310\",\n",
|
||||
@@ -372,6 +389,25 @@
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -481,7 +517,7 @@
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
@@ -103,7 +103,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
+1
-1
@@ -105,7 +105,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
+1
-1
@@ -110,7 +110,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
@@ -106,7 +106,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
+44
-8
@@ -165,14 +165,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -329,6 +334,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -338,7 +355,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -362,7 +379,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/vertex-ai/vertex-vision-model-garden-dockers/pytorch-diffusers-serve-opt:20240605_1400_RC00\",\n",
|
||||
@@ -372,6 +389,25 @@
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -496,7 +532,7 @@
|
||||
"\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
+44
-8
@@ -160,14 +160,19 @@
|
||||
"\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"PROJECT_ID = \"[your-project-id]\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"PROJECT_ID = \"\" # @param {type: \"string\", placeholder: \"[your-project-id]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"if not PROJECT_ID or PROJECT_ID == \"[your-project-id]\":\n",
|
||||
" PROJECT_ID = str(os.environ.get(\"GOOGLE_CLOUD_PROJECT\"))\n",
|
||||
"if not PROJECT_ID:\n",
|
||||
" PROJECT_ID = os.environ.get(\"GOOGLE_CLOUD_PROJECT\")\n",
|
||||
"\n",
|
||||
"REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"REGION = \"\" # @param {type: \"string\", placeholder: \"[your-region]\", isTemplate: true}\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)"
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ.get(\"GOOGLE_CLOUD_REGION\", \"us-central1\")\n",
|
||||
"\n",
|
||||
"vertexai.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"print(f\"Project: {PROJECT_ID}\\nLocation: {REGION}\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
@@ -324,6 +329,18 @@
|
||||
"use_dedicated_endpoint = True"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "S0q5fdbietBH"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoints = {}"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
@@ -333,7 +350,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_default\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
@@ -357,7 +374,7 @@
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"endpoint = model.deploy(\n",
|
||||
"endpoints[\"sdk_custom\"] = model.deploy(\n",
|
||||
" accept_eula=True,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
" serving_container_image_uri=\"us-docker.pkg.dev/deeplearning-platform-release/vertex-model-garden/pytorch-inference.cu125.0-4.ubuntu2204.py310\",\n",
|
||||
@@ -367,6 +384,25 @@
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "OCOHt9ivCdgA"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"if \"sdk_default\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_default\"]\n",
|
||||
" LABEL = \"sdk_default\"\n",
|
||||
"elif \"sdk_custom\" in endpoints:\n",
|
||||
" endpoint = endpoints[\"sdk_custom\"]\n",
|
||||
" LABEL = \"sdk_custom\"\n",
|
||||
"else:\n",
|
||||
" raise ValueError(\"No endpoint found. Create an endpoint.\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
@@ -523,7 +559,7 @@
|
||||
"# @title Delete the models and endpoints\n",
|
||||
"# @markdown Delete the endpoint.\n",
|
||||
"\n",
|
||||
"if endpoint:\n",
|
||||
"for endpoint in endpoints.values():\n",
|
||||
" endpoint.delete(force=True)"
|
||||
]
|
||||
}
|
||||
|
||||
@@ -0,0 +1,444 @@
|
||||
{
|
||||
"cells": [
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "w5feg0ieNxrp"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# Copyright 2025 Google LLC\n",
|
||||
"#\n",
|
||||
"# Licensed under the Apache License, Version 2.0 (the \"License\");\n",
|
||||
"# you may not use this file except in compliance with the License.\n",
|
||||
"# You may obtain a copy of the License at\n",
|
||||
"#\n",
|
||||
"# https://www.apache.org/licenses/LICENSE-2.0\n",
|
||||
"#\n",
|
||||
"# Unless required by applicable law or agreed to in writing, software\n",
|
||||
"# distributed under the License is distributed on an \"AS IS\" BASIS,\n",
|
||||
"# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.\n",
|
||||
"# See the License for the specific language governing permissions and\n",
|
||||
"# limitations under the License."
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "13rZccLtXENK"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Setup Google Cloud project\n",
|
||||
"# @markdown 1. [Make sure that billing is enabled for your project](https://cloud.google.com/billing/docs/how-to/modify-project).\n",
|
||||
"\n",
|
||||
"# @markdown 2. **[Optional]** Set region. If not set, the region will be set automatically according to Colab Enterprise environment.\n",
|
||||
"\n",
|
||||
"REGION = \"\" # @param {type:\"string\"}\n",
|
||||
"\n",
|
||||
"# @markdown 3. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
"# @markdown | a3-highgpu-4g | 4 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
"# @markdown | a3-highgpu-8g | 8 NVIDIA_H100_80GB | us-central1, europe-west4, us-west1, asia-southeast1 |\n",
|
||||
"\n",
|
||||
"import importlib\n",
|
||||
"import os\n",
|
||||
"\n",
|
||||
"from google.cloud import aiplatform\n",
|
||||
"\n",
|
||||
"# Import common utils\n",
|
||||
"if os.environ.get(\"VERTEX_PRODUCT\") != \"COLAB_ENTERPRISE\":\n",
|
||||
" ! pip install --upgrade tensorflow\n",
|
||||
"! git clone https://github.com/GoogleCloudPlatform/vertex-ai-samples.git\n",
|
||||
"\n",
|
||||
"common_util = importlib.import_module(\n",
|
||||
" \"vertex-ai-samples.notebooks.community.model_garden.docker_source_codes.notebook_util.common_util\"\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"# Setup GCP & VertexAI\n",
|
||||
"\n",
|
||||
"# Get the default cloud project id.\n",
|
||||
"PROJECT_ID = os.environ[\"GOOGLE_CLOUD_PROJECT\"]\n",
|
||||
"\n",
|
||||
"# Get the default region for launching jobs.\n",
|
||||
"if not REGION:\n",
|
||||
" REGION = os.environ[\"GOOGLE_CLOUD_REGION\"]\n",
|
||||
"\n",
|
||||
"# Enable the Vertex AI API and Compute Engine API, if not already.\n",
|
||||
"print(\"Enabling Vertex AI API and Compute Engine API.\")\n",
|
||||
"! gcloud services enable aiplatform.googleapis.com compute.googleapis.com\n",
|
||||
"\n",
|
||||
"# Initialize Vertex AI API.\n",
|
||||
"print(\"Initializing Vertex AI API.\")\n",
|
||||
"aiplatform.init(project=PROJECT_ID, location=REGION)\n",
|
||||
"\n",
|
||||
"# Gets the default SERVICE_ACCOUNT.\n",
|
||||
"shell_output = ! gcloud projects describe $PROJECT_ID\n",
|
||||
"project_number = shell_output[-1].split(\":\")[1].strip().replace(\"'\", \"\")\n",
|
||||
"SERVICE_ACCOUNT = f\"{project_number}-compute@developer.gserviceaccount.com\"\n",
|
||||
"print(\"Using this default Service Account:\", SERVICE_ACCOUNT)\n",
|
||||
"\n",
|
||||
"! gcloud config set project $PROJECT_ID\n",
|
||||
"import vertexai\n",
|
||||
"\n",
|
||||
"vertexai.init(\n",
|
||||
" project=PROJECT_ID,\n",
|
||||
" location=REGION,\n",
|
||||
")\n",
|
||||
"\n",
|
||||
"# Model configuration & utils\n",
|
||||
"SERVE_DOCKER_URI = \"us-docker.pkg.dev/vertex-ai-restricted/vertex-vision-model-garden-dockers/remote-sensing-serve-tf-gpu:latest\"\n",
|
||||
"MODEL_CONFIGS = {\n",
|
||||
" \"OWLVIT\": (\n",
|
||||
" \"earth-ai-imagery-owlvit-eap-10-2025\",\n",
|
||||
" \"publishers/google/models/remote_sensing_owlvit\",\n",
|
||||
" \"gs://vertex-model-garden-restricted-us/remote-sensing/OVD_OWL-ViT_So400M_RGB1008_V1\",\n",
|
||||
" ),\n",
|
||||
" \"MAMMUT\": (\n",
|
||||
" \"earth-ai-imagery-mammut-eap-10-2025\",\n",
|
||||
" \"publishers/google/models/remote_sensing_mammut\",\n",
|
||||
" \"gs://vertex-model-garden-restricted-us/remote-sensing/MaMMUT_So400M_RGB224_V1\",\n",
|
||||
" ),\n",
|
||||
"}\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def _get_platform_config(accelerator: str):\n",
|
||||
" \"\"\"Returns the platform config for the given accelerator type.\"\"\"\n",
|
||||
" if accelerator == \"CPU\":\n",
|
||||
" return \"cpu\", \"e2-standard-8\", None, None\n",
|
||||
" if accelerator == \"NVIDIA_L4\":\n",
|
||||
" return \"gpu\", \"g2-standard-8\", \"NVIDIA_L4\", 1\n",
|
||||
" if accelerator == \"NVIDIA_A100_80GB\":\n",
|
||||
" return \"gpu\", \"a2-ultragpu-1g\", \"NVIDIA_A100_80GB\", 1\n",
|
||||
" raise f\"Accelerator config is not supported {accelerator}\"\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def deploy(\n",
|
||||
" name: str,\n",
|
||||
" model_type: str,\n",
|
||||
" model_mode: str,\n",
|
||||
" platform: str,\n",
|
||||
" machine_type: str,\n",
|
||||
" accelerator_type: str,\n",
|
||||
" accelerator_count: int,\n",
|
||||
" service_account: str = None,\n",
|
||||
" use_dedicated_endpoint: bool = False,\n",
|
||||
" min_replica_count: int = 1,\n",
|
||||
" max_replica_count: int = 1,\n",
|
||||
") -> tuple[aiplatform.Endpoint, aiplatform.Model]:\n",
|
||||
" \"\"\"Deploys the model to a GPU endpoint with accelerator support.\n",
|
||||
"\n",
|
||||
" Args:\n",
|
||||
" name: the endpoint name to use for deployment.\n",
|
||||
" model_type: The model type to deploy, either MAMMUT or OWLVIT.\n",
|
||||
" model_mode: The model mode to deploy, e.g. COMBINED, IMAGE_ONLY or\n",
|
||||
" TEXT_ONLY.\n",
|
||||
" platform: The deployment platform, either \"cpu\" or \"gpu\".\n",
|
||||
" machine_type: The instance machine type to use, see\n",
|
||||
" https://cloud.google.com/compute/docs/machine-resource\n",
|
||||
" accelerator_type: The GPU type to deploy, defaults to NVIDIA_L4, see\n",
|
||||
" https://cloud.google.com/compute/docs/gpus\n",
|
||||
" accelerator_count: The number of GPUs (Accelerators) to use.\n",
|
||||
" \"\"\"\n",
|
||||
" model_id, model_name, model_path = MODEL_CONFIGS[model_type]\n",
|
||||
"\n",
|
||||
" if platform != \"cpu\":\n",
|
||||
" # Check quota only when using accelerators (GPU).\n",
|
||||
" common_util.check_quota(\n",
|
||||
" project_id=PROJECT_ID,\n",
|
||||
" region=REGION,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" is_for_training=False,\n",
|
||||
" )\n",
|
||||
"\n",
|
||||
" model = aiplatform.Model.upload(\n",
|
||||
" display_name=f\"{name}-model\",\n",
|
||||
" serving_container_image_uri=SERVE_DOCKER_URI,\n",
|
||||
" serving_container_ports=[8080],\n",
|
||||
" serving_container_predict_route=\"/predict\",\n",
|
||||
" serving_container_health_route=\"/health\",\n",
|
||||
" serving_container_environment_variables={\n",
|
||||
" \"DEPLOY_SOURCE\": \"notebook\",\n",
|
||||
" \"MODEL_ID\": model_id,\n",
|
||||
" \"MODEL_PATH\": model_path,\n",
|
||||
" \"MODEL_TYPE\": model_type,\n",
|
||||
" \"MODEL_MODE\": model_mode,\n",
|
||||
" \"PLATFORM\": platform,\n",
|
||||
" },\n",
|
||||
" model_garden_source_model_name=model_name,\n",
|
||||
" )\n",
|
||||
" endpoint = aiplatform.Endpoint.create(\n",
|
||||
" name, dedicated_endpoint_enabled=use_dedicated_endpoint\n",
|
||||
" )\n",
|
||||
" model.deploy(\n",
|
||||
" endpoint=endpoint,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" accelerator_type=accelerator_type,\n",
|
||||
" accelerator_count=accelerator_count,\n",
|
||||
" service_account=service_account,\n",
|
||||
" deploy_request_timeout=1800,\n",
|
||||
" enable_access_logging=True,\n",
|
||||
" min_replica_count=min_replica_count,\n",
|
||||
" max_replica_count=max_replica_count,\n",
|
||||
" sync=True,\n",
|
||||
" system_labels={\"NOTEBOOK_NAME\": \"model_garden_remote_sensing_deployment.ipynb\"},\n",
|
||||
" )\n",
|
||||
" return endpoint, model"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "LmC9mUmDSSUF"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Deploy model\n",
|
||||
"\n",
|
||||
"# @markdown **Choose an endpoint name (to be deployed)**\n",
|
||||
"ENDPOINT_NAME = \"mammut-combined-test-l4\" # @param { 'type' : 'string' }\n",
|
||||
"# @markdown **Specify the model type, variant mode and accelerator (platform) config.**\n",
|
||||
"MODEL_TYPE = \"MAMMUT\" # @param [\"MAMMUT\", \"OWLVIT\"]\n",
|
||||
"MODEL_MODE = \"COMBINED\" # @param [\"IMAGE_ONLY\", \"TEXT_ONLY\", \"COMBINED\"]\n",
|
||||
"ACCELERATOR = \"NVIDIA_L4\" # @param [\"CPU\", \"NVIDIA_L4\", \"NVIDIA_A100_80GB\"]\n",
|
||||
"# @markdown **Note:** For OWLVIT it is recommended to use a dedicated endpoint\n",
|
||||
"# @markdown as it increases the input size from 1.5 MB to 10MB.\n",
|
||||
"use_dedicated_endpoint = True # @param { 'type' : 'boolean' }\n",
|
||||
"platform, machine_type, acc_type, num_gpus = _get_platform_config(ACCELERATOR)\n",
|
||||
"\n",
|
||||
"endpoint, model = deploy(\n",
|
||||
" name=ENDPOINT_NAME,\n",
|
||||
" model_type=MODEL_TYPE,\n",
|
||||
" model_mode=MODEL_MODE,\n",
|
||||
" platform=platform,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
" accelerator_type=acc_type,\n",
|
||||
" accelerator_count=num_gpus,\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "markdown",
|
||||
"metadata": {
|
||||
"id": "yYGKMPJ_kAXZ"
|
||||
},
|
||||
"source": [
|
||||
"## Inference examples\n",
|
||||
"\n",
|
||||
"* Below there are 2 sets of samples: Object Detection (OWL-ViT) and Classification (MaMMUT), make sure that the deployed endpoint has the correct model type, otherwise you can override it below.\n",
|
||||
"\n",
|
||||
"* The samples are designed to work with the COMBINED mode, i.e. a variant\n",
|
||||
"of the model that can accept text, image or both as input.\n",
|
||||
"\n",
|
||||
"* Make sure you **cleanup unused resources** (endpoint) in the end. You can use\n",
|
||||
"the cleanup section above.\n",
|
||||
"\n",
|
||||
"* To get the best performance it is advised to use at least an **NVIDIA_L4 GPU**"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "mNTUQVO0j5Li"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Inference setup & utils.\n",
|
||||
"\n",
|
||||
"import base64\n",
|
||||
"import io\n",
|
||||
"\n",
|
||||
"from PIL import Image\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"def _b64_png(image: Image.Image) -> str:\n",
|
||||
" arr_bytes = io.BytesIO()\n",
|
||||
" image.save(arr_bytes, format=\"PNG\")\n",
|
||||
" return base64.b64encode(arr_bytes.getvalue()).decode(\"utf-8\")\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"# Download sample images\n",
|
||||
"!wget -O harbor.jpg https://mrsg.aegean.gr/images/uploads/it2zi0eidej4ql33llj.jpg\n",
|
||||
"!wget -O palace.jpeg https://www.spaceintelreport.com/wp-content/uploads/2021/05/Pleiades-NEO-US-Capitol-30cm.jpeg\n",
|
||||
"harbor_img = Image.open(\"harbor.jpg\")\n",
|
||||
"palace_img = Image.open(\"palace.jpeg\")"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "Jvdv-GLjKaWN"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @markdown **(Optional)** Override the endpoint (use a different one).\n",
|
||||
"# @markdown This is useful if you want to use a test a previously deployed model.\n",
|
||||
"# @markdown otherwise the inference samples will use the recently deployed model.\n",
|
||||
"ENDPOINT_ID = \"\" # @param { 'type': 'string' }\n",
|
||||
"use_dedicated_endpoint = True # @param { 'type' : 'boolean' }\n",
|
||||
"\n",
|
||||
"if ENDPOINT_ID:\n",
|
||||
" endpoint = aiplatform.Endpoint(ENDPOINT_ID)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "seGRCV5zHund"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Classification (MaMMUT) Inference Examples\n",
|
||||
"# Make sure that the deployed endpoint above is a MaMMUT model.\n",
|
||||
"\n",
|
||||
"# Call the image encoder with multiple images, batch_size is 1 by default.\n",
|
||||
"result = endpoint.predict(\n",
|
||||
" instances=[\n",
|
||||
" {\"image\": _b64_png(harbor_img)},\n",
|
||||
" {\"image\": _b64_png(palace_img)},\n",
|
||||
" ],\n",
|
||||
" parameters={\"batch_size\": 2},\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")\n",
|
||||
"print(\"Image encoder result, should contain 2 instances with embeddings.\")\n",
|
||||
"print(result)\n",
|
||||
"\n",
|
||||
"# Call text encoder with multiple input instances\n",
|
||||
"result = endpoint.predict(\n",
|
||||
" instances=[\n",
|
||||
" {\"text\": \"text\"},\n",
|
||||
" {\"text\": \"second text\"},\n",
|
||||
" {\"text\": \"this is a longer sentence\"},\n",
|
||||
" {\"text\": \"this is a another long sentence, longer than the previous\"},\n",
|
||||
" ],\n",
|
||||
" parameters={\"batch_size\": 2},\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")\n",
|
||||
"print(\"Text encoder result, should contain 2 instances with embeddings.\")\n",
|
||||
"print(result)\n",
|
||||
"\n",
|
||||
"# Call the zero-shot classification on the harbor & palace image, returns\n",
|
||||
"# similarity scores for each image/text, used\n",
|
||||
"labels = [\"airport\", \"palace\", \"harbor\", \"shipyard\", \"park\"]\n",
|
||||
"result = endpoint.predict(\n",
|
||||
" instances=[\n",
|
||||
" {\"image\": _b64_png(harbor_img), \"texts\": labels},\n",
|
||||
" {\"image\": _b64_png(palace_img), \"texts\": labels},\n",
|
||||
" ],\n",
|
||||
" parameters={\"batch_size\": 2},\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")\n",
|
||||
"print(\"Zero-shot classification result including similarity scores.\")\n",
|
||||
"print(result)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "4ALPx-WdjSBD"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Object Detection (OWL-ViT) Inference Examples\n",
|
||||
"\n",
|
||||
"# Make sure that the deployed endpoint above is OWL-ViT. It is advised to deploy\n",
|
||||
"# a dedicated endpoint for OWL-ViT as the input size is relatively large.\n",
|
||||
"\n",
|
||||
"# Call the image detection model, returns a list of object detections with\n",
|
||||
"# bounding boxes, scores & embeddings.\n",
|
||||
"result = endpoint.predict(\n",
|
||||
" instances=[\n",
|
||||
" {\"image\": _b64_png(harbor_img)},\n",
|
||||
" ],\n",
|
||||
" parameters={\"batch_size\": 1},\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")\n",
|
||||
"print(\"Image detection result, should contain 1 instance with object-level embeddings.\")\n",
|
||||
"print(result)\n",
|
||||
"\n",
|
||||
"# Call text encoder with multiple texts, returns text embeddings for each input.\n",
|
||||
"result = endpoint.predict(\n",
|
||||
" instances=[\n",
|
||||
" {\"text\": \"text\"},\n",
|
||||
" {\"text\": \"another text\"},\n",
|
||||
" {\"text\": \"this is a longer sentence\"},\n",
|
||||
" {\"text\": \"this is a very long sentence, even longer than above.\"},\n",
|
||||
" ],\n",
|
||||
" parameters={\"batch_size\": 4},\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")\n",
|
||||
"print(\"Text encoder result, should contain 4 instances with text embeddings.\")\n",
|
||||
"print(result)\n",
|
||||
"\n",
|
||||
"# Call the Open Vocabulary Detection mode with image/texts pairs, returns\n",
|
||||
"# object detections and labels, including bounding boxes, scores & embeddings.\n",
|
||||
"labels = [\"ship\", \"harbor\", \"dome\", \"building\", \"bridge\"]\n",
|
||||
"result = endpoint.predict(\n",
|
||||
" instances=[\n",
|
||||
" {\"image\": _b64_png(harbor_img), \"texts\": labels},\n",
|
||||
" {\"image\": _b64_png(palace_img), \"texts\": labels},\n",
|
||||
" ],\n",
|
||||
" parameters={\n",
|
||||
" \"batch_size\": 4,\n",
|
||||
" # Return only the top 100 detections based on objectness_score.\n",
|
||||
" \"top_k_objects\": 100,\n",
|
||||
" # Discard the object/text embeddings, overall reduces the output size.\n",
|
||||
" \"keep_embeddings\": False,\n",
|
||||
" },\n",
|
||||
" use_dedicated_endpoint=use_dedicated_endpoint,\n",
|
||||
")\n",
|
||||
"print(\"Object detection result, including detection results with 100 objects each.\")\n",
|
||||
"print(result)"
|
||||
]
|
||||
},
|
||||
{
|
||||
"cell_type": "code",
|
||||
"execution_count": null,
|
||||
"metadata": {
|
||||
"cellView": "form",
|
||||
"id": "quCzxT0WB_Ts"
|
||||
},
|
||||
"outputs": [],
|
||||
"source": [
|
||||
"# @title Cleanup Resources\n",
|
||||
"# @markdown Delete the experiment models and endpoints to recycle the resources\n",
|
||||
"# @markdown and avoid unnecessary continuous charges that may incur.\n",
|
||||
"\n",
|
||||
"endpoint.delete(force=True)\n",
|
||||
"model.delete()"
|
||||
]
|
||||
}
|
||||
],
|
||||
"metadata": {
|
||||
"colab": {
|
||||
"name": "model_garden_remote_sensing_deployment.ipynb",
|
||||
"toc_visible": true
|
||||
},
|
||||
"kernelspec": {
|
||||
"display_name": "Python 3",
|
||||
"name": "python3"
|
||||
}
|
||||
},
|
||||
"nbformat": 4,
|
||||
"nbformat_minor": 0
|
||||
}
|
||||
@@ -112,7 +112,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
|
||||
+2
-6
@@ -108,7 +108,7 @@
|
||||
"\n",
|
||||
"# @markdown 4. If you want to run predictions with A100 80GB or H100 GPUs, we recommend using the regions listed below. **NOTE:** Make sure you have associated quota in selected regions. Click the links to see your current quota for each GPU type: [Nvidia A100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_a100_80gb_gpus), [Nvidia H100 80GB](https://console.cloud.google.com/iam-admin/quotas?metric=aiplatform.googleapis.com%2Fcustom_model_serving_nvidia_h100_gpus). You can request for quota following the instructions at [\"Request a higher quota\"](https://cloud.google.com/docs/quota/view-manage#requesting_higher_quota).\n",
|
||||
"\n",
|
||||
"# @markdown > | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | Machine Type | Accelerator Type | Recommended Regions |\n",
|
||||
"# @markdown | ----------- | ----------- | ----------- |\n",
|
||||
"# @markdown | a2-ultragpu-1g | 1 NVIDIA_A100_80GB | us-central1, us-east4, europe-west4, asia-southeast1, us-east4 |\n",
|
||||
"# @markdown | a3-highgpu-2g | 2 NVIDIA_H100_80GB | us-west1, asia-southeast1, europe-west4 |\n",
|
||||
@@ -204,7 +204,6 @@
|
||||
"\n",
|
||||
"VERTEX_AI_MODEL_GARDEN_TIMESFM = \"gs://vertex-model-garden-public-us/timesfm\" # @param {type:\"string\", isTemplate:true} [\"gs://vertex-model-garden-public-us/timesfm\", \"gs://vertex-model-garden-public-eu/timesfm\", \"gs://vertex-model-garden-public-asia/timesfm\"]\n",
|
||||
"MODEL_VARIANT = \"timesfm-2.0-500m-jax\" # @param [\"timesfm-2.0-500m-jax\"]\n",
|
||||
"hf_model_id = \"google/\" + MODEL_VARIANT\n",
|
||||
"\n",
|
||||
"\n",
|
||||
"print(\n",
|
||||
@@ -320,7 +319,6 @@
|
||||
"\n",
|
||||
"def deploy_model(\n",
|
||||
" model_name: str,\n",
|
||||
" base_model_id: str,\n",
|
||||
" checkpoint_path: str,\n",
|
||||
" horizon: str,\n",
|
||||
" machine_type: str = \"g2-standard-8\",\n",
|
||||
@@ -347,13 +345,12 @@
|
||||
"\n",
|
||||
" model = aiplatform.Model.upload(\n",
|
||||
" display_name=model_name_with_time,\n",
|
||||
" artifact_uri=checkpoint_path,\n",
|
||||
" serving_container_image_uri=SERVE_DOCKER_URI,\n",
|
||||
" serving_container_ports=[8080],\n",
|
||||
" serving_container_predict_route=\"/predict\",\n",
|
||||
" serving_container_health_route=\"/health\",\n",
|
||||
" serving_container_environment_variables={\n",
|
||||
" \"MODEL_ID\": base_model_id,\n",
|
||||
" \"MODEL_ID\": checkpoint_path,\n",
|
||||
" \"DEPLOY_SOURCE\": deploy_source,\n",
|
||||
" \"TIMESFM_HORIZON\": str(horizon),\n",
|
||||
" \"TIMESFM_BACKEND\": timesfm_backend,\n",
|
||||
@@ -385,7 +382,6 @@
|
||||
"\n",
|
||||
"models[\"timesfm\"], endpoints[\"timesfm\"] = deploy_model(\n",
|
||||
" model_name=f\"timesfm-{MODEL_VARIANT}\",\n",
|
||||
" base_model_id=hf_model_id,\n",
|
||||
" checkpoint_path=checkpoint_path,\n",
|
||||
" horizon=horizon,\n",
|
||||
" machine_type=machine_type,\n",
|
||||
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user